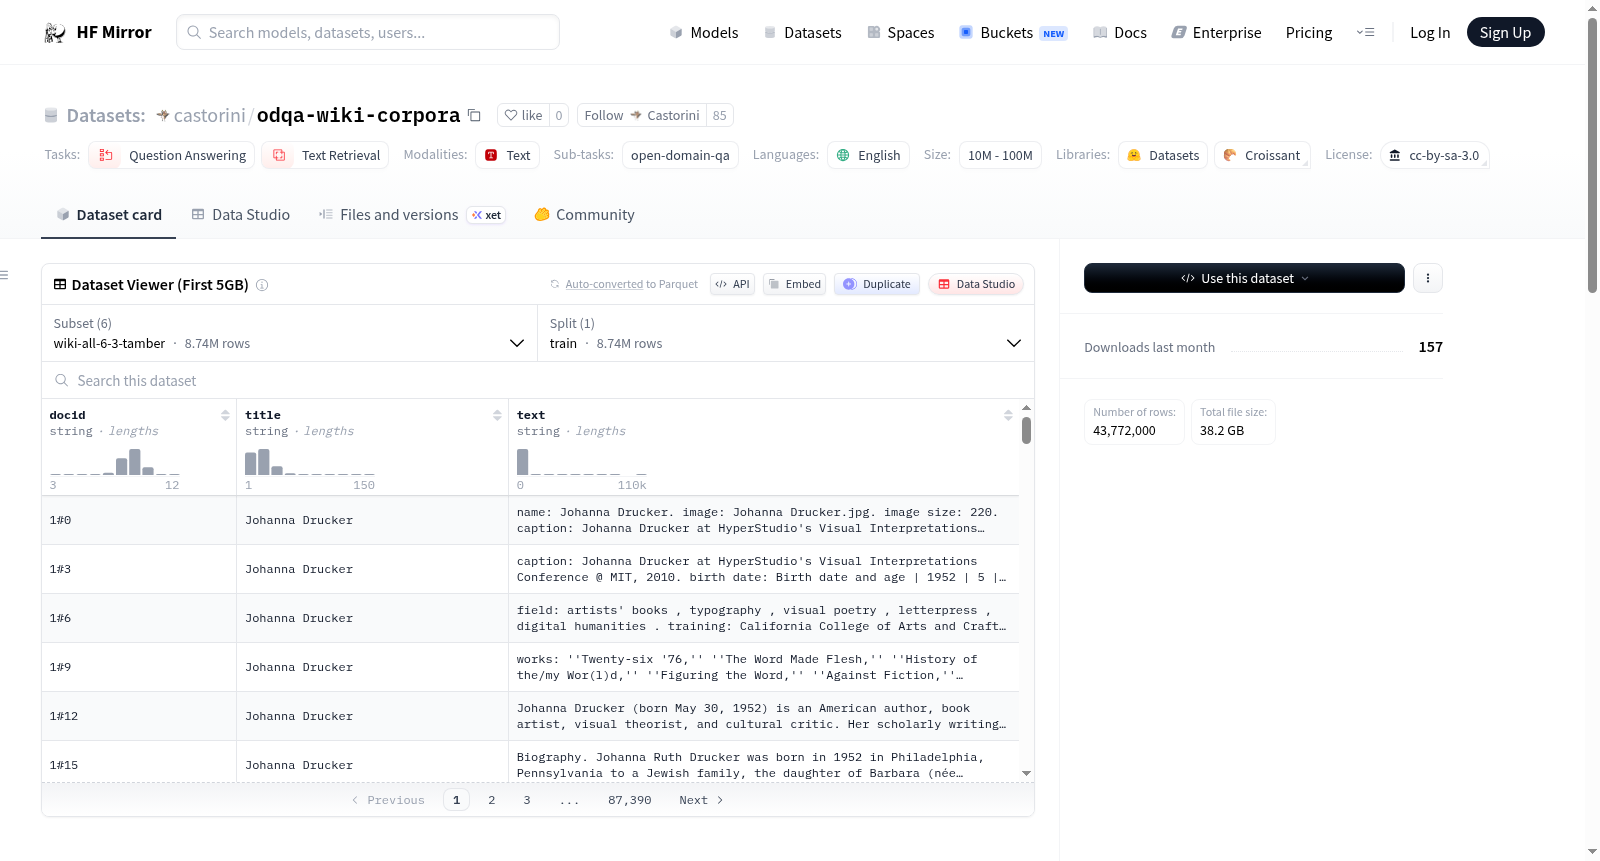
castorini/odqa-wiki-corpora
收藏资源简介:
--- annotations_creators: - no-annotation language: - en language_creators: [] license: - cc-by-sa-3.0 multilinguality: - monolingual pretty_name: Open-Domain Question Answering Wikipedia Corpora size_categories: [] source_datasets: [] tags: [] task_categories: - question-answering - text-retrieval task_ids: - open-domain-qa --- # Dataset Card for Open-Domain Question Answering Wikipedia Corpora ## Table of Contents - [Table of Contents](#table-of-contents) - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Dataset Structure](#dataset-structure) - [Data Fields](#data-fields) - [Data Splits](#data-splits) - [Dataset Creation](#dataset-creation) - [Source Data](#source-data) ## Dataset Description ### Dataset Summary The Wikipedia corpus variants provided can serve as knowledge sources for question-answering systems based on a retriever–reader pipeline. These corpus variants and their corresponding experiments are described further in the paper entitled: > Pre-Processing Matters! Improved Wikipedia Corpora for Open-Domain Question Answering. ## Dataset Structure ### Data Fields The dataset consists of passages that have been segmented from Wikipedia articles. For each passage, the following fields are provided - ```docid```: The passage id in the format of (X#Y) where passages from the same article share the same X, but Y denotes the segment id within the article - ```title```: The title of the article from where the passage comes - ```text```: The text content of the passage ### Data Splits There are 6 corpus variants in total - ```wiki-text-100w-karpukhin```: The original DPR Wikipedia corpus with non-overlapping passages, each 100 words long, from Karpukhin et al., > Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, Wen-tau Yih. [Dense Passage Retrieval for Open-Domain Question Answering](https://www.aclweb.org/anthology/2020.emnlp-main.550/). _Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP)_, pages 6769-6781, 2020. - ```wiki-text-100w-tamber```: Our replication of the above corpus - ```wiki-text-6-3-tamber```: A corpus similar to above i.e. without tables, infoboxes, and lists. Segmentation is done differently, with a passage size of 6 sentences and a stride of 3 sentences. Note, this means that passages are overlapped. - ```wiki-text-8-4-tamber```: Like wiki-text-6-3, but with a passage size of 8 sentences and a stride of 4 sentences. - ```wiki-all-6-3-tamber```: A corpus with tables, infoboxes, and lists included with a passage size of 6 sentences and a stride of 3 sentences. - ```wiki-all-8-4-tamber```: Like wiki-all-6-3, but with a passage size of 8 sentences and a stride of 4 sentences. ## Dataset Creation ### Source Data #### Initial Data Collection and Normalization We start with downloading the full December 20, 2018 Wikipedia XML dump: ```enwiki-20181220-pages-articles.xml``` from the Internet Archive: https://archive.org/details/enwiki-20181220. This is then Pre-processed by WikiExtractor: https://github.com/attardi/wikiextractor (making sure to modify the code to include lists as desired and replacing any tables with the string "TABLETOREPLACE") and DrQA: https://github.com/facebookresearch/DrQA/tree/main/scripts/retriever (again making sure to modify the code to not remove lists as desired). We then apply the [pre-processing script]((https://github.com/castorini/pyserini/blob/master/docs/experiments-wiki-corpora.md)) we make available in [Pyserini](https://github.com/castorini/pyserini) to generate the different corpus variants.
annotations_creators: - 无标注 language: - 英语 language_creators: [] license: - cc-by-sa-3.0 multilinguality: - 单语言 pretty_name: 开放域问答(Open-Domain Question Answering)维基百科语料库 size_categories: [] source_datasets: [] tags: [] task_categories: - 问答 - 文本检索 task_ids: - 开放域问答(Open-Domain Question Answering) # 开放域问答维基百科语料库数据集卡片 ## 目录 - [目录](#目录) - [数据集描述](#数据集描述) - [数据集概述](#数据集概述) - [数据集结构](#数据集结构) - [数据字段](#数据字段) - [数据划分](#数据划分) - [数据集创建](#数据集创建) - [源数据](#源数据) ## 数据集描述 ### 数据集概述 本数据集提供的维基百科语料库变体可作为基于检索器-阅读器流水线的问答系统的知识来源。这些语料库变体及其对应实验在以下论文中有详细阐述: > 《预处理至关重要!面向开放域问答的改进型维基百科语料库》 ## 数据集结构 ### 数据字段 本数据集包含从维基百科文章中分割得到的段落。每个段落包含以下字段: - `docid`: 段落标识符,格式为(X#Y),同一文章的段落共享相同的X值,Y代表该文章内的段落分段编号 - `title`: 该段落所属文章的标题 - `text`: 段落的文本内容 ### 数据划分 本数据集共包含6种语料库变体: - `wiki-text-100w-karpukhin`: 源自Karpukhin等人研究的原始稠密段落检索(Dense Passage Retrieval, DPR)维基百科语料库,采用非重叠段落分割,每段长度为100词。 > Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, Wen-tau Yih. [稠密段落检索用于开放域问答](https://www.aclweb.org/anthology/2020.emnlp-main.550/). _2020年自然语言处理经验方法会议(EMNLP 2020)论文集_,第6769-6781页,2020年。 - `wiki-text-100w-tamber`: 本团队对上述语料库的复现版本 - `wiki-text-6-3-tamber`: 与上述语料库类似的版本,不含表格、信息框与列表。采用新的分割方式,段落长度为6个句子,步长为3个句子。请注意,这意味着段落存在重叠。 - `wiki-text-8-4-tamber`: 与`wiki-text-6-3-tamber`类似,但段落长度为8个句子,步长为4个句子。 - `wiki-all-6-3-tamber`: 包含表格、信息框与列表的语料库,段落长度为6个句子,步长为3个句子。 - `wiki-all-8-4-tamber`: 与`wiki-all-6-3-tamber`类似,但段落长度为8个句子,步长为4个句子。 ## 数据集创建 ### 源数据 #### 原始数据收集与标准化 我们首先从互联网档案馆(Internet Archive)下载2018年12月20日的完整维基百科XML转储文件:`enwiki-20181220-pages-articles.xml`,下载地址为https://archive.org/details/enwiki-20181220。随后使用WikiExtractor(https://github.com/attardi/wikiextractor)进行预处理(需修改代码以保留列表,并将所有表格替换为字符串"TABLETOREPLACE"),并使用DrQA(https://github.com/facebookresearch/DrQA/tree/main/scripts/retriever)进行后续处理(需修改代码以保留列表)。 随后我们使用[Pyserini](https://github.com/castorini/pyserini)中提供的预处理脚本(https://github.com/castorini/pyserini/blob/master/docs/experiments-wiki-corpora.md)生成不同的语料库变体。
数据集概述
数据集名称
- 名称: Open-Domain Question Answering Wikipedia Corpora
- 别名: Open-Domain QA Wikipedia Corpora
语言与许可
- 语言: 英语 (en)
- 许可: CC-BY-SA-3.0
多语言性
- 类型: 单语种
任务类别
- 任务类别:
- 问答
- 文本检索
- 具体任务: 开放领域问答 (open-domain-qa)
数据集结构
- 数据字段:
docid: 文章ID,格式为(X#Y),其中X表示同一文章的ID,Y表示文章内的段落ID。title: 文章标题。text: 段落文本内容。
- 数据分割:
wiki-text-100w-karpukhin: 原始DPR维基百科语料库,非重叠段落,每段100字。wiki-text-100w-tamber: 上述语料库的复制。wiki-text-6-3-tamber: 类似语料库,不包含表格、信息框和列表,段落大小为6句,步长为3句,段落重叠。wiki-text-8-4-tamber: 类似wiki-text-6-3-tamber,段落大小为8句,步长为4句。wiki-all-6-3-tamber: 包含表格、信息框和列表的语料库,段落大小为6句,步长为3句。wiki-all-8-4-tamber: 类似wiki-all-6-3-tamber,段落大小为8句,步长为4句。
数据集创建
- 源数据:
- 初始数据收集: 使用2018年12月20日的维基百科XML转储
enwiki-20181220-pages-articles.xml。 - 预处理工具: WikiExtractor 和 DrQA。
- 预处理步骤: 使用Pyserini提供的预处理脚本生成不同的语料库变体。
- 初始数据收集: 使用2018年12月20日的维基百科XML转储