fffoivos/hplt-greek-ge8-no-mt-clean60-wave4
收藏资源简介:
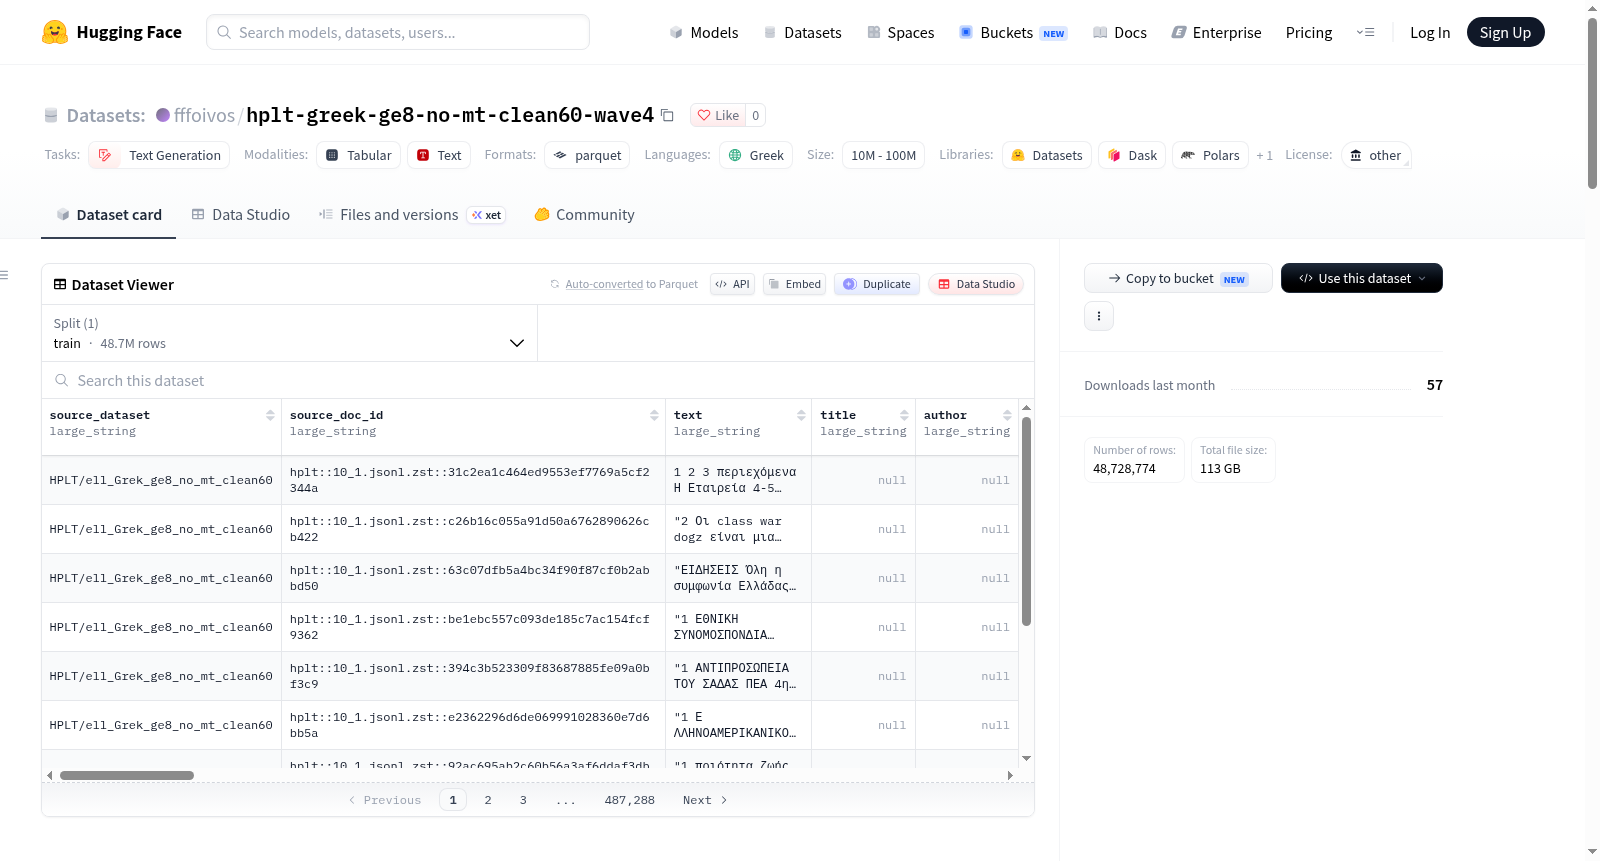
--- language: - el license: other pretty_name: HPLT Greek GE8 No-MT Clean60 Wave4 task_categories: - text-generation size_categories: - 10M<n<100M configs: - config_name: default data_files: - split: train path: data/*.parquet --- # HPLT Greek GE8 No-MT Clean60 Wave4 A standalone release of the filtered Greek HPLT slice used in the GlossAPI Greek pretraining corpus. It contains the full `HPLT/ell_Grek_ge8_no_mt_clean60` source after the Wave4 re-cleaning and normalization pass. ## Snapshot - Rows: `48728774` - Data parquet files: `250` - Source dataset value: `HPLT/ell_Grek_ge8_no_mt_clean60` - Quality bins: `8`, `9`, `10` - MT/register filtering: applied before this release - Cleaner gate: `greek_badness_score <= 60` before Wave4 re-cleaning ## Token Count With ModernGreek-148k This full HPLT slice was tokenized with [`fffoivos/apertus-tokenizer-extension`](https://huggingface.co/fffoivos/apertus-tokenizer-extension)'s selected `ModernGreek-148k` tokenizer: - tokenizer vocab: `148480` tokens (`131072` Apertus base + `17408` modern Greek extension tokens) - tokenizer SHA-256: `358ae3f29ac17c99769d6d437339e28657d5fcaed3486f8550feed3d6adfc394` - rows/documents: `48,728,774` - tokens without special tokens/EOD: `44,195,950,025` - tokens with one EOD per row: `44,244,678,799` - average tokens per row without EOD: `906.9785` The count was produced on Clariden with a CPU-only `xfer` job (`2399397`) and uses `add_special_tokens=false`. ## Quality Bin Distribution | quality_bin | row_count | file_count | share_of_rows_percent | | --- | --- | --- | --- | | 8 | 38919919 | 199 | 79.87 | | 9 | 9709678 | 50 | 19.93 | | 10 | 99177 | 1 | 0.2 | ## Columns - `source_dataset` - `source_doc_id` - `text` - `title` - `author` - `source_metadata_json` - `is_historical_or_polytonic` - `contains_math` - `contains_latex` - `greek_percentage` - `latin_percentage` - `polytonic_ratio` - `table_ratio` - `greek_badness_score` - `len_greek` - `mojibake_badness_score` - `needs_ocr` - `is_empty` - `filter` - `ocr_success` - `quality_method` - `reevaluated_at` - `content_chars_kept` - `chars_dropped_by_line_drop` - `chars_dropped_by_normalization` - `chars_dropped_by_per_char_filter` - `lines_dropped_by_cleaner` - `marker_chars_passthrough` - `marker_chars_added` - `charset_greek_ratio` - `charset_moji_ratio` - `charset_punct_ratio` - `mojibake_noise_ratio` - `rule_a_match_count` - `rule_b_match_count` - `residue_line_drop_count` - `phase_a_fallback_reason` - `phase_a_dialect_ambiguous_input` - `cleaner_chars_before` - `cleaner_chars_after` ## Intended Use - Greek web-text pretraining experiments - HPLT-only baselines - Mixture construction with curated GlossAPI sources - Tokenizer and cleaning analysis over a large filtered web corpus ## Notes - This dataset is intentionally HPLT-only; the broader mixed corpus lives at `fffoivos/glossapi-greek-nanochat-pretraining-dataset`. - Source licensing remains governed by the upstream HPLT release.
HPLT Greek GE8 No-MT Clean60 Wave4 is a standalone release of the filtered Greek HPLT slice used in the GlossAPI Greek pretraining corpus. It contains the full HPLT/ell_Grek_ge8_no_mt_clean60 source after the Wave4 re-cleaning and normalization pass. The dataset has undergone quality filtering (MT/register filtering applied, with a cleaner gate of greek_badness_score <= 60 before Wave4 re-cleaning), comprising approximately 48.7 million rows across 250 Parquet files, distributed across quality bins 8, 9, and 10. Tokenized with the ModernGreek-148k tokenizer, it totals around 44.2 billion tokens. Intended uses include Greek web-text pretraining experiments, HPLT-only baselines, mixture construction with curated GlossAPI sources, and tokenizer and cleaning analysis over a large filtered web corpus. This dataset is intentionally HPLT-only, with source licensing governed by the upstream HPLT release.