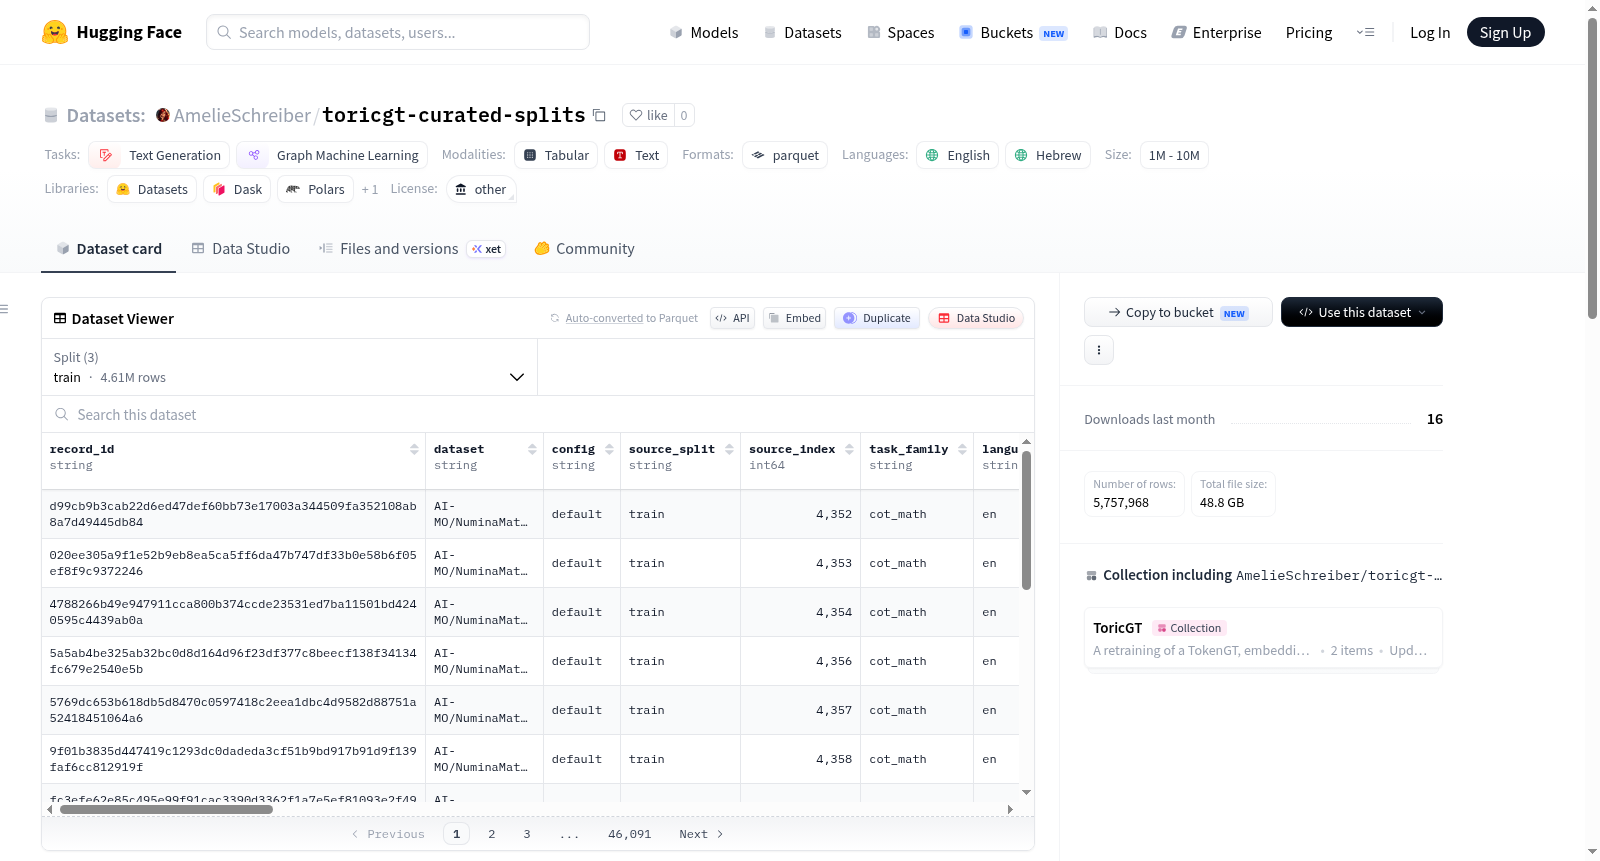
toricgt-curated-splits
收藏资源简介:
ToricGT Curated Graph Reasoning Splits 是一个为 ToricGT 项目精选的数据集,专门设计用于图推理任务。该数据集包含从 Sefaria 和 UniMorph 来源收集的希伯来语/犹太文本记录以及英语文本,以 Parquet 文件格式提供,包括训练集、验证集和测试集的分割文件,以及元数据文件如 manifest.json 和 split_report.json。数据集总规模为 5,790,736 行,其中训练集 4,633,582 行、验证集 578,319 行、测试集 578,835 行。希伯来语文本部分保留了上游的元音点标注(niqqud),其中带点希伯来语行 2,868 行,无点上游希伯来语行 3,561,888 行;用户可通过 quality_flags_json 中的 has_hebrew_without_niqqud 标志过滤无点文本。该数据集适用于文本生成和图机器学习任务,但需注意其为混合来源的研究数据集,使用时需保留归属列并审查上游许可证,特别是 GPL 许可和共享类似条款的源应在下游发布时单独处理。
ToricGT Curated Graph Reasoning Splits is a curated dataset for the ToricGT project, specifically designed for graph reasoning tasks. It includes Hebrew/Jewish text records collected from Sefaria and UniMorph sources, along with English text, provided in Parquet file format with splits for training, validation, and test sets, as well as metadata files such as manifest.json and split_report.json. The total dataset size is 5,790,736 rows, comprising 4,633,582 rows for training, 578,319 rows for validation, and 578,835 rows for testing. The Hebrew text portion retains upstream vowel point annotations (niqqud), with 2,886 rows of pointed Hebrew and 3,561,888 rows of unpointed upstream Hebrew; users can filter unpointed text via the has_hebrew_without_niqqud flag in quality_flags_json. This dataset is suitable for text generation and graph machine learning tasks, but note that it is a mixed-source research dataset, requiring attribution columns to be retained and upstream licenses reviewed, particularly for GPL-licensed or similarly shared sources that should be handled separately in downstream releases.
数据集概述:ToricGT Curated Graph Reasoning Splits
数据集名称:ToricGT Curated Graph Reasoning Splits
来源仓库:AmelieSchreiber/toricgt-curated-splits
任务类型
- 文本生成(text-generation)
- 图机器学习(graph-ml)
语言
- 英语(en)
- 希伯来语(he)
数据集构成与规模
- 总行数:5,790,736
- 训练集:4,633,582 行
- 验证集:578,319 行
- 测试集:578,835 行
文件内容
包含以下文件(均为本地生成的 Parquet 文件和元数据):
train.parquetvalidation.parquettest.parquetall.parquet(若使用了--include-all参数)manifest.jsonsplit_report.jsonsplit_report.mdniqqud_report.json
每条记录保留来源数据集、许可信息、数据划分、哈希值及图 JSON 字段,以便审计。
希伯来语元音点(Niqqud)处理策略
- 希伯来语/犹太教文本来源:Sefaria 和 UniMorph Hebrew 源。
- 上游数据中已有的元音点被保留,但默认不会为未加元音点的文本合成元音。
- 希伯来语行数:3,564,756
- 带元音点的希伯来语行:2,868
- 不带元音点的上游希伯来语行:3,561,888
- 严格需要带元音点的任务,应在
quality_flags_json中过滤掉has_hebrew_without_niqqud=true的行。
许可说明
- 许可证类型:其他(other)
- 本数据集为多源研究数据集,使用时应保留归因列,并在模型分发前审阅上游许可证。
- GPL 许可证或类似“相同方式共享”许可的来源数据,在涉及下游分发条款时应单独处理。