kaushik-harsh-99/Indian-legal-data-v2
收藏资源简介:
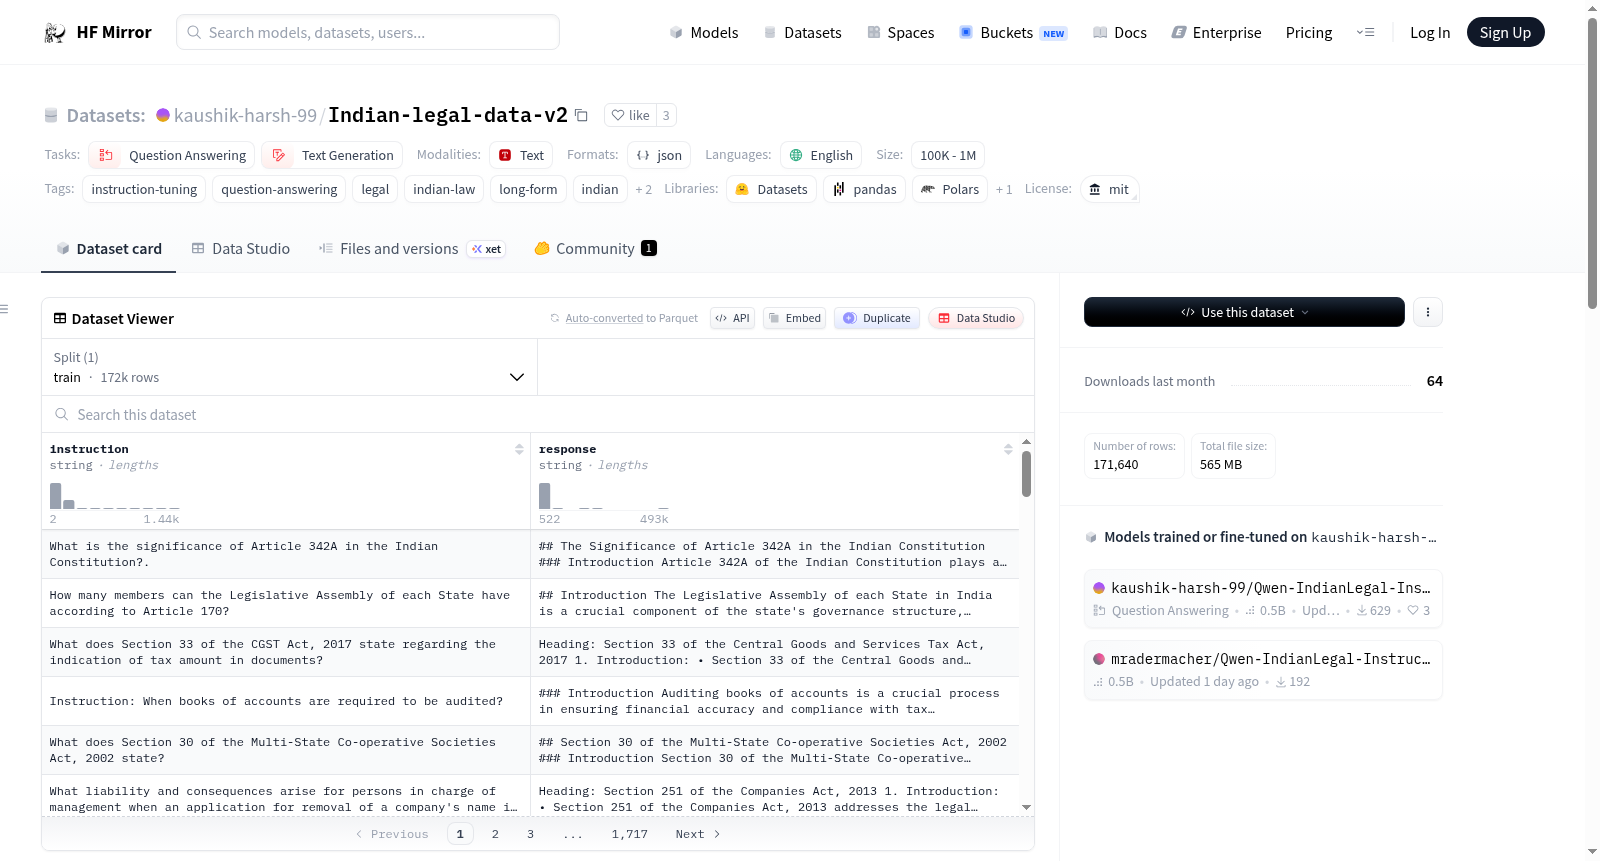
该数据集包含从印度法律文本中提取的高质量指令-响应对,主要关注法规解释和结构化法律说明。版本2在规模和质���上较版本1有显著升级,样本数量从33,077增加到171,640。该数据集专为语言模型的指令调优设计,强调清晰性、结构性和法律推理模式。任务类型为指令调优/法律问答,领域为印度法律(法案、章节、条款),语言为英语,格式为JSONL,主要用途是为法律推理和结构化答案生成微调大型语言模型。
This dataset contains high-quality instruction–response pairs derived from Indian legal texts, primarily focusing on statutory interpretation and structured legal explanations. Version 2 represents a significant scale and quality upgrade over v1, with samples increasing from 33,077 to 171,640. The dataset is designed specifically for instruction tuning of language models, emphasizing clarity, structure, and legal reasoning patterns. Task Type is Instruction Tuning / Legal QA, Domain is Indian Law (Acts, sections, provisions), Language is English, Format is JSONL, and Primary Use Case is Fine-tuning LLMs for legal reasoning and structured answer generation.