swan07/authorship-verification
收藏资源简介:
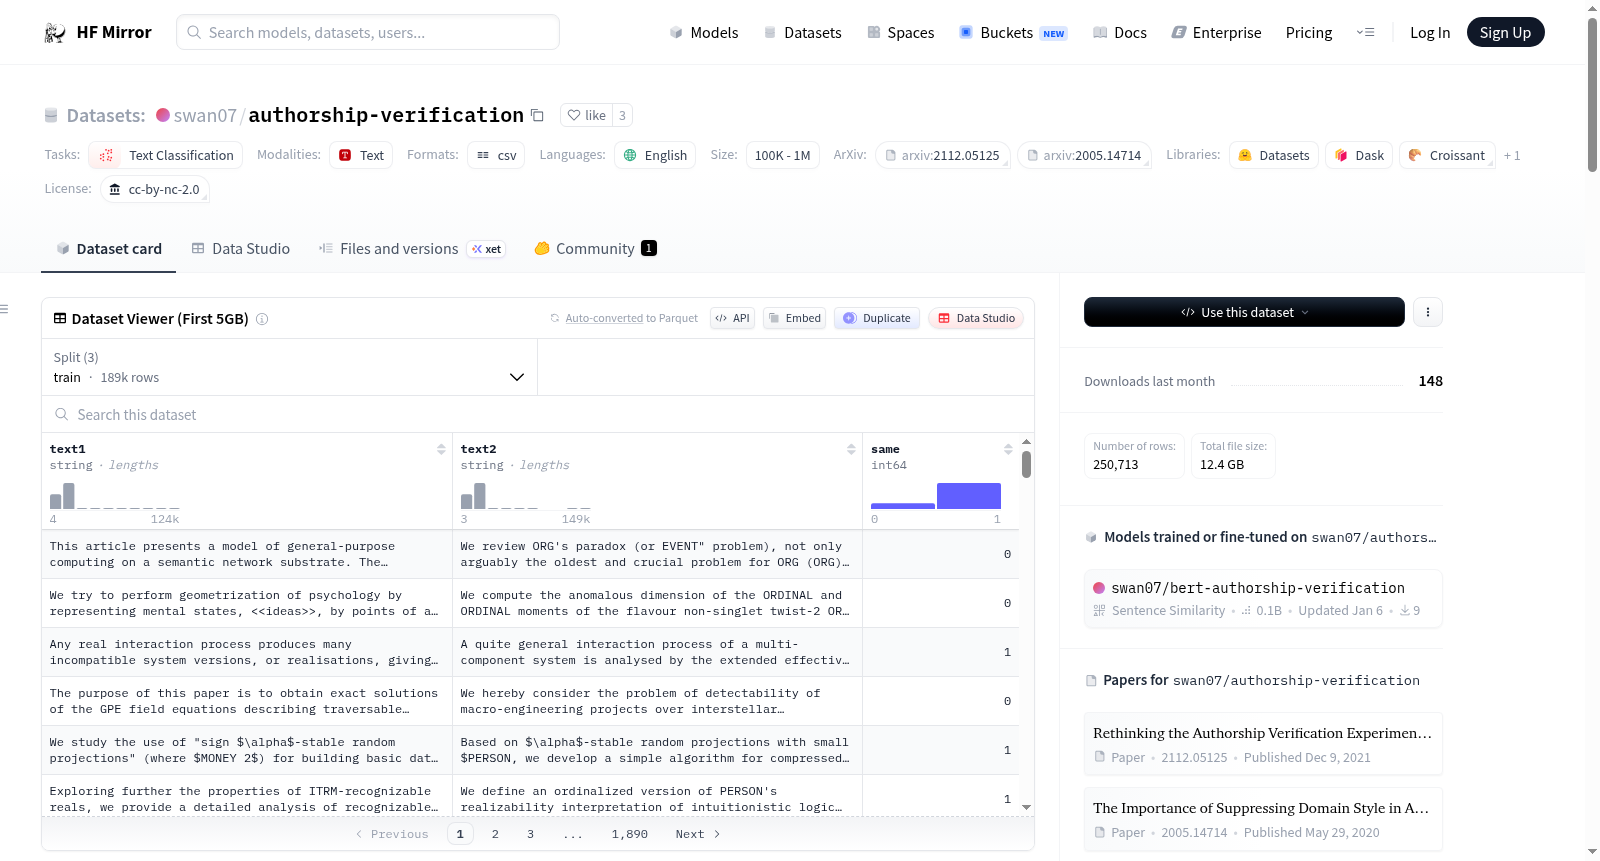
该数据集由12个经过清理和修改的开源作者验证和归属数据集组成,包括Reuters50、The Blog Authorship Corpus、Victorian、arXiv、DarkReddit、British Academic Written English (BAWE)、IMDB62、PAN11、PAN13、PAN14、PAN15和PAN20。这些数据集被清理后,命名实体被替换为它们的通用类型(除了PAN14、PAN15和PAN20),并重新结构化为包含|text1|text2|same|列的数据框,其中same列的值为0表示两个文本的作者不同,值为1表示作者相同。数据集被分为训练集、测试集和验证集,如果原始数据集提供了分割方式,则保留原始分割方式,否则使用0.7:0.15:0.15的比例进行分割。
The dataset is composed of 12 cleaned, modified, open source authorship verification and attribution datasets, including Reuters50, The Blog Authorship Corpus, Victorian, arXiv, DarkReddit, British Academic Written English (BAWE), IMDB62, PAN11, PAN13, PAN14, PAN15, and PAN20. These datasets were cleaned, with named entities replaced by their general types (except for PAN14, PAN15, and PAN20), and restructured into dataframes with columns |text1|text2|same|, where a value of 0 in the same column indicates that the two texts have different authors, while a value of 1 indicates that the two texts have the same author. The datasets were split into train/test/verification sets, retaining the original splits if provided, otherwise using a 0.7:0.15:0.15 split ratio.
数据集概述
基本信息
- 许可证: CC BY-NC-2.0
- 任务类别: 文本分类
- 语言: 英语
数据集详情
- 数据集名称: 未明确提及,用于作者验证的数据集。
- 数据集组成: 由12个经过清理和修改的开源作者验证和归属数据集组成。
数据集列表
-
Reuters50
- 作者: Liu, Zhi
- 年份: 2011
- 来源: UCI Machine Learning Repository
- 许可证: CC BY 4.0
-
The Blog Authorship Corpus
- 作者: J. Schler, M. Koppel, S. Argamon, J. Pennebaker
- 年份: 2006
- 来源: 2006 AAAI Spring Symposium on Computational Approaches for Analyzing Weblogs
- 许可证: 非商业研究用途
-
Victorian
- 作者: Gungor, Abdulmecit
- 年份: 2018
- 来源: UCI Machine Learning Repository
- 许可证: CC BY 4.0
-
arXiv
- 作者: Moreo, Alejandro
- 年份: 2022
- 来源: Zenodo
- 许可证: CC BY 4.0
-
DarkReddit
- 作者: Andrei Manolache, Florin Brad, Elena Burceanu, Antonio Barbalau, Radu Tudor Ionescu, Marius Popescu
- 年份: 2021
- 来源: arXiv
- 许可证: 未披露
-
British Academic Written English (BAWE)
- 作者: Nesi, Hilary, Gardner, Sheena, Thompson, Paul, Wickens, Paul
- 年份: 2008
- 来源: Oxford Text Archive
- 许可证: CC BY-NC-SA 3.0
-
IMDB62
- 作者: Seroussi, Yanir, Zukerman, Ingrid, Bohnert, Fabian
- 年份: 2014
- 来源: Computational Linguistics
- 许可证: 未披露
-
PAN11
- 作者: Argamon, Shlomo, Juola, Patrick
- 年份: 2011
- 来源: Zenodo
- 许可证: 未披露
-
PAN13
- 作者: Juola, Patrick, Stamatatos, Efstathios
- 年份: 2013
- 来源: Zenodo
- 许可证: 未披露
-
PAN14
- 作者: Stamatatos, Efstathios, Daelemans, Walter, Verhoeven, Ben, Potthast, Martin, Stein, Benno, Juola, Patrick, A. Sanchez-Perez, Miguel, Barrón-Cedeño, Alberto
- 年份: 2014
- 来源: Zenodo
- 许可证: 未披露
-
PAN15
- 作者: Stamatatos, Efstathios, Daelemans, Walter, Verhoeven, Ben, Juola, Patrick, López-López, Aurelio, Potthast, Martin, Stein, Benno
- 年份: 2015
- 来源: Zenodo
- 许可证: 未披露
-
PAN20
- 作者: Sebastian Bischoff, Niklas Deckers, Marcel Schliebs, Ben Thies, Matthias Hagen, Efstathios Stamatatos, Benno Stein, Martin Potthast
- 年份: 2020
- 来源: arXiv
- 许可证: 未披露
数据处理
- 清理和修改: 代码可在https://github.com/swan-07/authorship-verification/blob/main/Authorship_Verification_Datasets.ipynb找到。
- 命名实体替换: 除PAN14、PAN15和PAN20外,所有数据集中的命名实体被替换为其通用类型。
- 数据结构: 数据集被重构为数据框,包含列|text1|text2|same|,其中same列的值为0表示两个文本的作者不同,值为1表示两个文本的作者相同。
- 数据分割: 所有数据集被分割为训练/测试/验证集,保持原有分割(如有),否则使用0.7:0.15:0.15的比例分割。