iix/Parquet_FIles
收藏资源简介:
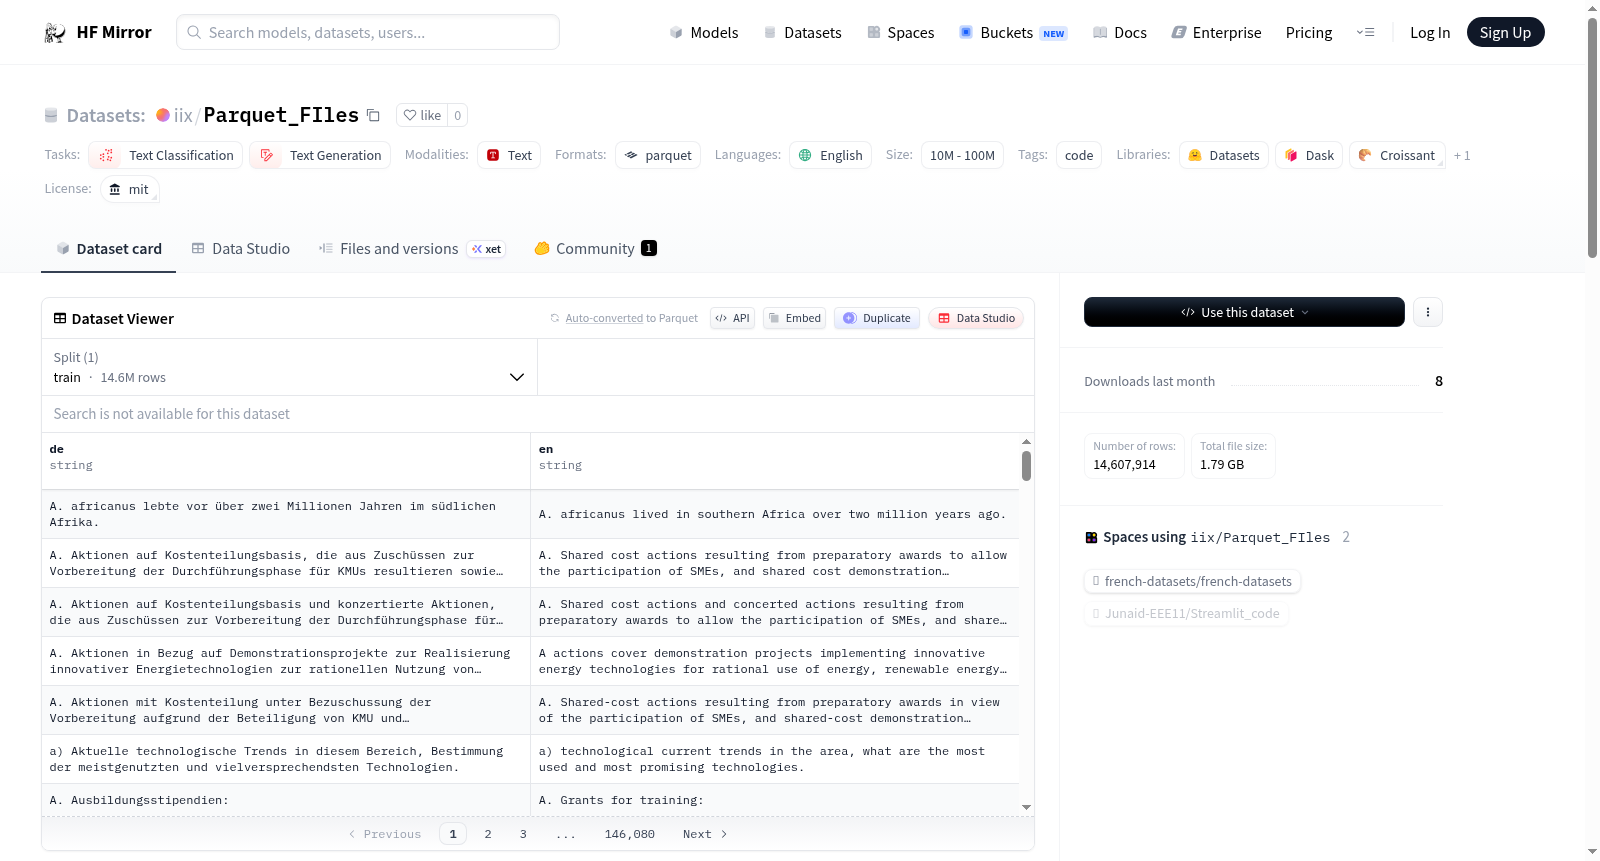
--- license: mit task_categories: - text-classification - text-generation language: - en tags: - code pretty_name: '*' size_categories: - 1M<n<10M --- # Parquet_Files # Cross Language (CL) Datasets Four datasets of language pair translations originating from CORDIS Project News (https://elrc-share.eu/) ``` Structured as follows: | Field | Description | | --------------- | ----------------------------------------------------------------------- | | de/es/fr/it | Non-English transcripts of sentences | | en | English translations of sentences | 120k rows (approx. per parquet file) ``` # Characters.parquet One large dataset of synthetic characters, information regarding them and their outputs. Created by combining other synthetic character datasets which can be found at: https://shorturl.at/gjIJ5, https://shorturl.at/DFQT6 & https://shorturl.at/tHX68. ``` Structured as follows: | Field | Description | | -------------- | --------------------------------------------------------------- | | name | Character name | | categories | Categories or genres associated with the character (array) | | personalities | Personality traits and characteristics of the character (array) | | description | Description of the character | | conversation | Conversational interactions involving the character (array) | 17.6k rows ``` # Flores7Lang.parquet Seven languages merged from the Flores-200 Dataset (https://github.com/facebookresearch/flores/blob/main/flores200/README.md) ``` Structured as follows: | Field | Description | | --------------- | ----------------------------------------------------- | | deu | Sentence translated into German | | eng | Sentence translated into English | | epo | Sentence translated into Esperanto | | fra | Sentence translated into French | | ita | Sentence translated into Italian | | spa | Sentence translated into Spanish | | tur | Sentence translated into Turkish | 2.1k rows ``` # Fraud_detection.parquet A synthetic financial dataset intended for Fraud detection tasks (https://www.kaggle.com/datasets/ealaxi/paysim1). ``` Structured as follows: | Field | Description | | --------------- | ------------------------------------------------------------- | | Step | Maps a unit of time in the real world (1 step = 1 hour) | | Type | CASH-IN, CASH-OUT, DEBIT, PAYMENT, or TRANSFER | | Amount | Amount of the transaction in local currency | | nameOrig | Customer who initiated the transaction | | oldbalanceOrg | Initial balance before the transaction | | newbalanceOrig | Customer's balance after the transaction | | nameDest | Recipient ID of the transaction | | oldbalanceDest | Initial recipient balance before the transaction | | newbalanceDest | Recipient's balance after the transaction | | isFraud | Identifies a fraudulent transaction (1) or non-fraudulent (0) | 2.27m rows ```
许可证:MIT协议 任务类别: - 文本分类 - 文本生成 语言: - 英语 标签: - 代码 美观名称:* 数据量区间:100万<n<1000万 # Parquet文件集 # 跨语言(Cross Language, CL)数据集 四个源自CORDIS项目新闻(来源:https://elrc-share.eu/)的语言对翻译数据集。 结构如下: | 字段名 | 描述 | | --------------- | -------------------------------------------------------------------- | | de/es/fr/it | 对应德语、西班牙语、法语、意大利语的非英语语句转录文本 | | en | 对应上述语句的英语翻译文本 | 每个Parquet文件约含12万条数据 # Characters.parquet数据集 该数据集为大型合成角色数据集,包含角色相关信息及其生成内容,由多个公开的合成角色数据集整合而成,原始数据集链接如下:https://shorturl.at/gjIJ5、https://shorturl.at/DFQT6 与 https://shorturl.at/tHX68。 结构如下: | 字段名 | 描述 | | --------------- | -------------------------------------------------------------------- | | name | 角色名称 | | categories | 与角色关联的类别或题材(数组格式) | | personalities | 角色的人格特质与特征(数组格式) | | description | 角色描述 | | conversation | 包含该角色的对话交互内容(数组格式) | 总计17.6万条数据 # Flores7Lang.parquet数据集 该数据集从Flores-200数据集(Flores-200 Dataset,来源:https://github.com/facebookresearch/flores/blob/main/flores200/README.md)中整合了7种语言的语料。 结构如下: | 字段名 | 描述 | | ------- | ------------------------------------------ | | deu | 德语译句 | | eng | 英语译句 | | epo | 世界语译句 | | fra | 法语译句 | | ita | 意大利语译句 | | spa | 西班牙语译句 | | tur | 土耳其语译句 | 总计2.1千条数据 # Fraud_detection.parquet数据集 该数据集为合成金融数据集,用于欺诈检测任务(来源:https://www.kaggle.com/datasets/ealaxi/paysim1)。 结构如下: | 字段名 | 描述 | | --------------- | -------------------------------------------------------------------- | | Step | 映射现实世界的时间单位(1步=1小时) | | Type | 交易类型,包括CASH-IN(现金存入)、CASH-OUT(现金取出)、DEBIT(借记)、PAYMENT(支付)或TRANSFER(转账) | | Amount | 以当地货币计价的交易金额 | | nameOrig | 发起交易的客户ID | | oldbalanceOrg | 交易前发起方账户的初始余额 | | newbalanceOrig | 交易后发起方账户的余额 | | nameDest | 交易接收方ID | | oldbalanceDest | 交易前接收方账户的初始余额 | | newbalanceDest | 交易后接收方账户的余额 | | isFraud | 交易欺诈标记,1表示欺诈交易,0表示非欺诈交易 | 总计227万条数据
数据集概述
Parquet_Files
Cross Language (CL) Datasets
- 来源: CORDIS Project News (https://elrc-share.eu/)
- 描述: 包含四种语言对翻译的数据集。
- 结构:
字段 描述 de/es/fr/it 非英语句子 en 英语翻译句子 - 大小: 约120,000行/文件
Characters.parquet
- 描述: 包含合成角色及其相关信息的大型数据集。
- 结构:
字段 描述 name 角色名称 categories 角色关联的类别或类型(数组) personalities 角色的性格特征(数组) description 角色描述 conversation 角色参与的对话(数组) - 大小: 17,600行
Flores7Lang.parquet
- 来源: Flores-200 Dataset (https://github.com/facebookresearch/flores/blob/main/flores200/README.md)
- 描述: 包含七种语言的数据集。
- 结构:
字段 描述 deu 德语翻译句子 eng 英语翻译句子 epo 世界语翻译句子 fra 法语翻译句子 ita 意大利语翻译句子 spa 西班牙语翻译句子 tur 土耳其语翻译句子 - 大小: 2,100行
Fraud_detection.parquet
- 来源: Kaggle (https://www.kaggle.com/datasets/ealaxi/paysim1)
- 描述: 用于欺诈检测任务的合成金融数据集。
- 结构:
字段 描述 Step 现实世界中的时间单位(1步=1小时) Type 交易类型(CASH-IN, CASH-OUT, DEBIT, PAYMENT, TRANSFER) Amount 交易金额(本地货币) nameOrig 发起交易的客户 oldbalanceOrg 交易前的初始余额 newbalanceOrig 交易后的客户余额 nameDest 交易接收者ID oldbalanceDest 交易前的接收者初始余额 newbalanceDest 交易后的接收者余额 isFraud 标识欺诈交易(1)或非欺诈交易(0) - 大小: 2,270,000行