adi-gov-tw/Taiwan-Tongues-ASR-CE-dataset-test
收藏资源简介:
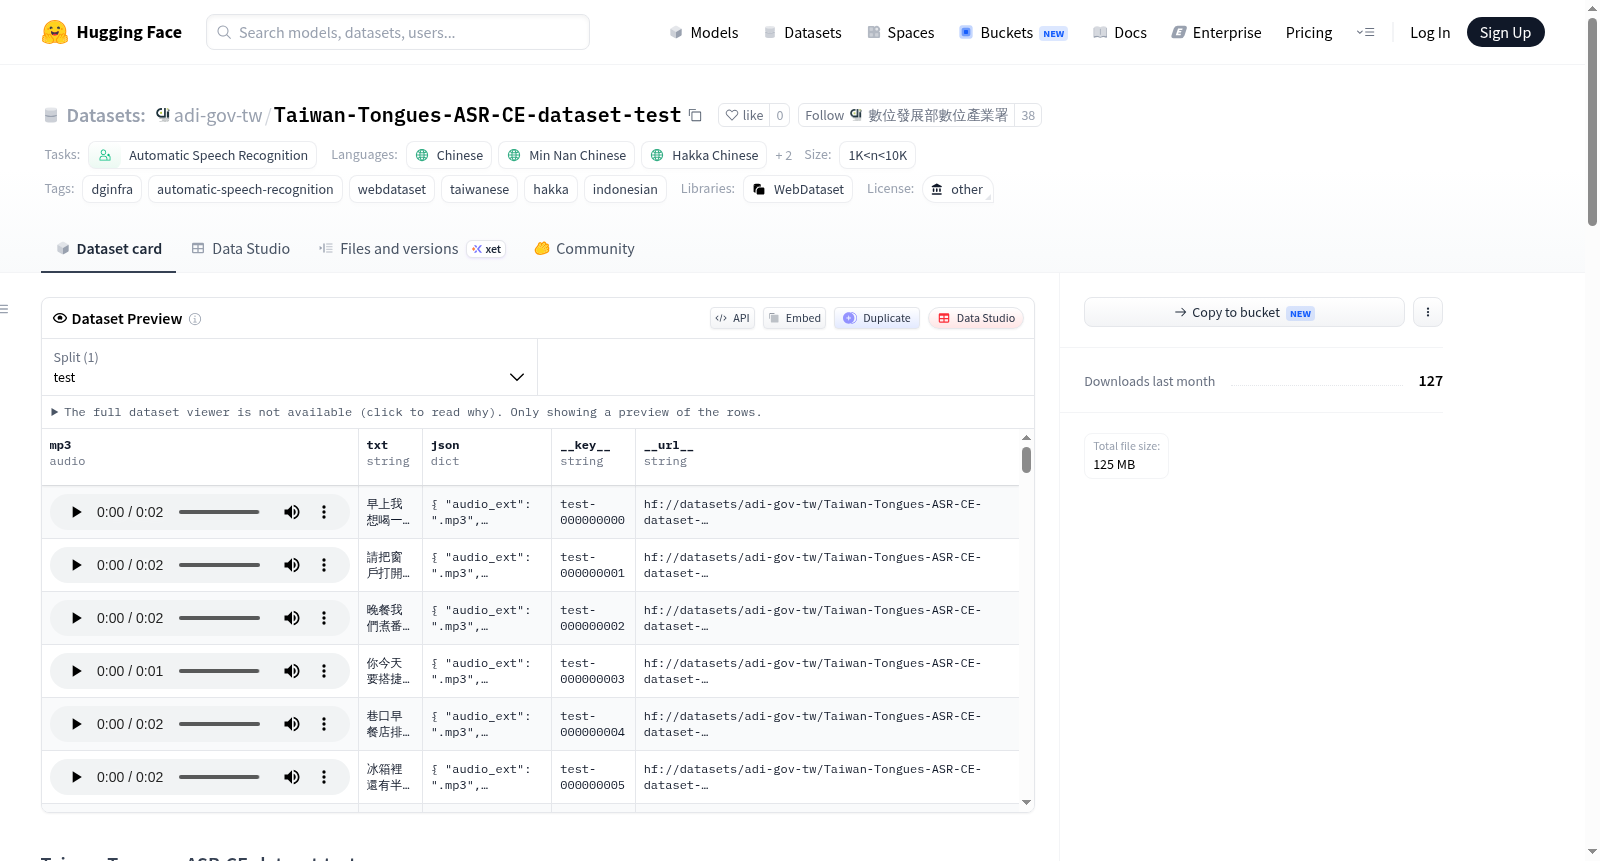
Taiwan-Tongues-ASR-CE-dataset-test 是台湾语种ASR-CE项目使用的测试数据集,以WebDataset tar分片形式打包,用于自动语音识别评估。该数据集核心测试集包含约3小时、涵盖四种语言的音频:中文普通话、台湾闽南语、客家语和英语。在v2.0印尼语更新中,印尼语测试元数据已合并到同一个test.tsv文件中,印尼语tar分片也包含在同一test/分片目录下。音频文件存储在压缩的.tar分片中,未在仓库中作为单独文件展开。数据集总计3852条话语,总时长为3.45小时,包括中文普通话(1262条,1.00小时)、台湾闽南语(827条,0.63小时)、客家语(473条,0.59小时)、英语(687条,0.58小时)和印尼语(603条,0.66小时)。数据集旨在用于ASR评估,音频以压缩格式存储,无需解压即可通过WebDataset流式读取,许可证列为其他,使用前需参考项目和发布文档。
Taiwan-Tongues-ASR-CE-dataset-test is the test dataset used by the Taiwan-Tongues-ASR-CE project, packaged as WebDataset tar shards for automatic speech recognition evaluation. The core test set is a roughly 3-hour, 4-language evaluation set for Mandarin Chinese, Taiwanese Hokkien, Hakka, and English. For the v2.0 Indonesian update, the Indonesian test metadata has been merged into the same test.tsv, and the Indonesian tar shards are included under the same test/ shard directory. Audio files remain inside the compressed .tar shards and are not expanded as individual files in the repository. The dataset totals 3,852 utterances with a duration of 3.45 hours, including Mandarin Chinese (1,262 utterances, 1.00 hours), Taiwanese Hokkien (827 utterances, 0.63 hours), Hakka (473 utterances, 0.59 hours), English (687 utterances, 0.58 hours), and Indonesian (603 utterances, 0.66 hours). It is intended for ASR evaluation, with audio stored in compressed format that can be streamed via WebDataset without unpacking; the license is listed as other, and users should refer to project and release documentation before use.