Jianshu001/arabic-daily-batch01-v5-5k
收藏资源简介:
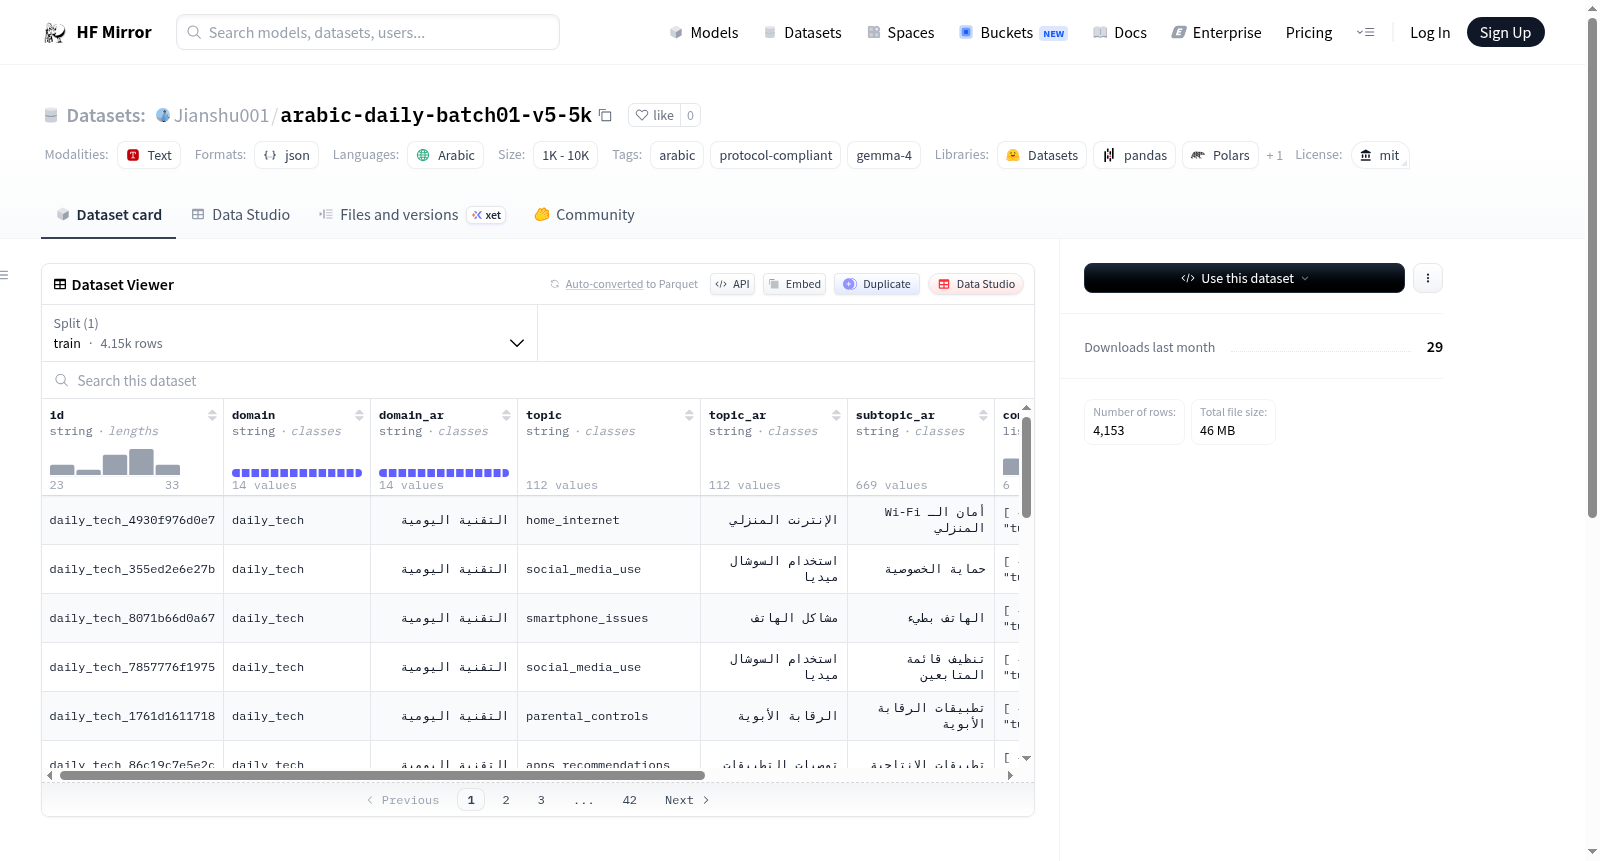
阿拉伯日常对话 — v5流程 — 4153条记录。该数据集包含4153条阿拉伯语日常对话记录,通过一个多步骤的流程生成:1. 使用Gemma-4-31B在720个子主题上生成对话;2. 通过Gemma-as-rewriter清理思维标签;3. 使用6维Gemma评估(真实性/助手质量/多轮/领域适应性/安全性/完整性),任何维度不达标则丢弃;4. 正则表达式最终审核,丢弃任何残留泄漏。数据模式包括用户和助手的对话结构,用户部分包含轮次、角色和文本,助手部分包含轮次、角色、思维和文本。
Arabic Daily Conversations — v5 Pipeline — 4153 records. This dataset contains 4153 records of Arabic daily conversations, generated through a multi-step pipeline: 1. Gemma-4-31B generation on 720 subtopics; 2. Thinking cleanup via Gemma-as-rewriter (removes role/style/draft-scaffolding labels); 3. 6-dimension Gemma judge (realism/assistant_quality/multi_turn/domain_fit/safety/integrity) — any dim dirty → drop; 4. Regex final audit — drops any residual leak. The schema includes user and assistant dialogue structures, with user part containing turn, role, and text, and assistant part containing turn, role, thinking, and text.