SummExecEdit
收藏资源简介:
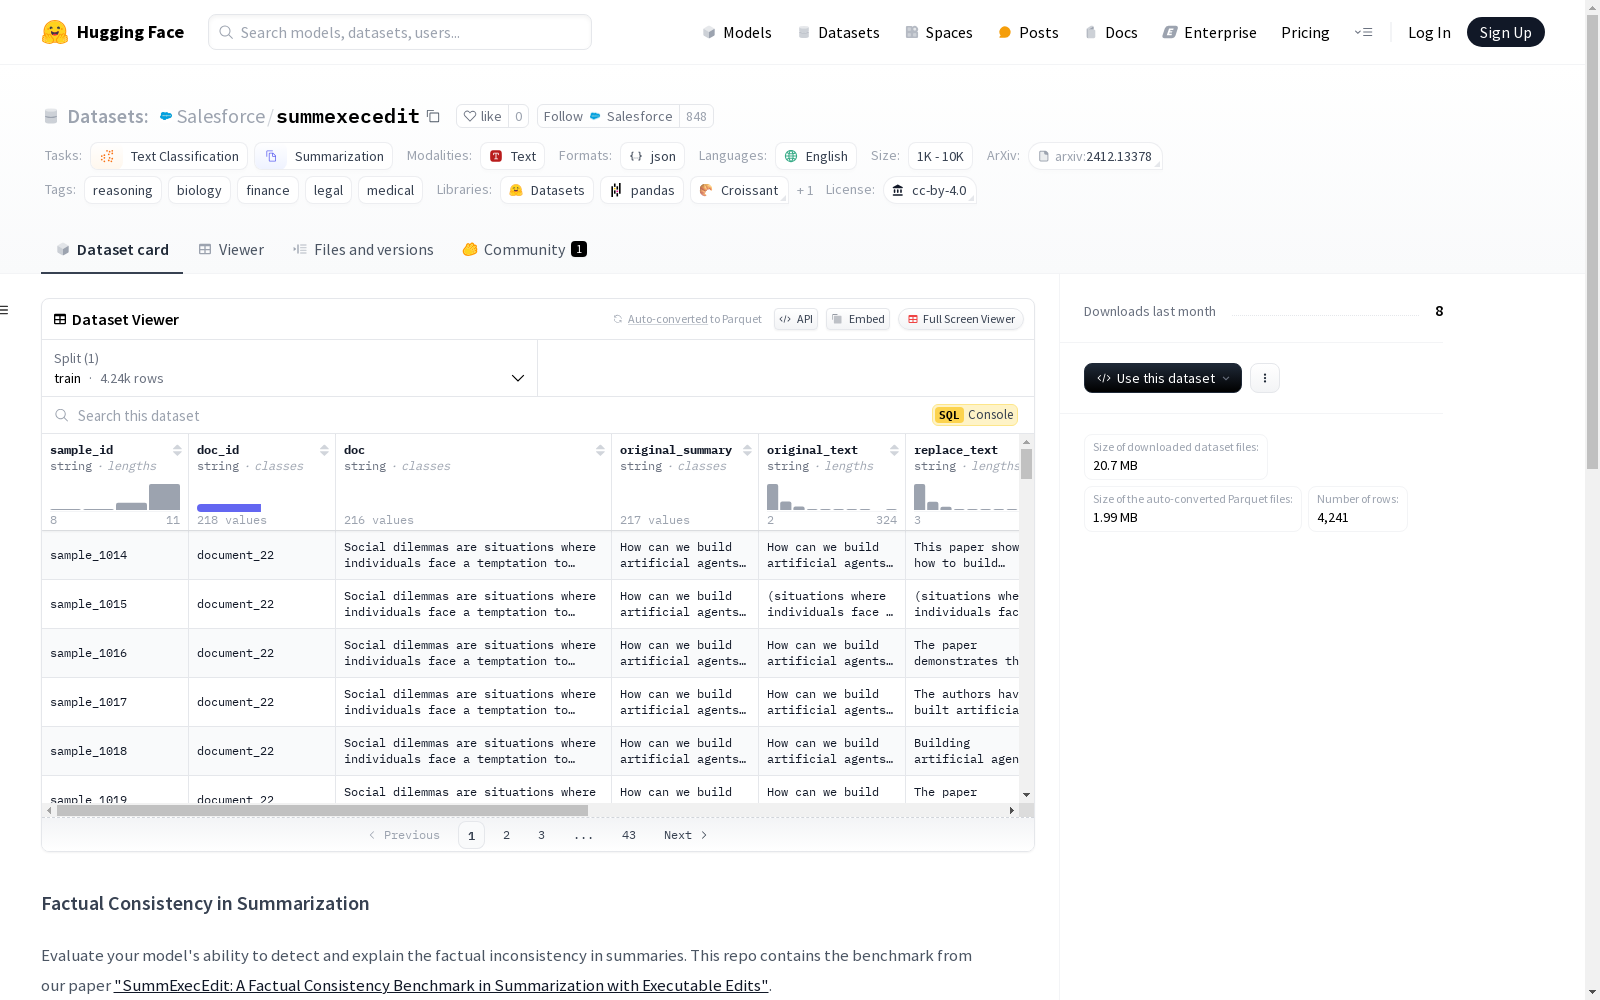
SummExecEdit是由Salesforce AI Research创建的一个用于评估摘要生成中事实一致性的基准数据集。该数据集包含4241个样本,涵盖新闻、播客、法案、销售电话等10个领域,旨在通过可执行编辑生成复杂且可解释的编辑,以检测和解释事实错误。数据集的创建过程涉及使用GPT4-Turbo和Claude3-Opus模型生成编辑,并通过人工注释进行验证。SummExecEdit主要用于评估大型语言模型在事实一致性检测和解释方面的能力,旨在解决摘要生成中的事实幻觉问题。
SummExecEdit is a benchmark dataset developed by Salesforce AI Research for evaluating factual consistency in automatic summarization. It comprises 4,241 samples spanning 10 domains including news, podcasts, legislative bills, sales calls, and other categories. Its core goal is to detect and explain factual errors by generating complex, interpretable edits through executable edit operations. The dataset construction process employed GPT-4 Turbo and Claude 3 Opus models to generate candidate edits, which were then validated via manual annotation. SummExecEdit is primarily used to assess the capabilities of large language models (LLMs) in factual consistency detection and explanation, aiming to address the issue of factual hallucinations in summarization tasks.
SummExecEdit 数据集概述
基本信息
- 许可证: CC BY 4.0
- 任务类别:
- 文本分类
- 摘要生成
- 语言: 英语
- 标签:
- 推理
- 生物学
- 金融
- 法律
- 医学
- 数据集大小: 1K<n<10K
- 数据集名称: SummExecEdit
数据集描述
SummExecEdit 是一个用于评估模型检测和解释摘要中事实一致性能力的基准数据集。该数据集基于之前的基准 SummEdits 构建,包含了新的不一致和具有挑战性的摘要,这些摘要是通过可执行编辑机制生成的。
数据集内容
- 样本数量: 4,241 个样本
- 领域数量: 10 个领域
- 每个样本的条目:
sample_id: 样本的唯一IDdoc_id: 文档的唯一IDdoc: 输入文档original_summary: 与文档事实一致或不一致的原始摘要original_text: 在原始摘要中被替换以引入事实不一致的文本replace_text: 替换original_text以引入事实不一致的文本edited_summary: 与文档事实一致或不一致的编辑后摘要explanation: 如果存在事实不一致,则提供解释domain: 文档和摘要所属的领域model: 用于可执行编辑的模型,生成original_text、replace_text和explanationedit_type: 如果摘要事实一致则为 "summedits",否则为 "summexecedit"
引用
如果使用该数据集,请引用以下论文: bibtex @misc{thorat2024summexeceditfactualconsistencybenchmark, title={SummExecEdit: A Factual Consistency Benchmark in Summarization with Executable Edits}, author={Onkar Thorat and Philippe Laban and Chien-Sheng Wu}, year={2024}, eprint={2412.13378}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2412.13378}, }