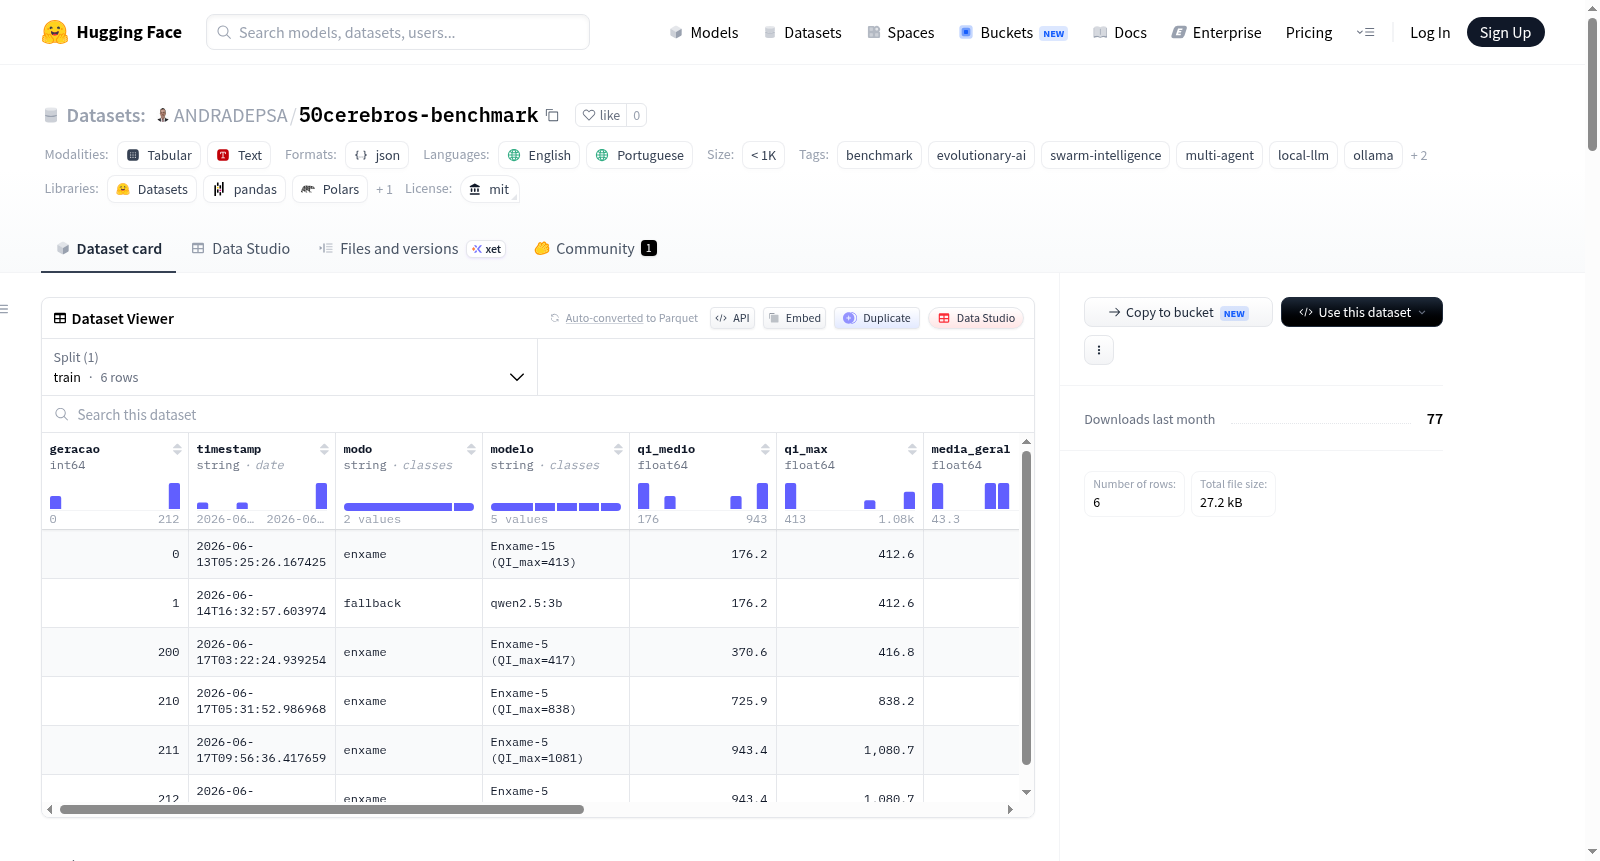
50cerebros-benchmark
收藏资源简介:
“5 Cérebros V40 — 群体集体智能基准测试”数据集是一个用于评估多代理进化人工智能系统性能的资源。该系统由五个被称为“大脑”的AI代理组成,这些代理被组织在十一个预定义的认知层(如额叶、边缘系统、颞叶等)中,并通过遗传算法(包括适应度选择、交叉和突变机制)持续进化。数据集的核心目标是量化“群体集体智能”,即代理集体通过协作与进化在综合性能上超越任何单个成员的能力。它主要包含系统在多项自然语言理解与推理基准任务(包括ARC Easy、ARC Challenge和HellaSwag)上的历史测试记录。对于每个测试轮次,数据记录了“群体”的集体性能得分、与最佳单代理相比的“集体增益”、参与测试的代理面板构成(包括模型类型、所属认知层和个体智商QI),以及反映系统进化状态的元数据(如累积基因数、平均智商、最大智商、种群多样性香农熵和灭绝事件次数)。该系统的显著特点是完全在本地有限硬件(如i3处理器和8GB内存,使用Ollama,无需GPU或云服务)上运行,强调零成本、数据隐私和自主进化能力。数据集提供了完整的测试历史(以JSON和CSV格式)以及最新的可读测试报告(TXT格式),适用于研究多代理系统、群体智能、进化算法在AI任务中的应用,以及评估AI系统在性能、效率、成本与隐私等多维度下的综合表现。
The "5 Cérebros V40 — Collective Intelligence Benchmark" dataset records the performance evaluation results of a multi-agent evolutionary AI system. This system consists of five AI agents, referred to as "brains," organized into eleven predefined cognitive layers (such as frontal lobe, limbic system, temporal lobe, etc.), and continuously evolves through genetic algorithms (including mechanisms like fitness selection, crossover, and mutation). The core objective of this benchmark is to quantify "collective swarm intelligence," which is the ability of a group of agents to surpass the performance of any individual member through collaboration and evolution. The dataset primarily includes historical test records of the system on multiple natural language understanding and reasoning benchmark tasks (including ARC Easy, ARC Challenge, and HellaSwag). For each test round, the data records the collective performance score of the "swarm," the "collective gain" compared to the best single agent, the composition of the agent panel involved in testing (model type, cognitive layer, individual intelligence quotient QI), and metadata reflecting the evolutionary state of the system (such as cumulative gene count, average IQ, maximum IQ, population diversity Shannon entropy, and extinction event count). A notable feature of this system is that it runs entirely on limited local hardware (i3 processor/8GB RAM, using Ollama, without the need for GPUs or cloud services), emphasizing zero cost, data privacy, and autonomous evolution capabilities. The dataset provides complete test history (in JSON and CSV formats) and the latest readable test reports (in TXT format). It is suitable for research on multi-agent systems, swarm intelligence, applications of evolutionary algorithms in AI tasks, and evaluating the comprehensive performance of AI systems across multiple dimensions such as performance, efficiency, cost, and privacy.
数据集概述:5 Cérebros V40 — Benchmark de Inteligência Coletiva do Enxame
该数据集是一个用于衡量群体智能的基准测试,基于一个名为“5 Cérebros V40”的多智能体进化系统。系统由5个AI大脑(智能体)组成,通过遗传算法在认知层中进化,旨在测量群体智能。
核心特性与用途
- 类型: 基准测试(Benchmark)
- 关键概念: 群体智能、多智能体、进化AI
- 硬件环境: 运行在 i3 / 8GB RAM 的本地设备上,使用 Ollama,无需GPU或云端资源。
- 许可证: MIT
- 语言: 英语 (en)、葡萄牙语 (pt)
最新测试结果(第212代)
- 群体智能分数: 63.3%
- 群体增益(群体 vs 最佳个体): ▲40.0%
- 面板组织: 1个组 × 最多5个大脑(共5个)
- 认知层数: 4
- 不同模型数: 5
- 累积基因数: 150
群体 vs 最佳个体表现
| 任务 | 群体(集体) | 最佳个体 | 群体增益 |
|---|---|---|---|
| ARC Easy | 100.0% | 20.0% | ▲80.0% |
| ARC Challenge | 70.0% | 50.0% | ▲20.0% |
| HellaSwag | 20.0% | 0.0% | ▲20.0% |
综合排名(智能 + 效率 + 隐私 + 进化)
该基准测试通过一个综合评分(40% 语言智能 + 15% 硬件 + 15% 成本 + 10% 隐私 + 20% 进化)对模型进行排名。
- 第一名: 50 Cérebros G212 ⭐ — 综合得分 7.61/10
- 第二名: LLaMA3 70B — 得分 6.78/10
- 第三名: Phi-3 Mini 3.8B — 得分 6.75/10
- GPT-4 得分 6.27/10,排名第四。
基准测试工作流程
- 面板: 1个组包含最多5个大脑。
- 基因: 每个大脑从集体记忆中接收一个基因。
- 1-SHOT: 每个问题前注入示例格式。
- 提问: 每个大脑以其认知角色回答。
- 投票: 汇总5个大脑的加权投票(按IQ加权),形成群体答案。
系统架构
系统由11个认知层构成,包括:
- 额叶(逻辑推理)、边缘系统(情感回应)、颞叶(记忆与连接)、顶叶(模式与数字)、枕叶(视觉描述)、脑干(本能反应)、小脑(协调与平衡)、海马体(长期存档)、杏仁核(初级情感)、皮层(综合合成)、DeepSeek(逐步推理)。
进化状态(第212代)
- 平均IQ: 943.4
- 最高IQ: 1080.7
- 累积基因: 150
- 灭绝/灾难次数: 12
- 香农多样性熵: 2.32 bits
- 基准测试轮次: 6
数据集文件
| 文件名 | 描述 |
|---|---|
benchmark_historico.json |
所有轮次的完整历史记录 |
benchmark_historico.csv |
用于分析的表格(群体、最佳个体、各任务增益) |
benchmark_ultimo.txt |
最新测试的可读报告 |