symile-m3
收藏资源简介:
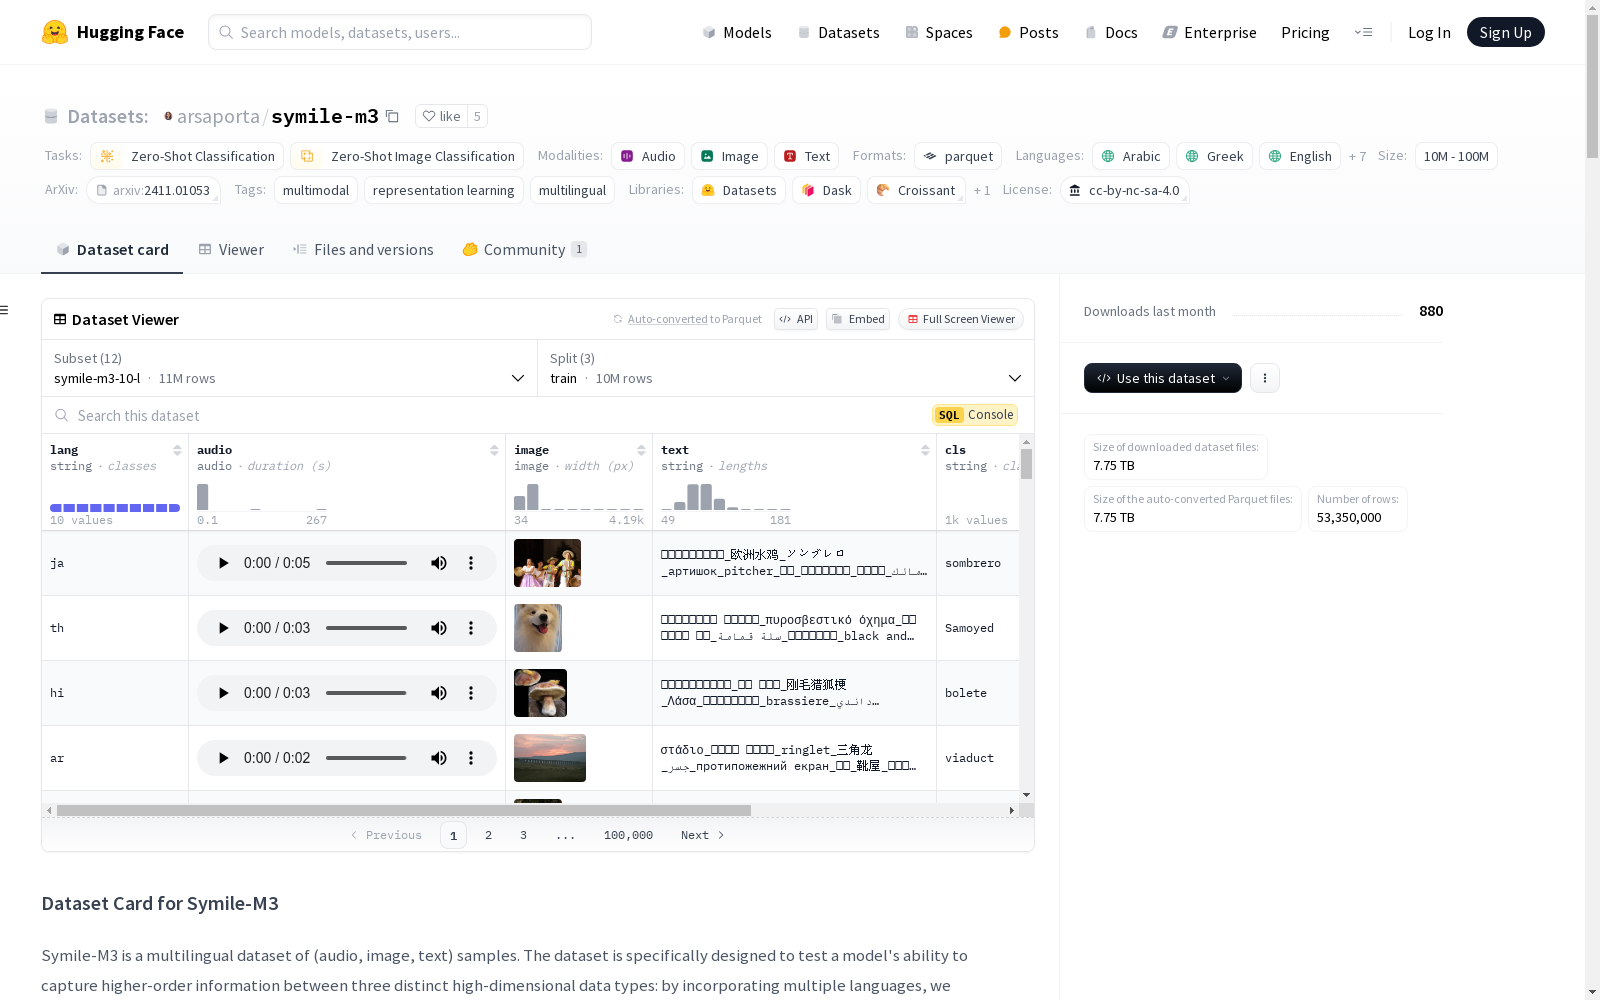
Symile-M3 是一个多语言的多模态数据集,包含音频、图像和文本样本。数据集设计用于测试模型在三种不同高维数据类型之间捕捉高阶信息的能力。具体来说,数据集包含多个语言版本的音频、图像和文本,要求模型通过音频和文本共同预测图像,而单独的音频或文本不足以完成任务。数据集包含多个配置版本,每个版本有不同的语言数量和数据规模。每个样本包含语言代码、音频数据、图像数据、文本、目标类别名称及其ID等信息。
Symile-M3 is a multilingual multimodal dataset containing audio, image, and text samples. This dataset is designed to test a model's ability to capture high-order information across three distinct high-dimensional data modalities. Specifically, the dataset includes audio, image, and text samples in multiple language versions, requiring the model to jointly predict the image using both audio and text, where either audio alone or text alone is insufficient to complete the task. The dataset features multiple configuration variants, each with varying numbers of languages and data scales. Each sample contains information such as language code, audio data, image data, text, target category name, and its corresponding ID.
Symile-M3 数据集概述
基本信息
- 许可证: CC BY-NC-SA 4.0
- 任务类别:
- 零样本分类
- 零样本图像分类
- 语言:
- 阿拉伯语 (ar)
- 希腊语 (el)
- 英语 (en)
- 印地语 (hi)
- 日语 (ja)
- 韩语 (ko)
- 泰卢固语 (te)
- 泰语 (th)
- 乌克兰语 (uk)
- 中文 (zh)
- 标签:
- 多模态
- 表示学习
- 多语言
- 数据集名称: Symile-M3
- 数据集大小: 10M < n < 100M
配置信息
symile-m3-5-m
- 特征:
lang: 字符串audio: 音频image: 图像text: 字符串cls: 字符串cls_id: int64target_text: 字符串
- 分割:
train: 725049451643.0 字节, 5000000 样本val: 35602464495.0 字节, 250000 样本test: 36207897705.0 字节, 250000 样本
- 下载大小: 798705714640 字节
- 数据集大小: 796859813843.0 字节
symile-m3-5-s
- 特征:
lang: 字符串audio: 音频image: 图像text: 字符串cls: 字符串cls_id: int64target_text: 字符串
- 分割:
train: 142185812397.0 字节, 1000000 样本val: 7217779117.0 字节, 50000 样本test: 7586183683.0 字节, 50000 样本
- 下载大小: 159628727029 字节
- 数据集大小: 156989775197.0 字节
symile-m3-5-xs
- 特征:
lang: 字符串audio: 音频image: 图像text: 字符串cls: 字符串cls_id: int64target_text: 字符串
- 分割:
train: 70410563197.0 字节, 500000 样本val: 3607295872.0 字节, 25000 样本test: 3624041386.0 字节, 25000 样本
- 下载大小: 80003029310 字节
- 数据集大小: 77641900455.0 字节
数据集结构
每个样本包含以下字段:
lang: 音频剪辑的语言代码audio: 音频数据path: Common Voice 文件名array: 原始音频波形sampling_rate: 采样率 (Hz)
image: PIL Image 对象 (RGB, 尺寸可变)text: 包含 w 个单词的文本 (每个语言一个单词), 用下划线分隔cls: 目标单词的英文类名cls_id: 类 ID (0 到 999)target_text: 目标单词 (音频语言中的类名)
数据集变体
- Symile-M3-2: 2 种语言 (英语, 希腊语)
- Symile-M3-5: 5 种语言 (英语, 希腊语, 印地语, 日语, 乌克兰语)
- Symile-M3-10: 10 种语言 (阿拉伯语, 希腊语, 英语, 印地语, 日语, 韩语, 泰卢固语, 泰语, 乌克兰语, 中文)
每个变体有四种大小:
- Large (l): 10M 训练样本, 500K 验证样本, 500K 测试样本
- Medium (m): 5M 训练样本, 250K 验证样本, 250K 测试样本
- Small (s): 1M 训练样本, 50K 验证样本, 50K 测试样本
- Extra Small (xs): 500K 训练样本, 25K 验证样本, 25K 测试样本