lhpku20010120/Data-Prep-Bench
收藏资源简介:
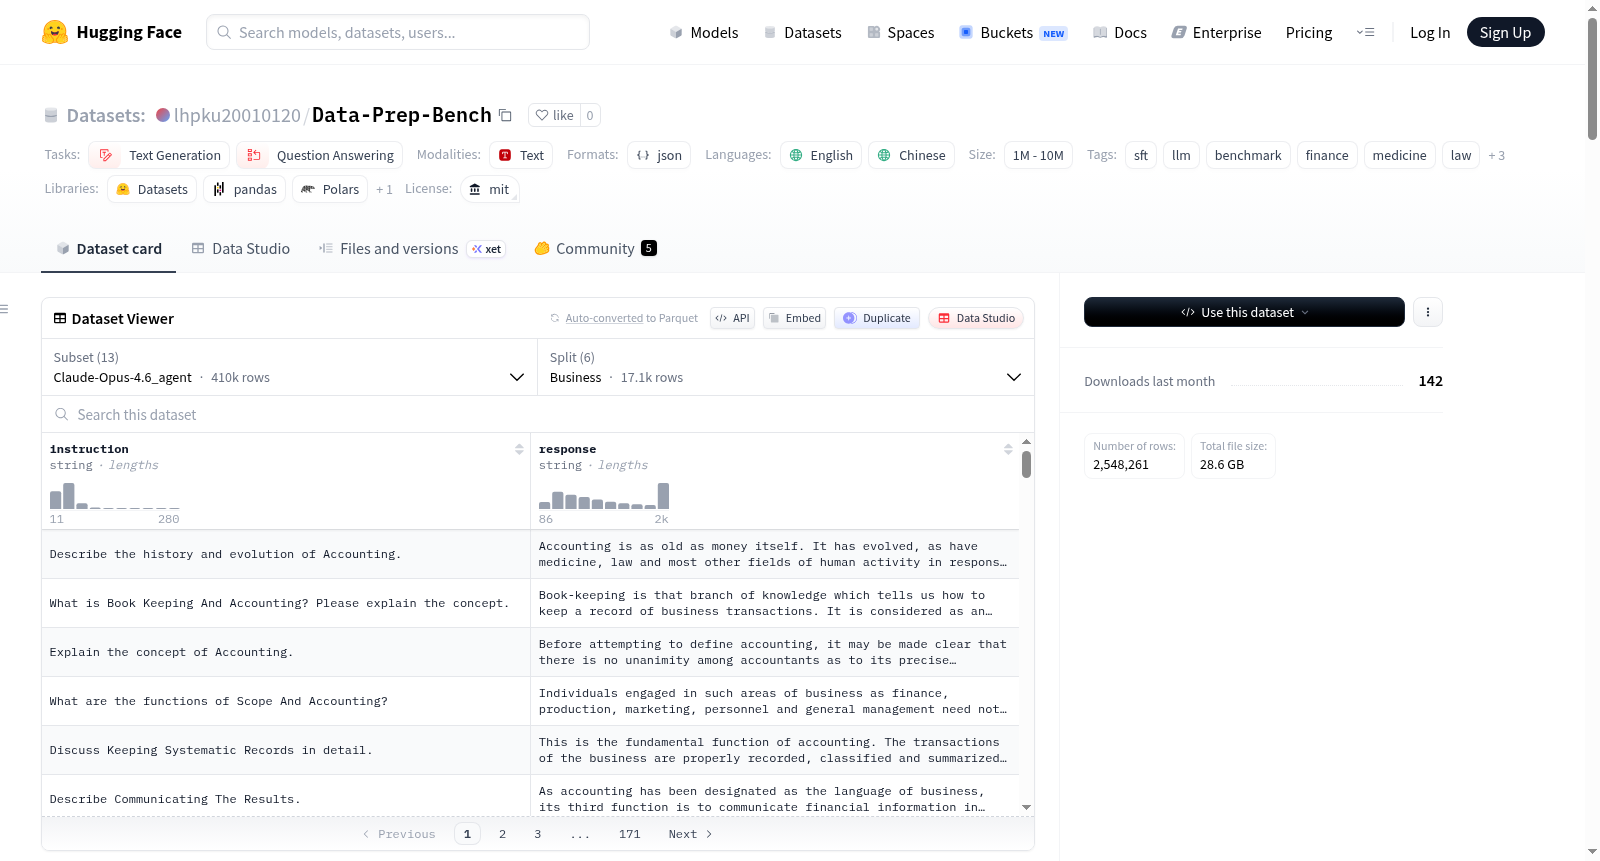
该数据集是一个全面的资源,专为大型语言模型(LLMs)的监督微调(SFT)和评估而构建,涵盖六个领域:金融、医学、法律、数学、科学和通用领域。关键特点是采用了12种不同的数据生成方法(包括基于代理的方法、DataFlow系列、纯LLM生成和SKILL方法),使用多种尖端模型(如GPT-5、Claude Opus 4.6、Gemini 3.0 Pro等)处理原始语料库并生成高质量的问答对(QA)。此外,存储库还提供了标准化的基准文件用于模型评估。数据集支持多语言(训练语料库包含中文和英文;基准测试为英文),任务包括监督微调(SFT)和模型评估。
This dataset is a comprehensive resource built for Supervised Fine-Tuning (SFT) and evaluation of Large Language Models (LLMs), covering six domains: Finance, Medicine, Law, Mathematics, Science, and General. A key feature of this dataset is that it employs 12 different data generation methods (including Agent-based methods, DataFlow series, pure LLM-based generation, and a SKILL method) using multiple cutting-edge models (such as GPT-5, Claude Opus 4.6, Gemini 3.0 Pro, etc.) to process raw corpora and produce high-quality question-answer (QA) pairs. In addition, the repository provides standardized benchmark files for model evaluation. The dataset supports multilingual content (training corpora contain both Chinese and English; benchmarks are in English) and tasks include Supervised Fine-Tuning (SFT) and Model Evaluation.