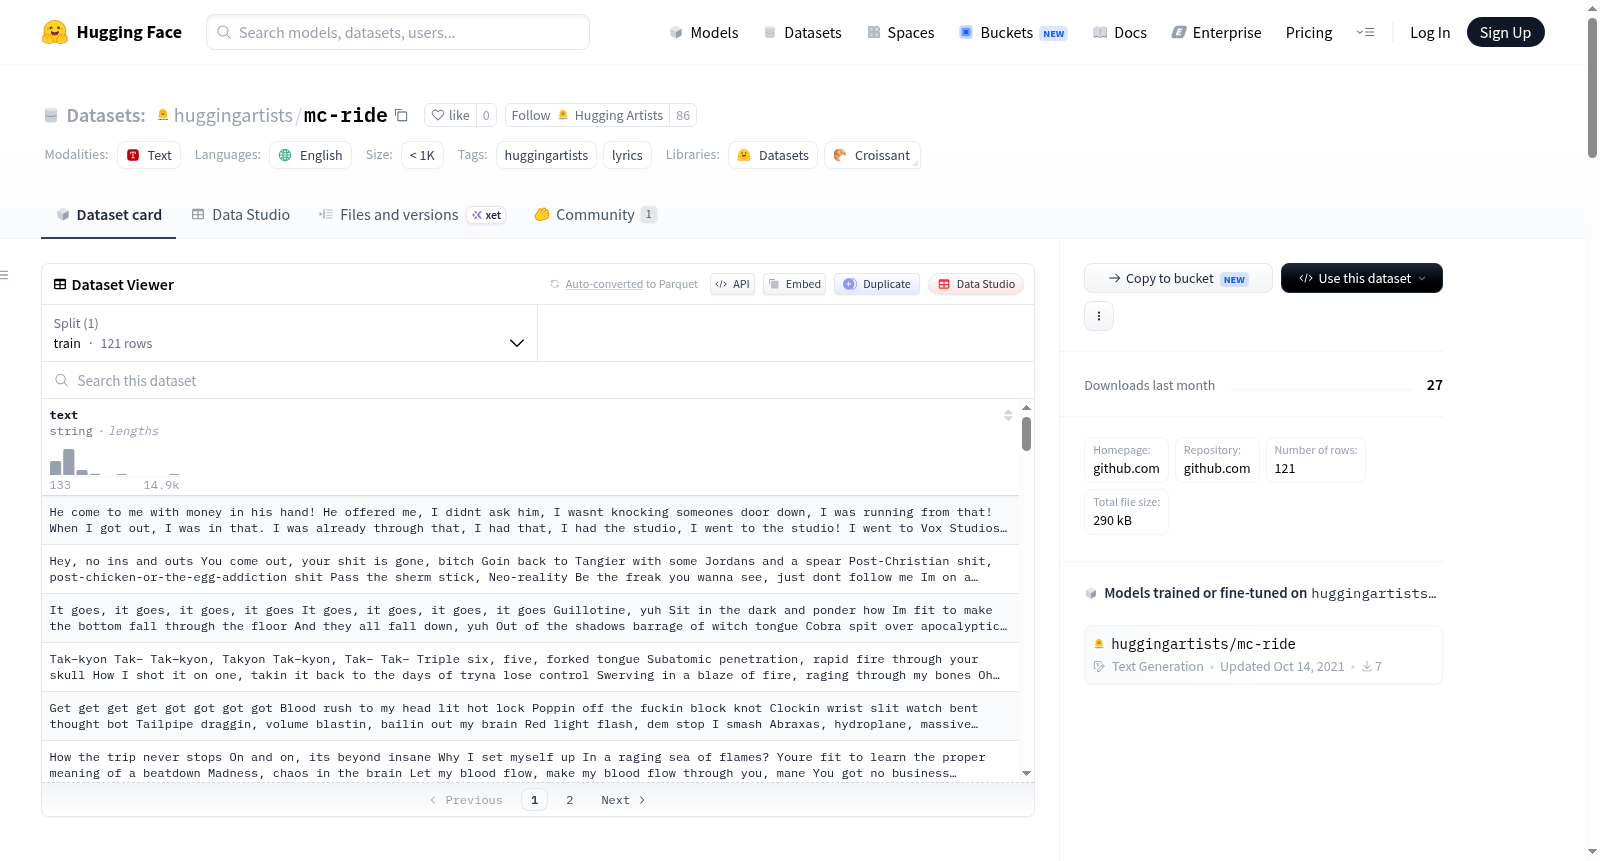
huggingartists/mc-ride
收藏资源简介:
--- language: - en tags: - huggingartists - lyrics --- # Dataset Card for "huggingartists/mc-ride" ## Table of Contents - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Supported Tasks and Leaderboards](#supported-tasks-and-leaderboards) - [Languages](#languages) - [How to use](#how-to-use) - [Dataset Structure](#dataset-structure) - [Data Fields](#data-fields) - [Data Splits](#data-splits) - [Dataset Creation](#dataset-creation) - [Curation Rationale](#curation-rationale) - [Source Data](#source-data) - [Annotations](#annotations) - [Personal and Sensitive Information](#personal-and-sensitive-information) - [Considerations for Using the Data](#considerations-for-using-the-data) - [Social Impact of Dataset](#social-impact-of-dataset) - [Discussion of Biases](#discussion-of-biases) - [Other Known Limitations](#other-known-limitations) - [Additional Information](#additional-information) - [Dataset Curators](#dataset-curators) - [Licensing Information](#licensing-information) - [Citation Information](#citation-information) - [About](#about) ## Dataset Description - **Homepage:** [https://github.com/AlekseyKorshuk/huggingartists](https://github.com/AlekseyKorshuk/huggingartists) - **Repository:** [https://github.com/AlekseyKorshuk/huggingartists](https://github.com/AlekseyKorshuk/huggingartists) - **Paper:** [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) - **Point of Contact:** [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) - **Size of the generated dataset:** 0.304935 MB <div class="inline-flex flex-col" style="line-height: 1.5;"> <div class="flex"> <div style="display:DISPLAY_1; margin-left: auto; margin-right: auto; width: 92px; height:92px; border-radius: 50%; background-size: cover; background-image: url('https://images.genius.com/c33b218009a0389e72c6d6628d3c2105.1000x1000x1.jpg')"> </div> </div> <a href="https://huggingface.co/huggingartists/mc-ride"> <div style="text-align: center; margin-top: 3px; font-size: 16px; font-weight: 800">🤖 HuggingArtists Model 🤖</div> </a> <div style="text-align: center; font-size: 16px; font-weight: 800">MC Ride</div> <a href="https://genius.com/artists/mc-ride"> <div style="text-align: center; font-size: 14px;">@mc-ride</div> </a> </div> ### Dataset Summary The Lyrics dataset parsed from Genius. This dataset is designed to generate lyrics with HuggingArtists. Model is available [here](https://huggingface.co/huggingartists/mc-ride). ### Supported Tasks and Leaderboards [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Languages en ## How to use How to load this dataset directly with the datasets library: ```python from datasets import load_dataset dataset = load_dataset("huggingartists/mc-ride") ``` ## Dataset Structure An example of 'train' looks as follows. ``` This example was too long and was cropped: { "text": "Look, I was gonna go easy on you\nNot to hurt your feelings\nBut I'm only going to get this one chance\nSomething's wrong, I can feel it..." } ``` ### Data Fields The data fields are the same among all splits. - `text`: a `string` feature. ### Data Splits | train |validation|test| |------:|---------:|---:| |121| -| -| 'Train' can be easily divided into 'train' & 'validation' & 'test' with few lines of code: ```python from datasets import load_dataset, Dataset, DatasetDict import numpy as np datasets = load_dataset("huggingartists/mc-ride") train_percentage = 0.9 validation_percentage = 0.07 test_percentage = 0.03 train, validation, test = np.split(datasets['train']['text'], [int(len(datasets['train']['text'])*train_percentage), int(len(datasets['train']['text'])*(train_percentage + validation_percentage))]) datasets = DatasetDict( { 'train': Dataset.from_dict({'text': list(train)}), 'validation': Dataset.from_dict({'text': list(validation)}), 'test': Dataset.from_dict({'text': list(test)}) } ) ``` ## Dataset Creation ### Curation Rationale [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Source Data #### Initial Data Collection and Normalization [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### Who are the source language producers? [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Annotations #### Annotation process [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### Who are the annotators? [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Personal and Sensitive Information [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## Considerations for Using the Data ### Social Impact of Dataset [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Discussion of Biases [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Other Known Limitations [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## Additional Information ### Dataset Curators [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Licensing Information [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Citation Information ``` @InProceedings{huggingartists, author={Aleksey Korshuk} year=2021 } ``` ## About *Built by Aleksey Korshuk* [](https://github.com/AlekseyKorshuk) [](https://twitter.com/intent/follow?screen_name=alekseykorshuk) [](https://t.me/joinchat/_CQ04KjcJ-4yZTky) For more details, visit the project repository. [](https://github.com/AlekseyKorshuk/huggingartists)
数据集概述
数据集名称
"huggingartists/mc-ride"
数据集描述
- 数据集总结: 该数据集是从Genius解析的歌词数据,旨在用于HuggingArtists生成歌词。
- 支持的任务和排行榜: 待补充
- 语言: 英语(en)
数据集结构
- 数据字段:
text: 字符串类型,包含歌词内容。
- 数据分割:
train: 121条记录validation和test: 待划分
使用方法
python from datasets import load_dataset
dataset = load_dataset("huggingartists/mc-ride")
数据集创建
- 来源数据: 待补充
- 注释: 待补充
- 个人和敏感信息: 待补充
使用数据时的考虑
- 数据集的社会影响: 待补充
- 偏见讨论: 待补充
- 其他已知限制: 待补充
附加信息
-
数据集管理员: 待补充
-
许可信息: 待补充
-
引用信息:
@InProceedings{huggingartists, author={Aleksey Korshuk} year=2021 }