nsp909/MDTA
收藏资源简介:
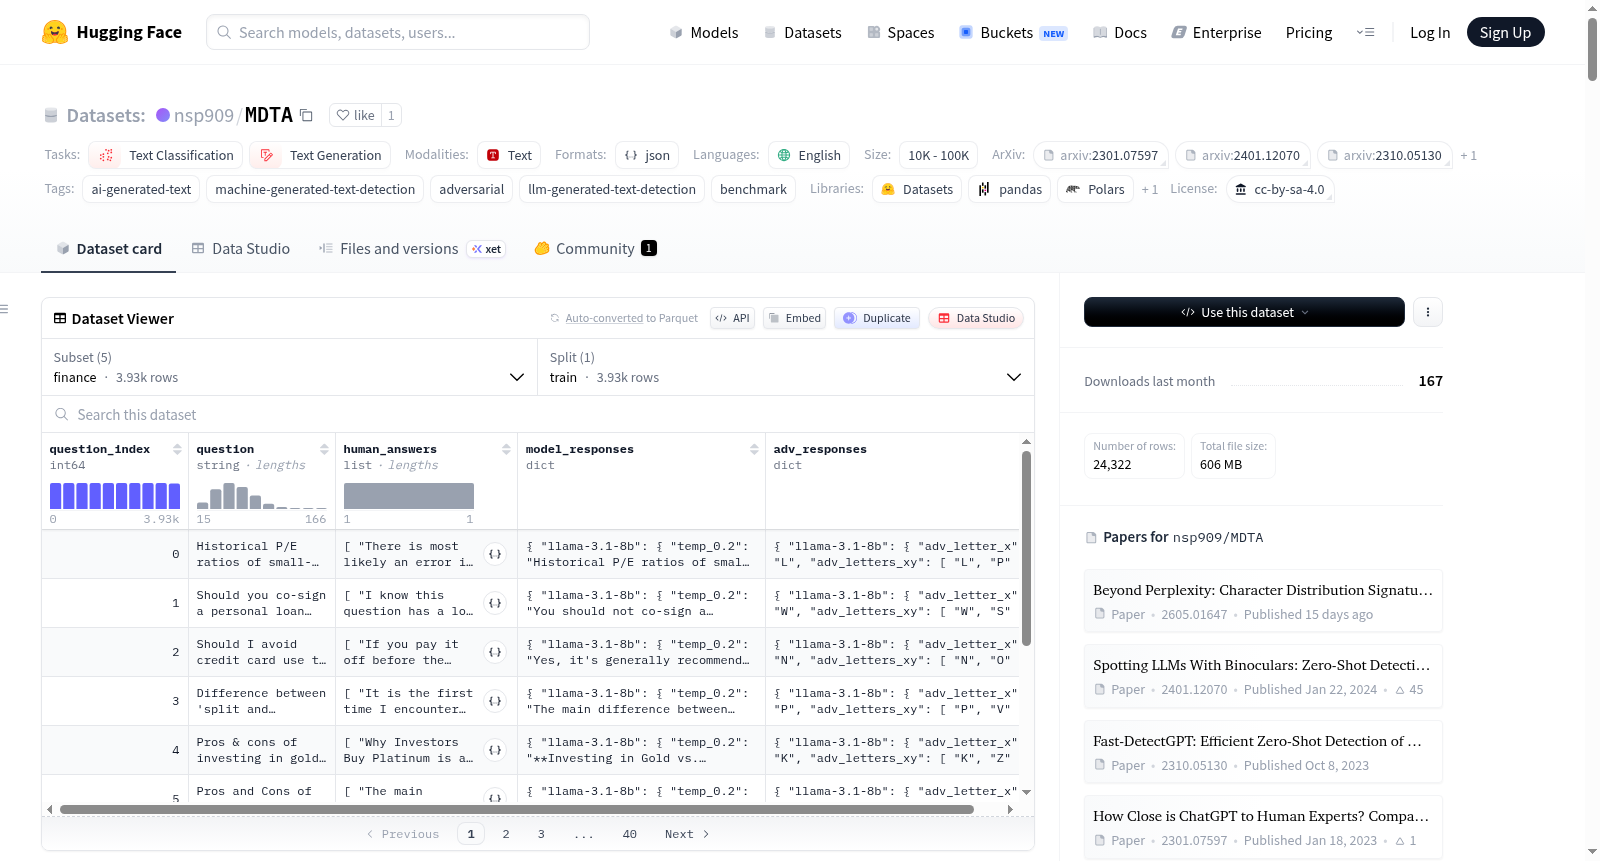
MDTA是一个用于AI生成文本检测的基准数据集。它通过五个领域、四个开放权重模型和三个采样温度,将人类编写的答案与LLM生成的答案配对,并为每个LLM响应添加了三种对抗性改写(包括受限制的字母避免改写)。数据集包含24,322个对齐的问题(约642,000个文本样本,包括所有生成和对抗性响应)。问题和人类答案来源于HC3数据集;MDTA通过现代模型覆盖、温度变化和有针对性的对抗性增强扩展了HC3。
MDTA is a benchmark for AI-generated text detection. It pairs human-written and LLM-generated answers across five domains, four open-weights models, and three sampling temperatures, and augments each LLM response with three adversarial paraphrases (including constrained letter-avoidance rewrites). The dataset spans 24,322 prompt-aligned questions (around 642,000 text samples when counting all generated and adversarial responses). Questions and human answers are sourced from the HC3 dataset; MDTA extends HC3 with modern model coverage, temperature variation, and targeted adversarial augmentation.