corral-reports-october-runs-summary-v1
收藏资源简介:
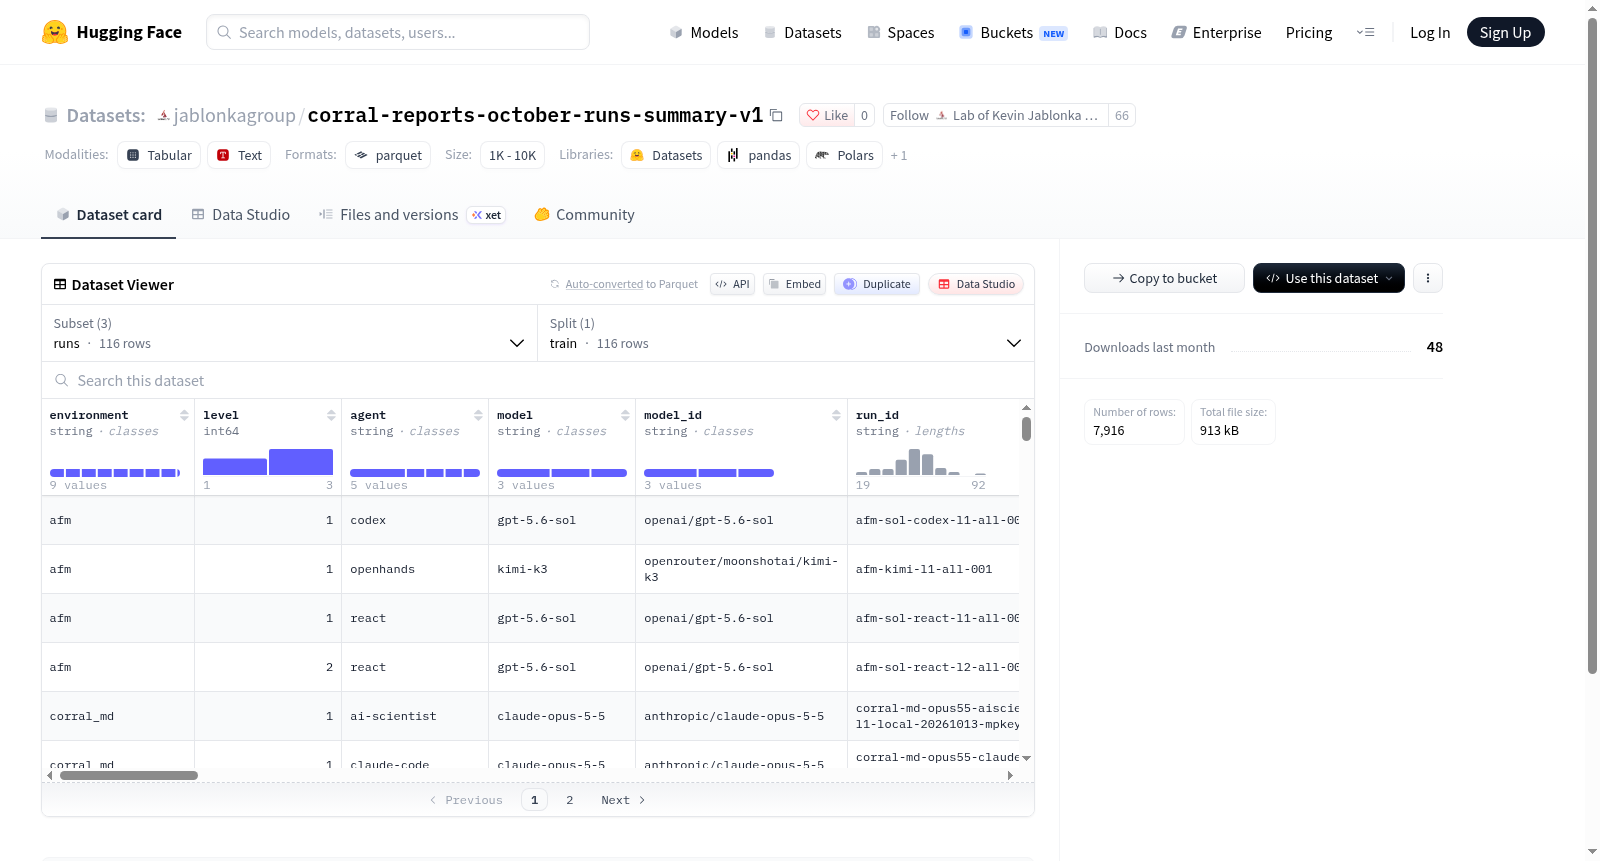
该数据集是面向智能体或模型在任务环境中运行表现评估的记录与汇总数据集,用于分析和比较不同智能体、模型在多种环境与级别下的任务执行效果。README 仅以 dataset_info 形式给出元数据,未提供自然语言背景说明。数据集包含三个配置:runs、tasks 和 trials,均只有 train 划分,数据文件分别位于 runs/train-*、tasks/train-* 和 trials/train-*。整体规模为 7,916 条样本,其中 runs 配置 116 条,tasks 配置 1,300 条,trials 配置 6,500 条;dataset_size 分别为 75,894、446,144、3,484,005 字节,总计 4,006,043 字节;download_size 分别为 48,301、77,270、780,301 字节,总计 905,872 字节。三个配置共享 environment、level、agent、model、model_id 和 run_id 标识维度,用于描述运行环境、级别、智能体、模型、模型 ID 与运行 ID。runs 配置提供运行级聚合结果,字段包括 tasks、trials_per_task、trials、passes、error_trials、agent_error_trials、infrastructure_error_trials、average_score、pass_at_1 至 pass_at_5、pass_hat_1 至 pass_hat_5、average_duration_s、total_duration_s、wall_clock_s、total_input_tokens、total_output_tokens、total_reasoning_tokens、total_llm_calls、total_tool_calls、total_agent_steps、generated_at、report_file、report_sha256 和 langfuse_session_url。tasks 配置提供任务级统计,额外包含 task_id、success_rate,并记录每个任务的 trials、passes、error_trials、average_score、pass_at_1 至 pass_at_5、pass_hat_1 至 pass_hat_5、average_duration_s、total_duration_s、total_input_tokens、total_output_tokens、total_reasoning_tokens、total_llm_calls、total_tool_calls 和 total_agent_steps。trials 配置提供单次试验级记录,额外包含 trial、execution_id、score、success、surrendered、error、error_category、error_kind、duration_s、tool_execution_duration_s、input_tokens、output_tokens、reasoning_tokens、llm_calls、tool_calls、agent_steps、langfuse_session_id、langfuse_trace_id 和 langfuse_trace_url。从字段结构可推断,该数据集可用于分析不同智能体和模型在多种环境与级别下的任务执行表现,包括通过率、成功率、平均得分、错误类型与错误归属、耗时、token 消耗、LLM 调用、工具调用和智能体步数等,并可借助 Langfuse 会话或追踪字段关联运行记录。
This dataset is a recording and aggregation dataset for evaluating the runtime performance of agents or models in task environments. The README provides metadata only in dataset_info form and does not include natural-language background notes. The dataset contains three configurations: runs, tasks, and trials, all with only a train split, with data files located at runs/train-*, tasks/train-*, and trials/train-*. The overall size is 7,916 samples: 116 in runs, 1,300 in tasks, and 6,500 in trials. Their dataset_size values are 75,894, 446,144, and 3,484,005 bytes respectively, totaling 4,006,043 bytes; their download_size values are 48,301, 77,270, and 780,301 bytes respectively, totaling 905,872 bytes. The three configurations share identifier dimensions including environment, level, agent, model, model_id, and run_id, describing the execution environment, level, agent, model, model ID, and run ID. The runs configuration provides run-level aggregate results, with fields including tasks, trials_per_task, trials, passes, error_trials, agent_error_trials, infrastructure_error_trials, average_score, pass_at_1 through pass_at_5, pass_hat_1 through pass_hat_5, average_duration_s, total_duration_s, wall_clock_s, total_input_tokens, total_output_tokens, total_reasoning_tokens, total_llm_calls, total_tool_calls, total_agent_steps, generated_at, report_file, report_sha256, and langfuse_session_url. The tasks configuration provides task-level statistics, additionally including task_id and success_rate, and records each tasks trials, passes, error_trials, average_score, pass_at_1 through pass_at_5, pass_hat_1 through pass_hat_5, average_duration_s, total_duration_s, total_input_tokens, total_output_tokens, total_reasoning_tokens, total_llm_calls, total_tool_calls, and total_agent_steps. The trials configuration provides individual trial-level records, additionally including trial, execution_id, score, success, surrendered, error, error_category, error_kind, duration_s, tool_execution_duration_s, input_tokens, output_tokens, reasoning_tokens, llm_calls, tool_calls, agent_steps, langfuse_session_id, langfuse_trace_id, and langfuse_trace_url. From the field structure, it can be inferred that the dataset can be used to analyze the task execution performance of different agents and models across multiple environments and levels, including pass rate, success rate, average score, error types and error attribution, duration, token consumption, LLM calls, tool calls, and agent steps, and to associate run records via Langfuse session or trace fields.
数据集总结
基本信息
- 数据集页面:
https://huggingface.co/datasets/jablonkagroup/corral-reports-october-runs-summary-v1 - 配置数量:3
- 配置名称:runs、tasks、trials
- 数据划分:每个配置均包含 train 划分
配置汇总
| 配置 | 划分 | 样本数 | 划分字节数 | 下载大小 | 数据集大小 | 数据文件 |
|---|---|---|---|---|---|---|
| runs | train | 116 | 75,894 | 48,237 | 75,894 | https://huggingface.co/datasets/jablonkagroup/corral-reports-october-runs-summary-v1/resolve/main/runs/train-* |
| tasks | train | 1,300 | 446,144 | 77,262 | 446,144 | https://huggingface.co/datasets/jablonkagroup/corral-reports-october-runs-summary-v1/resolve/main/tasks/train-* |
| trials | train | 6,500 | 3,483,959 | 780,307 | 3,483,959 | https://huggingface.co/datasets/jablonkagroup/corral-reports-october-runs-summary-v1/resolve/main/trials/train-* |
字段结构
runs
- string:environment、agent、model、model_id、run_id、generated_at、report_file、report_sha256、langfuse_session_url
- int64:level、tasks、trials_per_task、trials、passes、error_trials、agent_error_trials、infrastructure_error_trials、total_input_tokens、total_output_tokens、total_reasoning_tokens、total_llm_calls、total_tool_calls、total_agent_steps
- float64:average_score、pass_at_1、pass_hat_1、pass_at_2、pass_hat_2、pass_at_3、pass_hat_3、pass_at_4、pass_hat_4、pass_at_5、pass_hat_5、average_duration_s、total_duration_s、wall_clock_s
tasks
- string:environment、agent、model、model_id、run_id、task_id
- int64:level、trials、passes、error_trials、total_input_tokens、total_output_tokens、total_reasoning_tokens、total_llm_calls、total_tool_calls、total_agent_steps
- float64:average_score、success_rate、pass_at_1、pass_hat_1、pass_at_2、pass_hat_2、pass_at_3、pass_hat_3、pass_at_4、pass_hat_4、pass_at_5、pass_hat_5、average_duration_s、total_duration_s
trials
- string:environment、agent、model、model_id、run_id、task_id、execution_id、error、error_category、error_kind、langfuse_session_id、langfuse_trace_id、langfuse_trace_url
- int64:level、trial、input_tokens、output_tokens、reasoning_tokens、llm_calls、tool_calls、agent_steps
- float64:score、duration_s、tool_execution_duration_s
- bool:success、surrendered