stefanocarrera/autophagycode_D_he_train-mercury_Qwen3-8B_strategy_trust_t0.75_g7_run1_metrics
收藏资源简介:
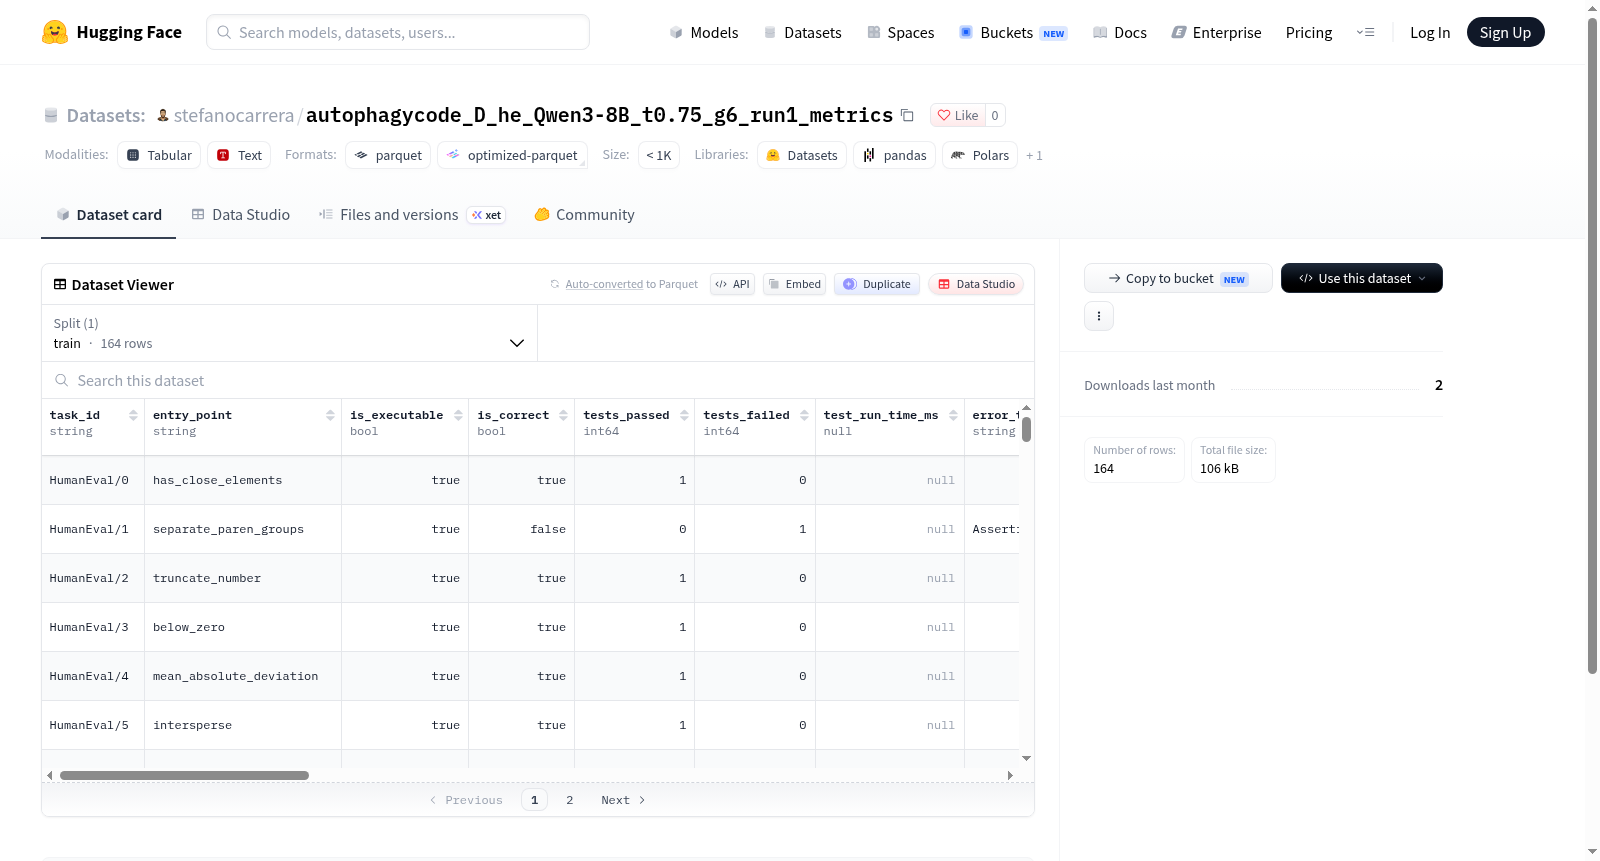
--- dataset_info: features: - name: task_id dtype: string - name: entry_point dtype: string - name: is_executable dtype: bool - name: is_correct dtype: bool - name: tests_passed dtype: int64 - name: tests_failed dtype: int64 - name: test_run_time_ms dtype: 'null' - name: error_type dtype: string - name: halstead_vocabulary dtype: int64 - name: halstead_length dtype: int64 - name: halstead_volume dtype: float64 - name: halstead_difficulty dtype: float64 - name: halstead_effort dtype: float64 - name: halstead_time dtype: float64 - name: cyclomatic_complexity dtype: int64 - name: maintainability_index dtype: float64 - name: loc dtype: int64 - name: sloc dtype: int64 - name: comment_percentage dtype: float64 - name: TTR dtype: float64 - name: token_dict dtype: string - name: shannon_entropy dtype: float64 - name: mean_predictive_entropy dtype: float64 - name: max_predictive_entropy dtype: float64 - name: n_func_defined dtype: int64 - name: entry_point_repeated dtype: bool splits: - name: train num_bytes: 234294 num_examples: 164 download_size: 101855 dataset_size: 234294 configs: - config_name: default data_files: - split: train path: data/train-* ---
This dataset contains data related to programming tasks, with each entry having a unique task ID (task_id) and an entry point (entry_point), and records whether the code is executable (is_executable) and correct (is_correct). It provides test result metrics, including the number of tests passed and failed (tests_passed, tests_failed), as well as code quality measures such as Halstead complexity metrics (vocabulary, length, volume, difficulty, effort, time), cyclomatic complexity, maintainability index, lines of code (loc, sloc), comment percentage, lexical diversity (TTR), entropy values (shannon_entropy, mean_predictive_entropy, max_predictive_entropy), and the number of function definitions (n_func_defined). The data also includes error type (error_type) and entry point repetition information (entry_point_repeated). The dataset is split into a training set (train) with 164 examples, a total size of approximately 234KB, and a download size of approximately 102KB.