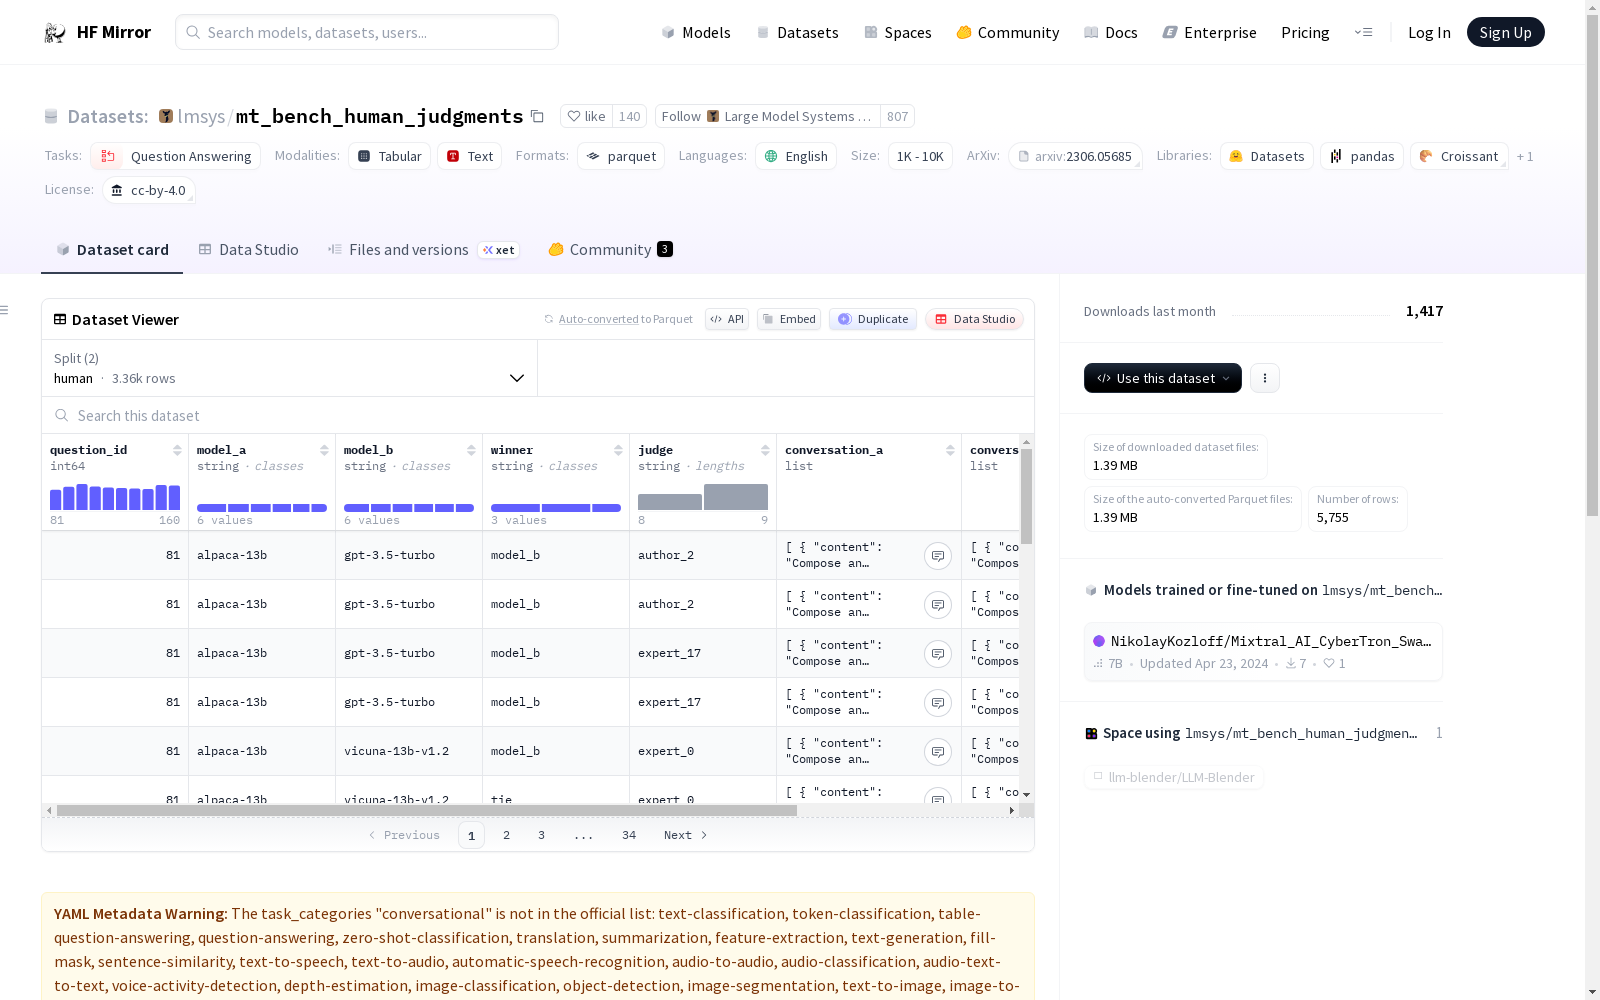
lmsys/mt_bench_human_judgments
收藏资源简介:
--- dataset_info: features: - name: question_id dtype: int64 - name: model_a dtype: string - name: model_b dtype: string - name: winner dtype: string - name: judge dtype: string - name: conversation_a list: - name: content dtype: string - name: role dtype: string - name: conversation_b list: - name: content dtype: string - name: role dtype: string - name: turn dtype: int64 splits: - name: human num_bytes: 15003469 num_examples: 3355 - name: gpt4_pair num_bytes: 10679650 num_examples: 2400 download_size: 1388888 dataset_size: 25683119 license: cc-by-4.0 task_categories: - conversational - question-answering language: - en size_categories: - 1K<n<10K --- ## Content This dataset contains 3.3K expert-level pairwise human preferences for model responses generated by 6 models in response to 80 MT-bench questions. The 6 models are GPT-4, GPT-3.5, Claud-v1, Vicuna-13B, Alpaca-13B, and LLaMA-13B. The annotators are mostly graduate students with expertise in the topic areas of each of the questions. The details of data collection can be found in our [paper](https://arxiv.org/abs/2306.05685). ## Agreement Calculation This Colab [notebook](https://colab.research.google.com/drive/1ctgygDRJhVGUJTQy8-bRZCl1WNcT8De6?usp=sharing) shows how to compute the agreement between humans and GPT-4 judge with the dataset. Our results show that humans and GPT-4 judge achieve over 80\% agreement, the same level of agreement between humans. ## Citation ``` @misc{zheng2023judging, title={Judging LLM-as-a-judge with MT-Bench and Chatbot Arena}, author={Lianmin Zheng and Wei-Lin Chiang and Ying Sheng and Siyuan Zhuang and Zhanghao Wu and Yonghao Zhuang and Zi Lin and Zhuohan Li and Dacheng Li and Eric. P Xing and Hao Zhang and Joseph E. Gonzalez and Ion Stoica}, year={2023}, eprint={2306.05685}, archivePrefix={arXiv}, primaryClass={cs.CL} } ```
数据集详情: 特征: - 名称:question_id,数据类型:64位整数(int64) - 名称:model_a,数据类型:字符串(string) - 名称:model_b,数据类型:字符串(string) - 名称:winner,数据类型:字符串(string) - 名称:judge,数据类型:字符串(string) - 名称:conversation_a:列表类型,包含: - 名称:content,数据类型:字符串(string) - 名称:role,数据类型:字符串(string) - 名称:conversation_b:列表类型,包含: - 名称:content,数据类型:字符串(string) - 名称:role,数据类型:字符串(string) - 名称:turn,数据类型:64位整数(int64) 数据划分: - 名称:human,字节数:15003469,样本数:3355 - 名称:gpt4_pair,字节数:10679650,样本数:2400 下载大小:1388888 数据集总大小:25683119 许可证:CC BY 4.0(知识共享署名4.0协议) 任务类别: - 对话式 - 问答式 语言: - 英语 规模类别: - 1K<n<10K ## 数据集概况 本数据集包含针对80个MT-bench(MT基准测试)问题生成的模型回复所对应的3355条专家级成对人类偏好标注数据,涉及6个大语言模型(LLM)的输出对比。涉及的6个模型分别为GPT-4、GPT-3.5、Claud-v1、Vicuna-13B、Alpaca-13B与LLaMA-13B。本次标注的标注者多为具备对应问题主题领域专业知识的研究生。数据采集的详细细节可参阅我们的[论文]("https://arxiv.org/abs/2306.05685")。 ## 一致性计算 本Colab提供的[协作笔记]("https://colab.research.google.com/drive/1ctgygDRJhVGUJTQy8-bRZCl1WNcT8De6?usp=sharing")演示了如何利用本数据集计算人类标注者与GPT-4评判器之间的一致性水平。实验结果表明,人类与GPT-4评判器的一致性超过80%,该水准等同于人类标注者之间的一致性程度。 ## 引用 @misc{zheng2023judging, title={使用MT-Bench与Chatbot Arena评判大语言模型作为评判器}, author={Lianmin Zheng and Wei-Lin Chiang and Ying Sheng and Siyuan Zhuang and Zhanghao Wu and Yonghao Zhuang and Zi Lin and Zhuohan Li and Dacheng Li and Eric. P Xing and Hao Zhang and Joseph E. Gonzalez and Ion Stoica}, year={2023}, eprint={2306.05685}, archivePrefix={arXiv}, primaryClass={cs.CL} }
数据集概述
数据集信息
-
特征(Features):
question_id: 数据类型为int64model_a: 数据类型为stringmodel_b: 数据类型为stringwinner: 数据类型为stringjudge: 数据类型为stringconversation_a: 包含两个子特征content: 数据类型为stringrole: 数据类型为string
conversation_b: 包含两个子特征content: 数据类型为stringrole: 数据类型为string
turn: 数据类型为int64
-
数据分割(Splits):
human: 大小为 15003469 字节,包含 3355 个样本gpt4_pair: 大小为 10679650 字节,包含 2400 个样本
-
下载大小(Download Size): 1388888 字节
-
数据集大小(Dataset Size): 25683119 字节
-
许可证(License): cc-by-4.0
-
任务类别(Task Categories):
- 对话(conversational)
- 问答(question-answering)
-
语言(Language): 英语(en)
-
大小类别(Size Categories): 1K<n<10K
数据集内容
- 包含 3.3K 专家级的人类偏好数据,用于评估 6 个模型对 80 个 MT-bench 问题的响应。
- 涉及的模型包括 GPT-4, GPT-3.5, Claud-v1, Vicuna-13B, Alpaca-13B, 和 LLaMA-13B。
- 注释者主要是具有相关问题领域专业知识的研究生。
数据集用途
- 用于计算人类与 GPT-4 判断者之间的协议,显示两者之间的协议度超过 80%。