LaTeX_OCR
收藏资源简介:
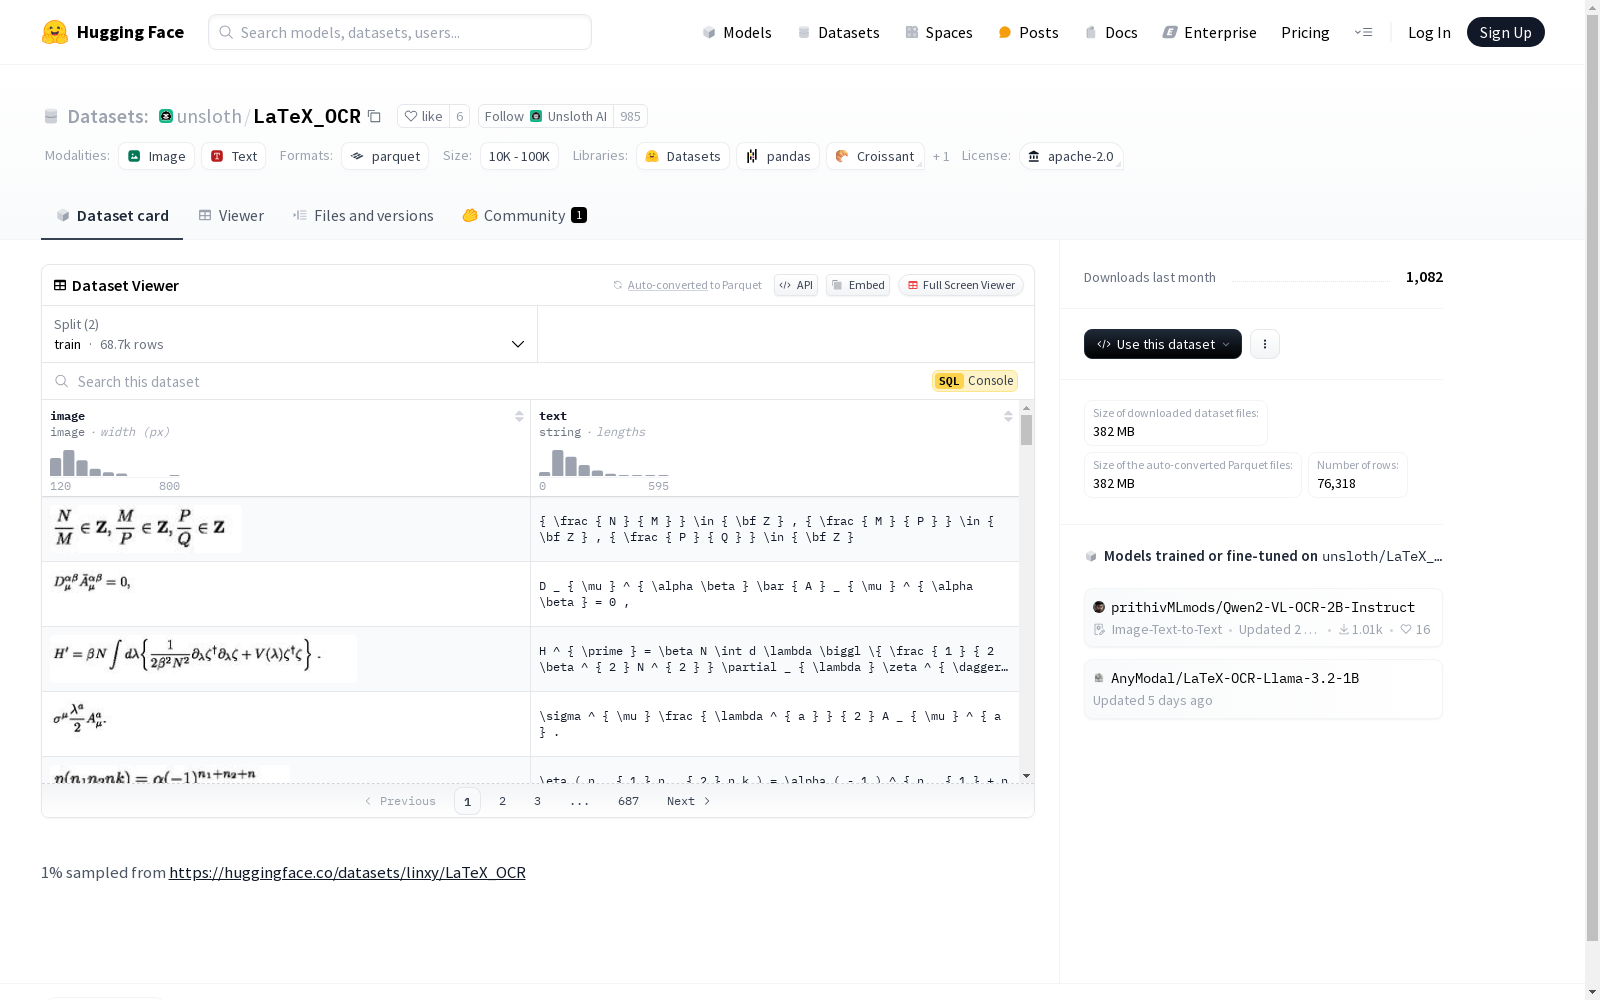
该数据集包含图像和文本两种特征。图像特征的类型为图像,文本特征的类型为字符串。数据集分为训练集和测试集,训练集包含68686个样本,测试集包含7632个样本。数据集的总下载大小为382010447字节,总数据集大小为384311363.86字节。数据集的配置名为'default',数据文件路径分别为'data/train-*'和'data/test-*'。数据集的许可证为Apache 2.0。
This dataset comprises two types of features: image features and text features. Image features are of the image data type, while text features are string-type data. The dataset is split into a training set and a test set, where the training set contains 68686 samples and the test set contains 7632 samples. The total download size of the dataset is 382010447 bytes, and the total size of the complete dataset is 384311363.86 bytes. The dataset configuration is named 'default', and the data file paths are 'data/train-*' and 'data/test-*' respectively. The license of this dataset is Apache 2.0.
LaTeX_OCR 数据集概述
数据集信息
特征
- image: 图像数据,数据类型为
image。 - text: 文本数据,数据类型为
string。
数据分割
- train: 训练集,包含 68686 个样本,占用 345879330.24 字节。
- test: 测试集,包含 7632 个样本,占用 38432033.62 字节。
数据大小
- 下载大小: 382010447 字节。
- 数据集总大小: 384311363.86 字节。
配置
- config_name:
default- data_files:
- train:
data/train-* - test:
data/test-*
- train:
- data_files:
许可证
- license:
apache-2.0
数据来源
- 数据集是从 https://huggingface.co/datasets/linxy/LaTeX_OCR 中抽取的 1% 样本。