laion-emotional-trajectory-t80
收藏资源简介:
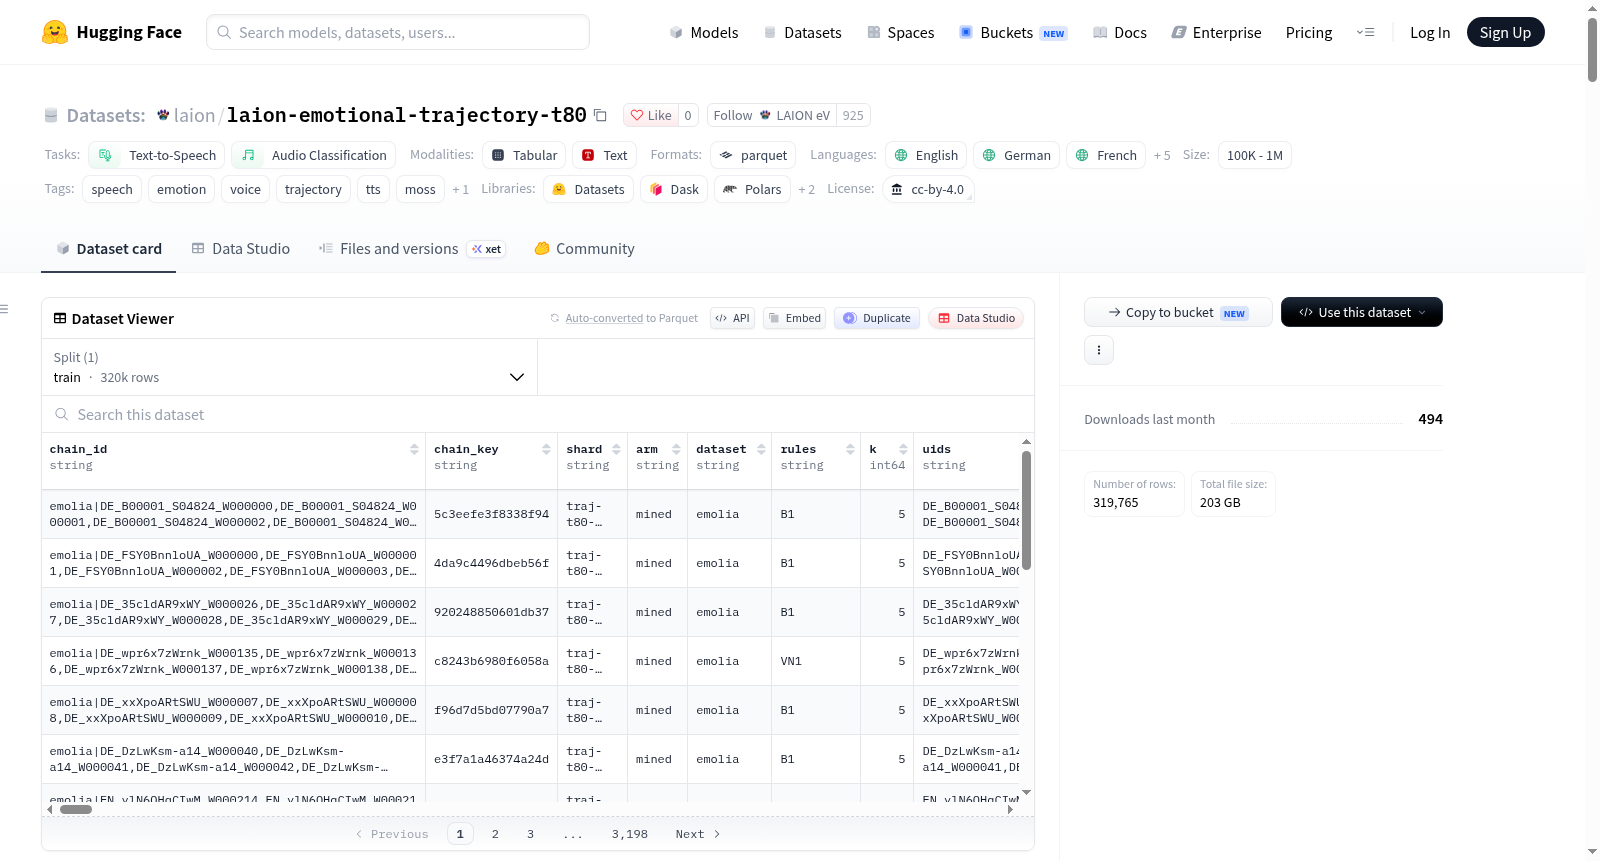
LAION情感轨迹语音数据集(T≥0.80层级)是一个用于表达性文本转语音(TTS)和音频分类任务的大规模语音数据集。该数据集包含319,765个交叉淡入淡出的语音轨迹,总计4,482音频小时,源自1,598,825个原始片段。每个轨迹是由同一说话人的5个连续话语组成的短序列,其测量到的情感或声音特征从语料库分布的一端单调移动到另一端,且至少跨越整个语料库范围的80%,相邻片段之间的步长不超过25%。音频片段以等功率交叉淡入淡出方式连接成连续音频文件,并使用MOSS-Audio-Tokenizer-v2重新编码为12个码本×1024的token序列,帧率为12.5 fps。每个轨迹携带两级描述:内联的逐片段剧本式描述(包含情感和声音描述符)以及基于渲染音频整体评分的通用描述(分为仅含VoiceNet维度的a变体和含情感词的b变体)。数据集主要来源于vprof_vc(利用Chatterbox-VC和SIDON生成的合成语音配置文件)和emolia(YODAS衍生的情感语音),其中vprof_vc占99.99%。语言主要为英语和德语,但需注意轨迹的语言标签仅取自第一个片段,实际约92.6%的轨迹混合了两种语言。数据集采用WebDataset格式存储,每个tar包包含音频、MOSS token和JSON元数据,同时提供parquet元数据表便于筛选。适用任务包括情感语音合成、语音情感识别、声音特征变化建模等。数据集采用CC-BY-4.0许可证,但合成语音部分有特殊说明。注意:vprof_vc轨迹是构造而非真实观察,情感分类器绝对精度较低,且情感子句因40维门控机制而普遍存在。
The LAION Emotional Trajectory Speech Dataset (T≥0.80 tier) is a large-scale speech dataset for expressive text-to-speech (TTS) and audio classification tasks. It contains 319,765 cross-faded speech trajectories totaling 4,482 audio hours, derived from 1,598,825 original segments. Each trajectory is a short sequence of 5 consecutive utterances from the same speaker, where the measured emotional or voice characteristics monotonically shift from one end of the corpus distribution to the other, spanning at least 80% of the entire corpus range, with a step size between adjacent segments not exceeding 25%. Audio segments are concatenated into continuous audio files using equal-power cross-fading and re-encoded into 12 codebooks × 1024 token sequences using MOSS-Audio-Tokenizer-v2 at a frame rate of 12.5 fps. Each trajectory carries two levels of description: inline per-segment script descriptions (including emotion and voice descriptors) and a general description based on overall rendering audio scoring (divided into a variant with only VoiceNet dimensions and a b variant with emotional words). The dataset mainly originates from vprof_vc (synthetic speech profiles generated using Chatterbox-VC and SIDON) and emolia (emotional speech derived from YODAS), with vprof_vc accounting for 99.99%. The languages are primarily English and German, but note that the language label of each trajectory is taken only from the first segment; in reality, approximately 92.6% of trajectories mix both languages. The dataset is stored in WebDataset format, with each tar package containing audio, MOSS tokens, and JSON metadata, along with a parquet metadata table for easy filtering. Applicable tasks include emotional speech synthesis, speech emotion recognition, and voice feature change modeling. The dataset is licensed under CC-BY-4.0, with special notes for the synthetic speech portion. Note: vprof_vc trajectories are constructed rather than real observations, the absolute accuracy of emotion classifiers is low, and emotional subclauses are ubiquitous due to the 40-dimensional gating mechanism.
LAION Emotional-Trajectory Speech — Tier T≥0.80 数据集概述
基本信息
- 数据集名称: LAION Emotional-Trajectory Speech — Tier T≥0.80
- 许可证: CC-BY-4.0
- 任务类型: 文本转语音 (text-to-speech)、音频分类 (audio-classification)
- 语言: 英语、德语、法语、西班牙语、意大利语、荷兰语、波兰语、葡萄牙语
- 数据规模: 100K—1M 条数据
- 标签: speech, emotion, voice, trajectory, tts, moss, webdataset
核心内容
- 数据量: 319,765 条交叉淡化语音轨迹,总计 4,482 音频小时,包含 1,598,825 个源片段
- 核心概念: "轨迹"指由同一位说话者连续说出的 5 个话语组成的短序列,其情感或语音特征从语料库分布的一端单调移动至另一端
- 关键特性: 每条链在其命名维度上跨越至少 80% 的语料库范围,且相邻片段之间步长不超过 25%
分层体系
数据集中设置了严格嵌套的分层标准(T≥0.20 至 T≥0.80)。本发布为 T≥0.80 层级,是最高标准层。更高层级是低层级的严格子集,因此可在 T≥0.20 上训练、在 T≥0.80 上评估,无需重新下载。
| 层级 | 链数 | 小时 | en% | de% | 其他% |
|---|---|---|---|---|---|
| T≥0.80(本发布) | 319,765 | 4,531 | 59.6 | 40.4 | 0.0 |
构建方式
- 资格规则: 通过四种规则衡量(B1、AB2、PXR、VN1),所有规则要求步长上限 C=0.25
- 说话者筛选(严格且无转换): 要求相邻片段余弦相似度≥0.80,且所有片段与首片段余弦相似度≥0.80;不满足条件的链会被剔除
- 渲染方式: 所有片段统一电平至 −20.0 dBFS RMS,接缝处使用 150 ms 等功率交叉淡化(热点处缩短至 100 ms),48 kHz 单声道,MP3 96 kbps CBR
再标记化
- 交叉淡化后的拼接属于新音频,因此使用 MOSS-Audio-Tokenizer-v2 重新编码
- 12 个码本 ×1024,每秒 12.5 帧,每帧 12 个 token(80 ms)
- 存储为
uint16 [T, 12]格式的<chain>.moss.npy文件
标注说明
双层字幕
- 逐段内联: 以剧本形式呈现
(情感 · 语音描述) 所说内容,每片段一行 - 整体概括: 基于渲染后的音频评分生成两种变体
caption_general_a: 仅含 VoiceNet 维度,无情感词caption_general_b: 含 VoiceNet 维度+前 2–3 种情感
重要警告
- 括号标注含义(需特别区分): 在
vprof_vc来源中,约 37.7% 的括号是合成提示中的爆发方向而非实际检测,因此每段区分burst_detected(实际检测)与burst_scripted(请求但未确认) - 语言标记: 链的
lang_iso仅取第一个片段,实测 92.6% 的链为混合语言(德语+英语),需根据langs/lang_mixed字段过滤
数据集组成
| 数据集 | 链数 | 许可证 |
|---|---|---|
vprof_vc |
319,650 | 生成数据(见注释) |
emolia |
115 | CC-BY-4.0 |
本发布为 CLEAN 版本,已排除来源不明或无法公开再分发的数据。
诚实局限性
- 轨迹是构造的而非观察到的: 语音配置文件轨迹由同一克隆声音对五个不同文本的独立录制构成,顺序由打包器施加
- 五种情感无法成为双面规则下的轨迹端点: Awe、Distress、Sadness、Disappointment、Helplessness 的原始得分过度零膨胀
- 情感评分器绝对能力较弱: 对语音配置文件的 top-1 准确率仅 8.0%(随机水平 2.5%)
- 约 98% 的链至少包含一种情感: 这是 40 维门控的算术结果,不代表每条链都富有情感
文件格式与加载
数据集以 WebDataset 格式分发(traj-t80-NNNNN.tar),包含 MP3 音频、JSON 元数据和 MOSS token npy 文件,另有 parquet 元数据文件及验证文件。支持通过 Hugging Face 数据集库加载,提供 Python 示例代码。