New Yorker Caption Contest Dataset
收藏资源简介:
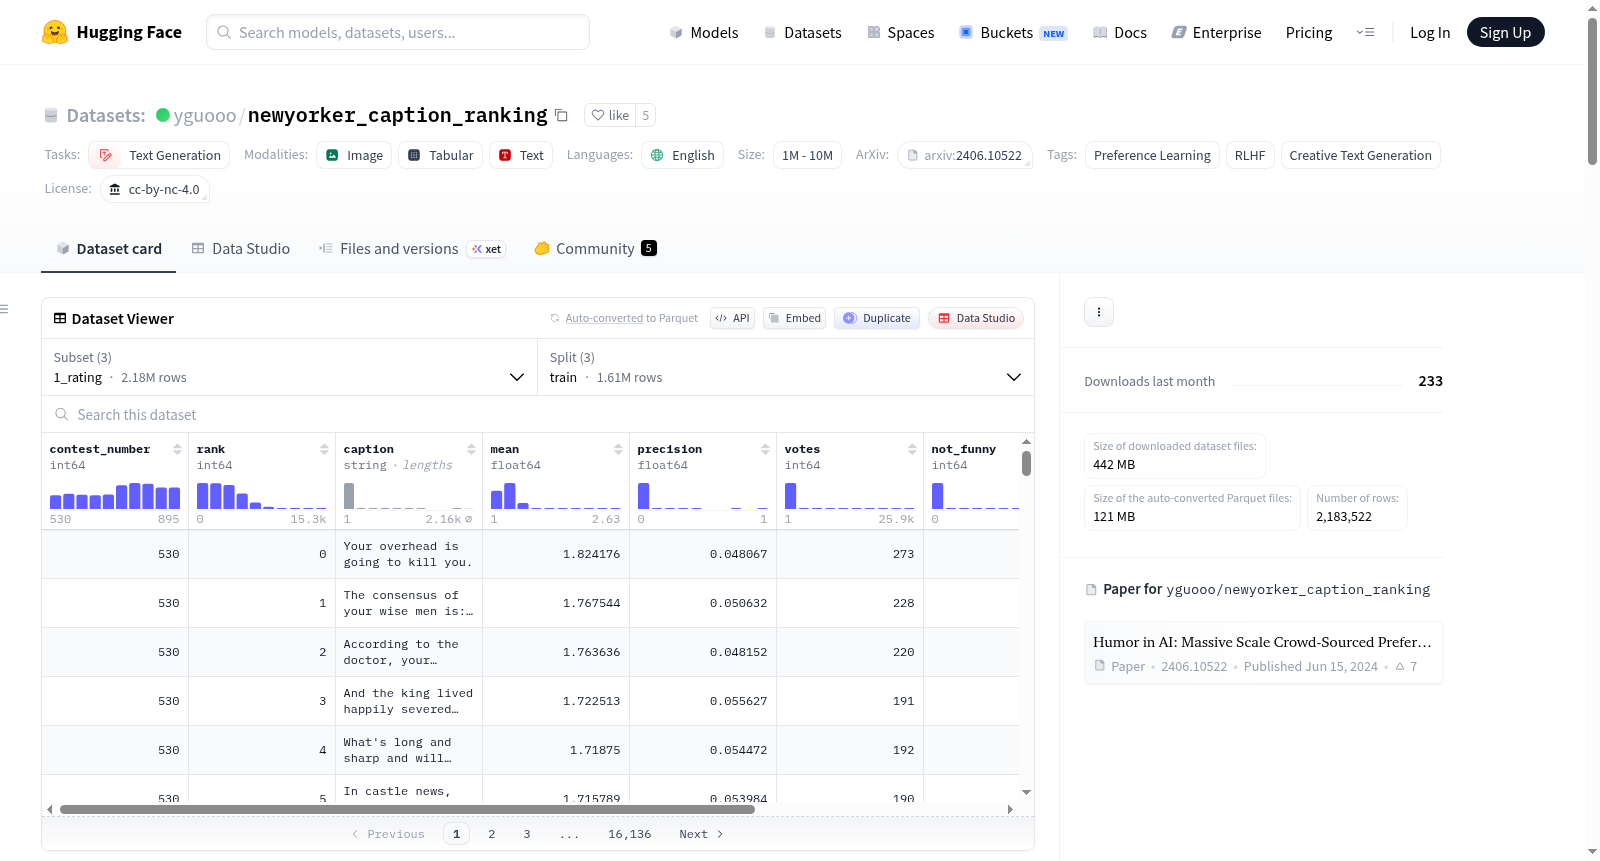
本数据集名为‘New Yorker Caption Contest Dataset’,由威斯康星大学麦迪逊分校创建,包含超过250万条来自《纽约客》每周漫画标题竞赛的人类评分数据。数据集涵盖了过去八年的竞赛内容,总计超过2.5亿次人类评价。创建过程中,通过众包方式收集评分,使用多臂老虎机算法优化展示效果。该数据集主要用于支持大型语言模型和基于偏好的微调算法的发展,特别是在幽默标题生成领域的应用。
This dataset is named the New Yorker Caption Contest Dataset, which was created by the University of Wisconsin-Madison. It contains over 2.5 million human rating records from The New Yorker's weekly cartoon caption contests, covering contests from the past eight years and accumulating a total of more than 250 million human ratings. During the dataset construction, ratings were collected via crowdsourcing, and a multi-armed bandit algorithm was used to optimize the display of contest content. This dataset is primarily intended to support the development of large language models and preference-based fine-tuning algorithms, especially for applications in the field of humorous caption generation.