allenai/common_gen
收藏资源简介:
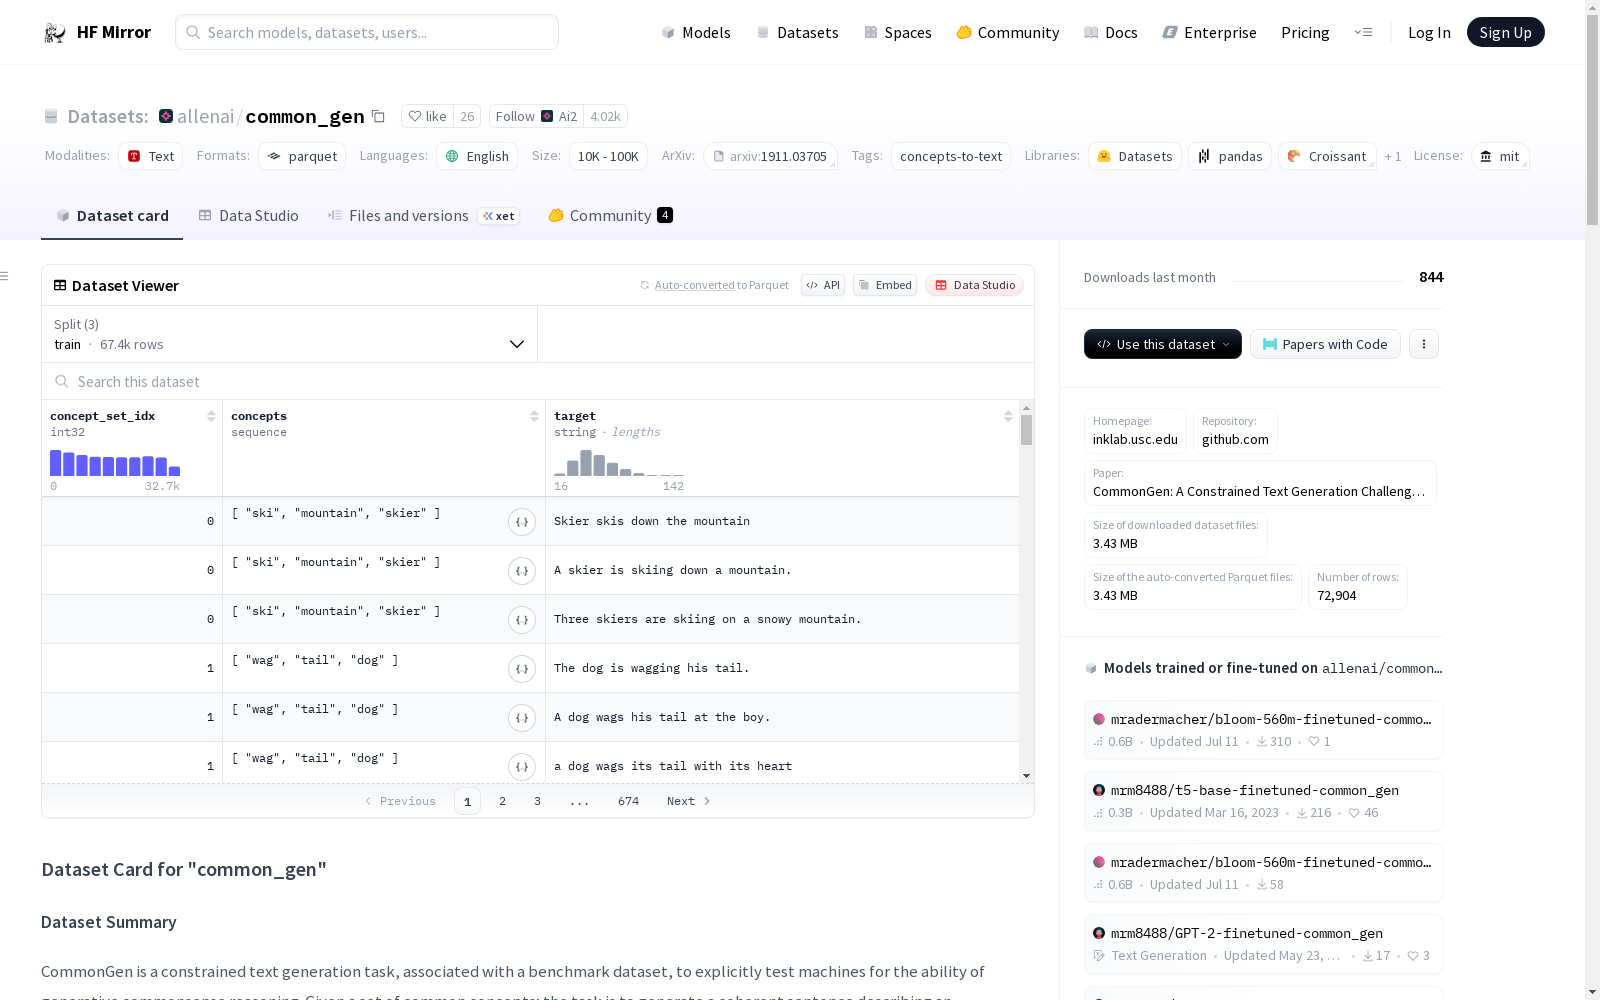
--- annotations_creators: - crowdsourced language_creators: - found - crowdsourced language: - en license: - mit multilinguality: - monolingual size_categories: - 10K<n<100K source_datasets: - original task_categories: - text2text-generation task_ids: [] paperswithcode_id: commongen pretty_name: CommonGen tags: - concepts-to-text dataset_info: features: - name: concept_set_idx dtype: int32 - name: concepts sequence: string - name: target dtype: string splits: - name: train num_bytes: 6724166 num_examples: 67389 - name: validation num_bytes: 408740 num_examples: 4018 - name: test num_bytes: 77518 num_examples: 1497 download_size: 3434865 dataset_size: 7210424 configs: - config_name: default data_files: - split: train path: data/train-* - split: validation path: data/validation-* - split: test path: data/test-* --- # Dataset Card for "common_gen" ## Table of Contents - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Supported Tasks and Leaderboards](#supported-tasks-and-leaderboards) - [Languages](#languages) - [Dataset Structure](#dataset-structure) - [Data Instances](#data-instances) - [Data Fields](#data-fields) - [Data Splits](#data-splits) - [Dataset Creation](#dataset-creation) - [Curation Rationale](#curation-rationale) - [Source Data](#source-data) - [Annotations](#annotations) - [Personal and Sensitive Information](#personal-and-sensitive-information) - [Considerations for Using the Data](#considerations-for-using-the-data) - [Social Impact of Dataset](#social-impact-of-dataset) - [Discussion of Biases](#discussion-of-biases) - [Other Known Limitations](#other-known-limitations) - [Additional Information](#additional-information) - [Dataset Curators](#dataset-curators) - [Licensing Information](#licensing-information) - [Citation Information](#citation-information) - [Contributions](#contributions) ## Dataset Description - **Homepage:** [https://inklab.usc.edu/CommonGen/index.html](https://inklab.usc.edu/CommonGen/index.html) - **Repository:** https://github.com/INK-USC/CommonGen - **Paper:** [CommonGen: A Constrained Text Generation Challenge for Generative Commonsense Reasoning](https://arxiv.org/abs/1911.03705) - **Point of Contact:** [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) - **Size of downloaded dataset files:** 1.85 MB - **Size of the generated dataset:** 7.21 MB - **Total amount of disk used:** 9.06 MB ### Dataset Summary CommonGen is a constrained text generation task, associated with a benchmark dataset, to explicitly test machines for the ability of generative commonsense reasoning. Given a set of common concepts; the task is to generate a coherent sentence describing an everyday scenario using these concepts. CommonGen is challenging because it inherently requires 1) relational reasoning using background commonsense knowledge, and 2) compositional generalization ability to work on unseen concept combinations. Our dataset, constructed through a combination of crowd-sourcing from AMT and existing caption corpora, consists of 30k concept-sets and 50k sentences in total. ### Supported Tasks and Leaderboards [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Languages [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## Dataset Structure ### Data Instances #### default - **Size of downloaded dataset files:** 1.85 MB - **Size of the generated dataset:** 7.21 MB - **Total amount of disk used:** 9.06 MB An example of 'train' looks as follows. ``` { "concept_set_idx": 0, "concepts": ["ski", "mountain", "skier"], "target": "Three skiers are skiing on a snowy mountain." } ``` ### Data Fields The data fields are the same among all splits. #### default - `concept_set_idx`: a `int32` feature. - `concepts`: a `list` of `string` features. - `target`: a `string` feature. ### Data Splits | name |train|validation|test| |-------|----:|---------:|---:| |default|67389| 4018|1497| ## Dataset Creation ### Curation Rationale [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Source Data #### Initial Data Collection and Normalization [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### Who are the source language producers? [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Annotations #### Annotation process [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### Who are the annotators? [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Personal and Sensitive Information [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## Considerations for Using the Data ### Social Impact of Dataset [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Discussion of Biases [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Other Known Limitations [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## Additional Information ### Dataset Curators [More Information Needed](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### Licensing Information The dataset is licensed under [MIT License](https://github.com/INK-USC/CommonGen/blob/master/LICENSE). ### Citation Information ```bib @inproceedings{lin-etal-2020-commongen, title = "{C}ommon{G}en: A Constrained Text Generation Challenge for Generative Commonsense Reasoning", author = "Lin, Bill Yuchen and Zhou, Wangchunshu and Shen, Ming and Zhou, Pei and Bhagavatula, Chandra and Choi, Yejin and Ren, Xiang", booktitle = "Findings of the Association for Computational Linguistics: EMNLP 2020", month = nov, year = "2020", address = "Online", publisher = "Association for Computational Linguistics", url = "https://www.aclweb.org/anthology/2020.findings-emnlp.165", doi = "10.18653/v1/2020.findings-emnlp.165", pages = "1823--1840" } ``` ### Contributions Thanks to [@JetRunner](https://github.com/JetRunner), [@yuchenlin](https://github.com/yuchenlin), [@thomwolf](https://github.com/thomwolf), [@lhoestq](https://github.com/lhoestq) for adding this dataset.
annotations_creators: - 众包(crowdsourced) language_creators: - 公开采集(found) - 众包(crowdsourced) language: - 英语(en) license: - MIT许可证(MIT License) multilinguality: - 单语言(monolingual) size_categories: - 10000 < 样本数 < 100000 source_datasets: - 原始数据集(original) task_categories: - 文本到文本生成(text2text-generation) task_ids: [] paperswithcode_id: commongen pretty_name: CommonGen tags: - 概念到文本(concepts-to-text) dataset_info: features: - name: concept_set_idx dtype: int32 - name: concepts sequence: string - name: target dtype: string splits: - name: train num_bytes: 6724166 num_examples: 67389 - name: validation num_bytes: 408740 num_examples: 4018 - name: test num_bytes: 77518 num_examples: 1497 download_size: 3434865 dataset_size: 7210424 configs: - config_name: default data_files: - split: train path: data/train-* - split: validation path: data/validation-* - split: test path: data/test-* # "common_gen" 数据集卡片 ## 目录 - [数据集描述](#数据集描述) - [数据集概述](#数据集概述) - [支持任务与基准榜单](#支持任务与基准榜单) - [语言](#语言) - [数据集结构](#数据集结构) - [数据实例](#数据实例) - [数据字段](#数据字段) - [数据划分](#数据划分) - [数据集构建](#数据集构建) - [构建初衷](#构建初衷) - [源数据](#源数据) - [标注信息](#标注信息) - [个人与敏感信息](#个人与敏感信息) - [数据使用注意事项](#数据使用注意事项) - [数据集的社会影响](#数据集的社会影响) - [偏差讨论](#偏差讨论) - [其他已知局限性](#其他已知局限性) - [附加信息](#附加信息) - [数据集策展人](#数据集策展人) - [许可信息](#许可信息) - [引用信息](#引用信息) - [贡献者](#贡献者) ## 数据集描述 - **主页:** [https://inklab.usc.edu/CommonGen/index.html](https://inklab.usc.edu/CommonGen/index.html) - **代码仓库:** https://github.com/INK-USC/CommonGen - **相关论文:** [CommonGen:面向生成式常识推理的受限文本生成挑战](https://arxiv.org/abs/1911.03705) - **联系人:** [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) - **下载数据集文件大小:** 1.85 MB - **生成数据集大小:** 7.21 MB - **总磁盘占用:** 9.06 MB ### 数据集概述 CommonGen 是一项受限文本生成任务,配套基准数据集,用于精准测试机器的生成式常识推理能力。给定一组通用概念,任务要求生成一段连贯的日常场景语句,且必须使用给定的全部概念。 该任务具有较强挑战性,因为其本质上需要同时具备两项核心能力:1)依托背景常识知识完成关系推理;2)针对未见过的概念组合实现组合泛化。本数据集结合亚马逊机械 Turk(Amazon Mechanical Turk,AMT)众包任务与现有字幕语料库构建完成,总计包含3万个概念集与5万条语句。 ### 支持任务与基准榜单 [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 语言 [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## 数据集结构 ### 数据实例 #### default - **下载数据集文件大小:** 1.85 MB - **生成数据集大小:** 7.21 MB - **总磁盘占用:** 9.06 MB 训练集的一个示例如下: { "concept_set_idx": 0, "concepts": ["ski", "mountain", "skier"], "target": "三名滑雪者正在积雪的山地滑雪。" } ### 数据字段 所有数据划分的字段均保持一致。 #### default - `concept_set_idx`: 为 `int32` 类型特征。 - `concepts`: 为字符串列表类型特征。 - `target`: 为字符串类型特征。 ### 数据划分 | 划分名称 | 训练集 | 验证集 | 测试集 | |---------|-------:|-------:|-------:| | default | 67389 | 4018 | 1497 | ## 数据集构建 ### 构建初衷 [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 源数据 #### 初始数据采集与标准化 [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### 源语言生成者是谁? [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 标注信息 #### 标注流程 [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) #### 标注人员是谁? [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 个人与敏感信息 [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## 数据使用注意事项 ### 数据集的社会影响 [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 偏差讨论 [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 其他已知局限性 [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ## 附加信息 ### 数据集策展人 [更多信息请参见](https://github.com/huggingface/datasets/blob/master/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards) ### 许可信息 本数据集采用 [MIT许可证(MIT License)](https://github.com/INK-USC/CommonGen/blob/master/LICENSE) 进行授权。 ### 引用信息 bib @inproceedings{lin-etal-2020-commongen, title = "{C}ommon{G}en: A Constrained Text Generation Challenge for Generative Commonsense Reasoning", author = "Lin, Bill Yuchen and Zhou, Wangchunshu and Shen, Ming and Zhou, Pei and Bhagavatula, Chandra and Choi, Yejin and Ren, Xiang", booktitle = "Findings of the Association for Computational Linguistics: EMNLP 2020", month = nov, year = "2020", address = "Online", publisher = "Association for Computational Linguistics", url = "https://www.aclweb.org/anthology/2020.findings-emnlp.165", doi = "10.18653/v1/2020.findings-emnlp.165", pages = "1823--1840" } ### 贡献者 感谢 [@JetRunner](https://github.com/JetRunner)、[@yuchenlin](https://github.com/yuchenlin)、[@thomwolf](https://github.com/thomwolf)、[@lhoestq](https://github.com/lhoestq) 为本数据集的添加工作。
数据集概述
数据集名称
- 名称: CommonGen
- 别名: commongen
数据集属性
- 语言: 英语 (en)
- 许可证: MIT
- 多语言性: 单语
- 大小: 10K<n<100K
- 源数据集: 原始
- 任务类别: 文本到文本生成 (text2text-generation)
- 标签: 概念到文本 (concepts-to-text)
数据集结构
- 特征:
concept_set_idx: int32类型concepts: 字符串序列target: 字符串类型
- 分割:
- 训练集: 67389个样本,6724166字节
- 验证集: 4018个样本,408740字节
- 测试集: 1497个样本,77518字节
- 下载大小: 3434865字节
- 数据集大小: 7210424字节
数据集创建
- 语言创建者: 发现和众包
- 注释创建者: 众包
- 数据集信息:
- 构建方式: 通过结合AMT众包和现有标题语料库构建,包含30k概念集和50k句子。
使用考虑
- 许可证信息: 数据集根据MIT许可证授权。
- 引用信息: bib @inproceedings{lin-etal-2020-commongen, title = "{C}ommon{G}en: A Constrained Text Generation Challenge for Generative Commonsense Reasoning", author = "Lin, Bill Yuchen and Zhou, Wangchunshu and Shen, Ming and Zhou, Pei and Bhagavatula, Chandra and Choi, Yejin and Ren, Xiang", booktitle = "Findings of the Association for Computational Linguistics: EMNLP 2020", month = nov, year = "2020", address = "Online", publisher = "Association for Computational Linguistics", url = "https://www.aclweb.org/anthology/2020.findings-emnlp.165", doi = "10.18653/v1/2020.findings-emnlp.165", pages = "1823--1840" }