Cleaned-Kazakh-Wikipedia
收藏资源简介:
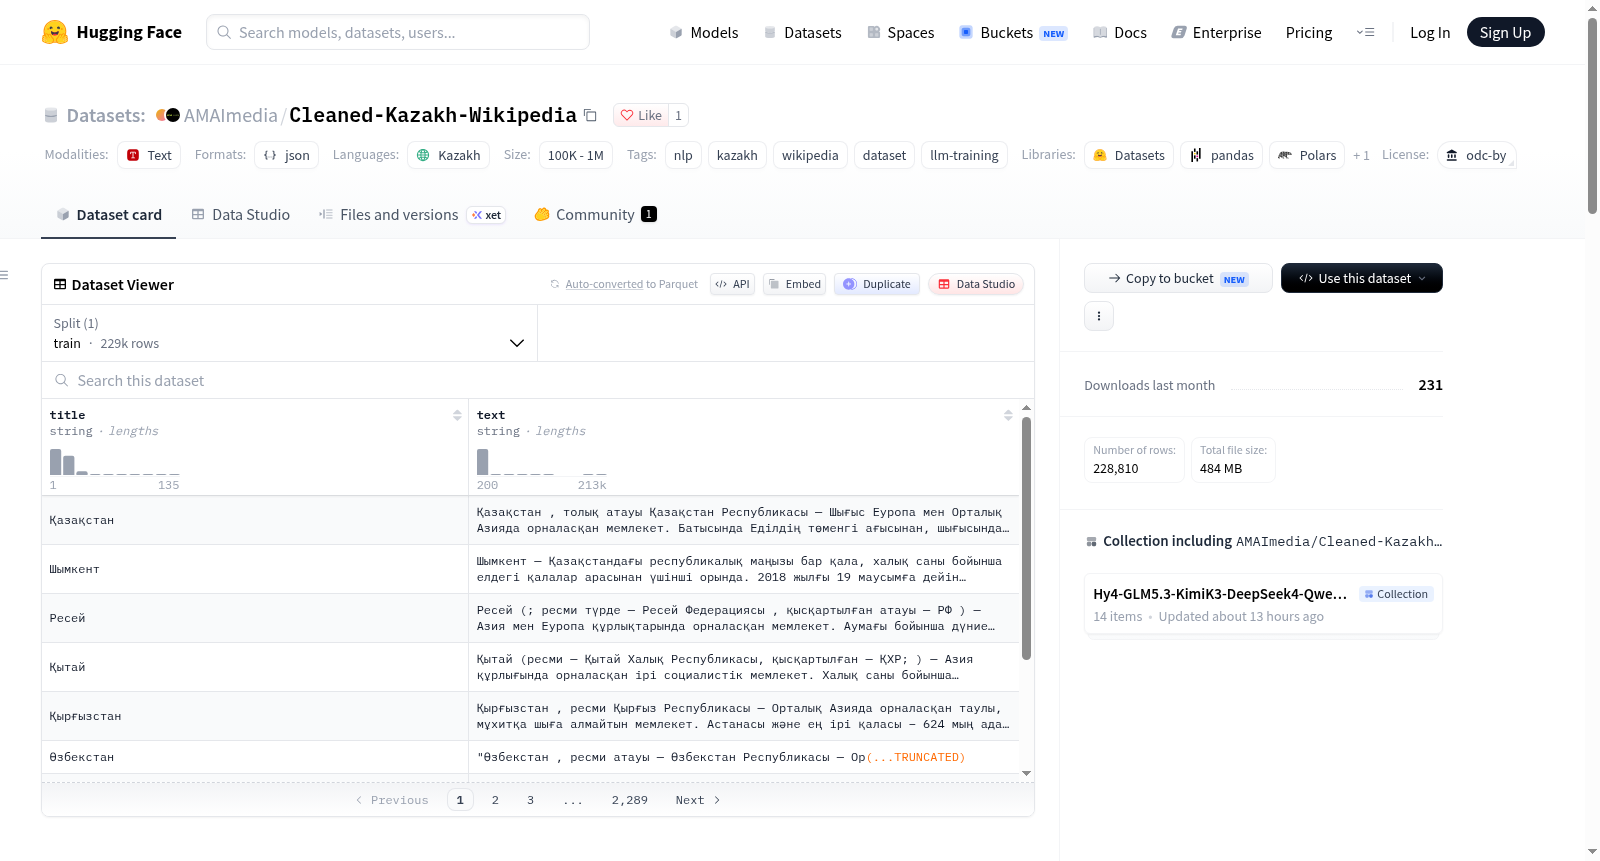
Kazakh-Wiki-Clean-228K 是一个经过清洗和结构化的哈萨克语维基百科数据集,包含 228,810 篇主命名空间文章,旨在用于大语言模型(LLM)的预训练与微调以及自然语言处理(NLP)任务。该数据集由 AMAImedia.com 的 NOESIS 专业多语言配音自动化平台(框架:DHCF-FNO)发布,创始人为 Ilia Bolotnikov。数据来源于 Wikimedia Foundation 的哈萨克语维基百科(kkwiki),采用西里尔字母书写。所有文章均经过预处理流程:仅保留主命名空间(NS 0)文章,去除重定向、讨论页和管理类别;丢弃最终长度低于 200 字符的低质量文章;递归剥离嵌套的 MediaWiki 模板、信息框和表格,移除 HTML 标签和技术元数据,将内部维基链接转换为纯文本;移除技术命令(如 __NOTOC__、__NOEDITSECTION__),清理空括号等结构残留,并规范化空白和标点。数据集以 JSON Lines 格式存储,每行包含一个 JSON 对象,字段为“title”(文章标题)和“text”(提取并清洗后的文本内容)。该数据集适用于语言模型预训练与微调、哈萨克语语义表示开发、检索增强生成(RAG)系统的知识库,以及哈萨克语的统计与结构语言学研究。数据集采用 ODC-By 许可证分发,使用时需注明原作者。
Kazakh-Wiki-Clean-228K is a cleaned and structured Kazakh Wikipedia dataset containing 228,810 main namespace articles, intended for pre-training and fine-tuning of large language models (LLMs) and natural language processing (NLP) tasks. The dataset is released by the NOESIS Professional Multilingual Dubbing Automation Platform (Framework: DHCF-FNO) of AMAImedia.com, founded by Ilia Bolotnikov. The data originates from the Kazakh Wikipedia (kkwiki) of the Wikimedia Foundation, written in Cyrillic script. All articles undergo a preprocessing pipeline: only main namespace (NS 0) articles are retained, redirects, discussion pages, and administrative categories are removed; low-quality articles with a final length below 200 characters are discarded; nested MediaWiki templates, infoboxes, and tables are recursively stripped, HTML tags and technical metadata are removed, internal wiki links are converted to plain text; technical commands (e.g., __NOTOC__, __NOEDITSECTION__) are removed, structural remnants such as empty parentheses are cleaned, and whitespace and punctuation are normalized. The dataset is stored in JSON Lines format, with each line containing a JSON object with fields title (article title) and text (extracted and cleaned text content). This dataset is suitable for language model pre-training and fine-tuning, developing Kazakh semantic representations, serving as a knowledge base for retrieval-augmented generation (RAG) systems, and statistical and structural linguistic research on Kazakh. The dataset is distributed under the ODC-By license, requiring attribution to the original authors.
数据集概述:Kazakh-Wiki-Clean-228K
Kazakh-Wiki-Clean-228K 是一个经过清洗和结构化的哈萨克语维基百科文章集合,包含 228,810篇 主命名空间文章,专为大型语言模型(LLM)预训练、微调及自然语言处理(NLP)任务设计。
核心信息
| 属性 | 详情 |
|---|---|
| 文章总数 | 228,810 |
| 数据来源 | 维基媒体基金会(kkwiki) |
| 语言 | 哈萨克语(西里尔字母) |
| 格式 | JSON Lines(.jsonl) |
| 文章范围 | 仅包含主命名空间(Namespace 0)文章 |
| 许可协议 | Odc-by 许可证 |
| 发布背景 | 作为 NOESIS 专业多语言配音自动化平台的一部分发布 |
数据清洗流程
- 过滤:仅保留主命名空间文章,排除重定向、讨论页和管理分类,并丢弃长度低于200字符的文章。
- 标记移除:递归删除嵌套的 MediaWiki 模板、信息框和表格,去除 HTML 标签和技术元数据,并将内部链接转换为纯文本。
- 规范化:移除技术命令(如
__NOTOC__),清理结构残留物(如空括号、残余括号),并规范化空白和标点。
数据结构
数据以 JSONL 格式存储,每行代表一篇文章,包含两个字段:
title:文章标题text:提取并清洗后的文本内容
预期应用场景
- 语言建模:用于 Transformer 架构模型的预训练和微调
- 词向量嵌入:开发哈萨克语语义表示
- RAG 系统:作为检索增强生成管道的知识库
- 语言学研究:支持哈萨克语的统计和结构分析
许可与署名
该数据集采用 Odc-by 许可证 发布,用户在使用或重新分发时必须注明原作者(创建者:kurumikz)。