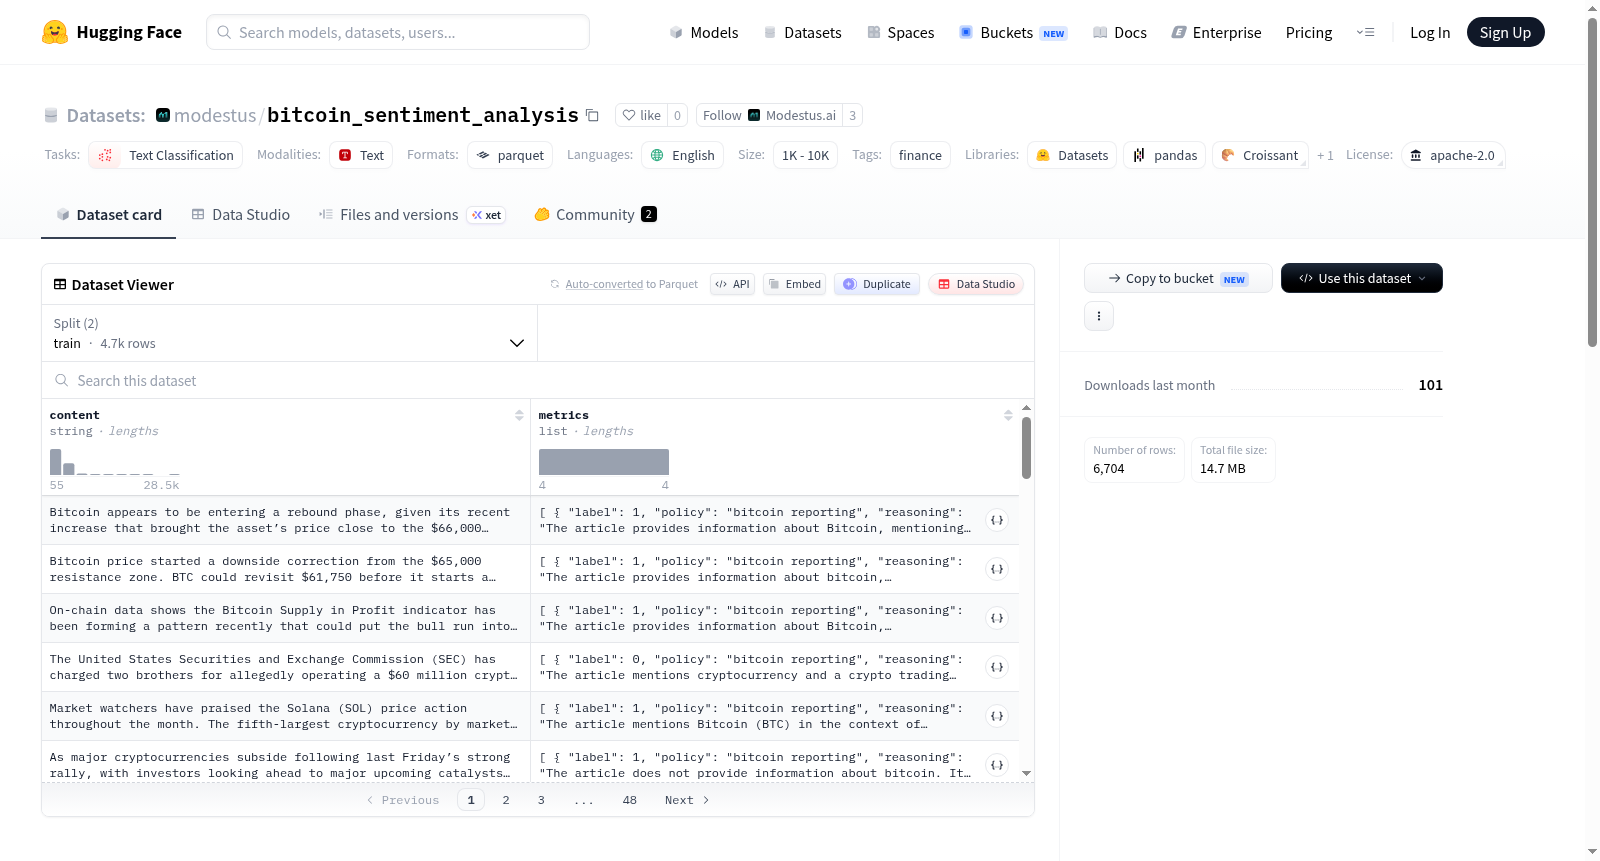
modestus/bitcoin_sentiment_analysis
收藏资源简介:
--- license: apache-2.0 dataset_info: features: - name: content dtype: string - name: metrics list: - name: label dtype: int64 - name: policy dtype: string - name: reasoning dtype: string splits: - name: train num_bytes: 21673740 num_examples: 4704 - name: test num_bytes: 9298292 num_examples: 2000 download_size: 14722722 dataset_size: 30972032 configs: - config_name: default data_files: - split: train path: data/train-* - split: test path: data/test-* task_categories: - text-classification language: - en tags: - finance size_categories: - 10K<n<100K --- We introduce a specialized sentiment analysis dataset for decentralized finance, **DeFine**. The dataset contains *6.700* cryptocurrency-related news articles sourced from CoinMarketCap and TradingView, with sentiment labels generated by state-of-the-art Large Language Models. During its construction, we investigate the impact of chain-of-thought (CoT) prompting on LLM performance when processing complex financial texts. Our results reveal that CoT reasoning significantly outperforms simple and free-form prompting, particularly for smaller models, and offer key insights into how model size and architecture influence performance. <p align="center"> <img src="https://i.imgur.com/COwXKlE.jpeg" alt="consensus-rate-small" width="200" style="display: inline-block;"/> <img src="https://i.imgur.com/suNSLaO.jpeg" alt="consensus-rate-medium" width="200" style="display: inline-block;"/> <img src="https://i.imgur.com/NbDQ5tP.jpeg" alt="consensus-rate-large" width="200" style="display: inline-block;"/> </p> The training notebook can be found at [notebook](https://colab.research.google.com/drive/1HlA1Oiv660CTwxtK7hK3WZWTsNoDMgEG?usp=sharing) The evaluation results of LLMs on this dataset, along with our trained version: | Model | Consensus Rate | |----------------------------------------------|---------------| | Llama-3.1-8B-Instruct-Turbo | 0.9306 | | Gemma-2-27b-it | 0.9497 | | Llama-3.1-70B-Instruct-Turbo | 0.9593 | | Mixtral-8x22B-Instruct-v0.1 | 0.9480 | | Qwen2-72B-Instruct | 0.9517 | | Nous-Hermes-2-Mixtral-8x7B-DPO | 0.9201 | | Qwen2.5-3B-Instruct (Original) | 0.8947 | | Qwen2.5-3B-Instruct (Ours) | 0.9239 | | Qwen2.5-7B-Instruct (Original) | 0.8808 | | Qwen2.5-7B-Instruct (Ours) | 0.9421 | We hope that dataset and evaluation framework serve as valuable tools for advancing sentiment analysis research in DeFi!
许可证: apache-2.0 数据集信息: 特征: - 字段名: content 数据类型: 字符串 - 字段名: metrics 子字段列表: - 字段名: label 数据类型: 64位整数 - 字段名: policy 数据类型: 字符串 - 字段名: reasoning 数据类型: 字符串 数据集拆分: - 名称: train 字节大小: 21673740 样本数量: 4704 - 名称: test 字节大小: 9298292 样本数量: 2000 下载体积: 14722722 数据集总体积: 30972032 配置项: - 配置名称: default 数据文件: - 拆分方式: train 路径: data/train-* - 拆分方式: test 路径: data/test-* 任务类别: - 文本分类 语言: - 英语 标签: - 金融 样本规模区间: - 10K < n < 100K 我们推出了一款面向去中心化金融(DeFi, decentralized finance)的专属情感分析数据集**DeFine**。 该数据集包含来自CoinMarketCap与TradingView的6700篇加密货币相关新闻文章,其情感标签由当前顶尖的大语言模型(Large Language Model, LLM)生成。 在数据集构建过程中,我们探究了思维链(chain-of-thought, CoT)提示词在处理复杂金融文本时对大语言模型性能的影响。研究结果表明,思维链推理的表现显著优于简单提示与自由格式提示,在小型模型上这一优势尤为明显;同时我们还揭示了模型规模与架构对性能的影响机制。 <p align="center"> <img src="https://i.imgur.com/COwXKlE.jpeg" alt="小型模型共识率" width="200" style="display: inline-block;"/> <img src="https://i.imgur.com/suNSLaO.jpeg" alt="中型模型共识率" width="200" style="display: inline-block;"/> <img src="https://i.imgur.com/NbDQ5tP.jpeg" alt="大型模型共识率" width="200" style="display: inline-block;"/> </p> 训练代码 notebook 可通过以下链接获取:[notebook](https://colab.research.google.com/drive/1HlA1Oiv660CTwxtK7hK3WZWTsNoDMgEG?usp=sharing) 大语言模型在该数据集上的评估结果,以及我们微调后的模型表现如下表所示: | 模型 | 共识率 | |----------------------------------------------|---------------| | Llama-3.1-8B-Instruct-Turbo | 0.9306 | | Gemma-2-27b-it | 0.9497 | | Llama-3.1-70B-Instruct-Turbo | 0.9593 | | Mixtral-8x22B-Instruct-v0.1 | 0.9480 | | Qwen2-72B-Instruct | 0.9517 | | Nous-Hermes-2-Mixtral-8x7B-DPO | 0.9201 | | Qwen2.5-3B-Instruct (Original) | 0.8947 | | Qwen2.5-3B-Instruct (Ours) | 0.9239 | | Qwen2.5-7B-Instruct (Original) | 0.8808 | | Qwen2.5-7B-Instruct (Ours) | 0.9421 | 我们期望本数据集与评估框架能够为去中心化金融领域的情感分析研究提供有价值的研究工具!