NUSAAKSARA
收藏资源简介:
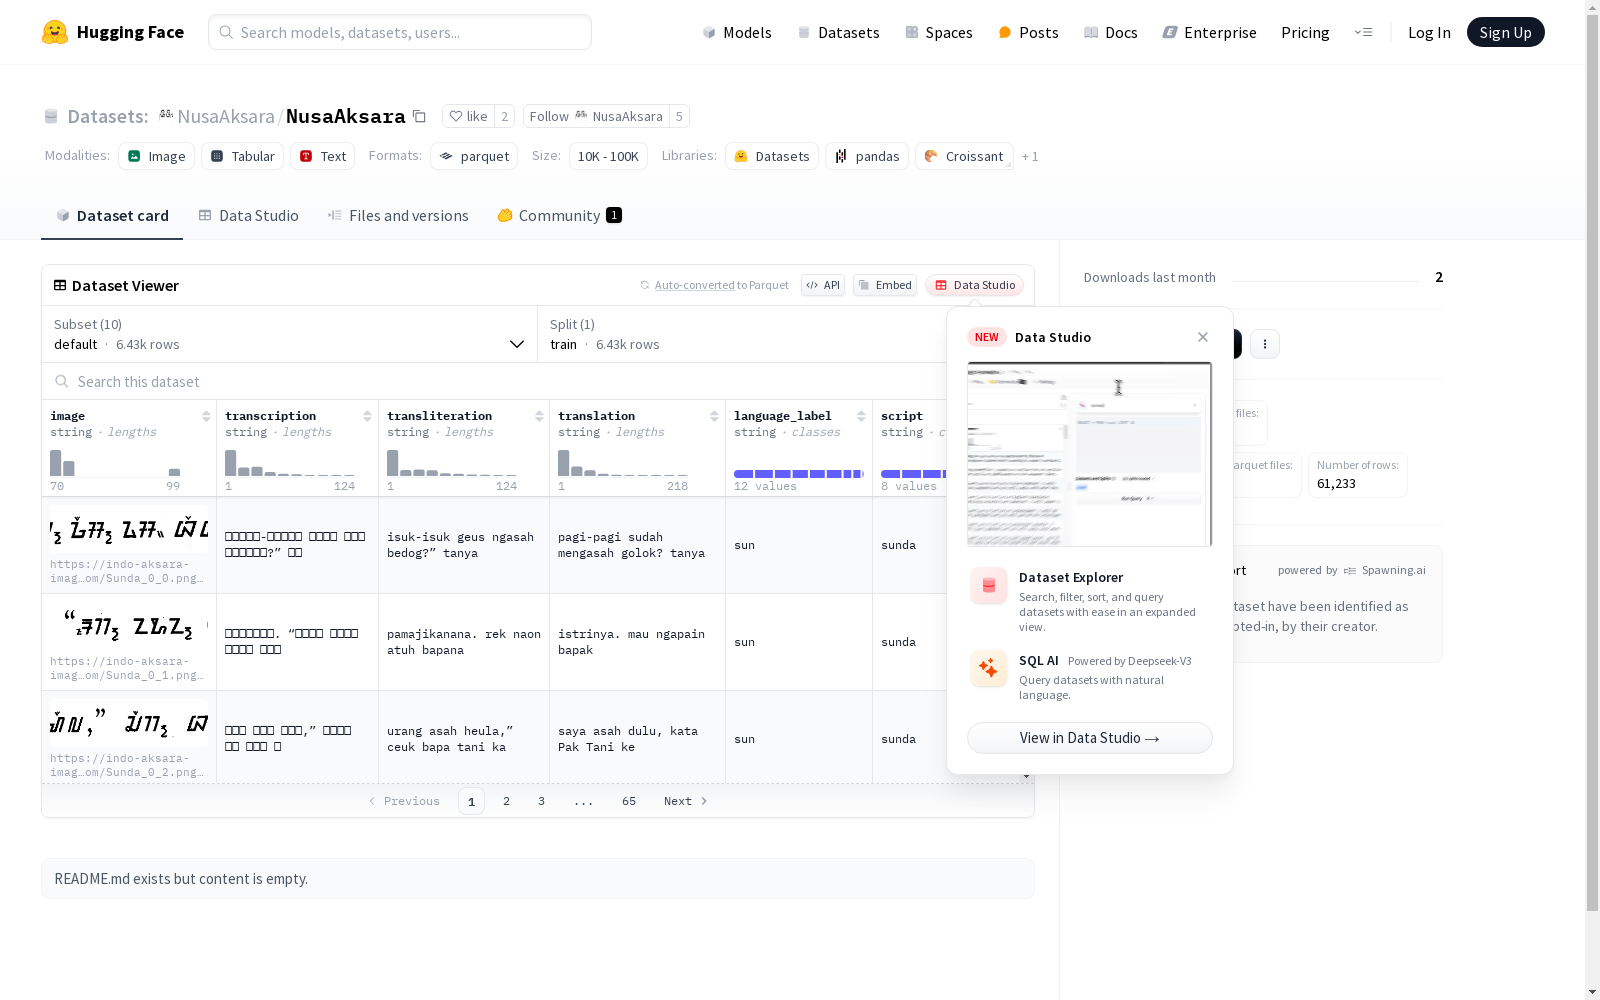
NUSAAKSARA是一个包含文本和图像模态的多模态多语言基准数据集,旨在保存和振兴印度尼西亚的传统脚本。该数据集涵盖了7种语言中的8种脚本,包括一些在NLP基准中不常见的低资源语言。数据集通过专家的严谨步骤构建,包括对文本进行转录、转写和翻译。该数据集可用于多种任务,如图像分割、光学字符识别、转写、翻译和语言识别等。
NUSAAKSARA is a multimodal and multilingual benchmark dataset covering both text and image modalities, which aims to preserve and revitalize Indonesia's traditional scripts. This dataset includes 8 scripts across 7 languages, with several low-resource languages that are rarely encountered in mainstream NLP benchmarks. It is constructed through rigorous expert-led workflows, encompassing text transcription, transliteration, and translation. The dataset supports a wide range of downstream tasks, such as image segmentation, optical character recognition (OCR), transcription, translation, and language identification.