what-breaks
收藏资源简介:
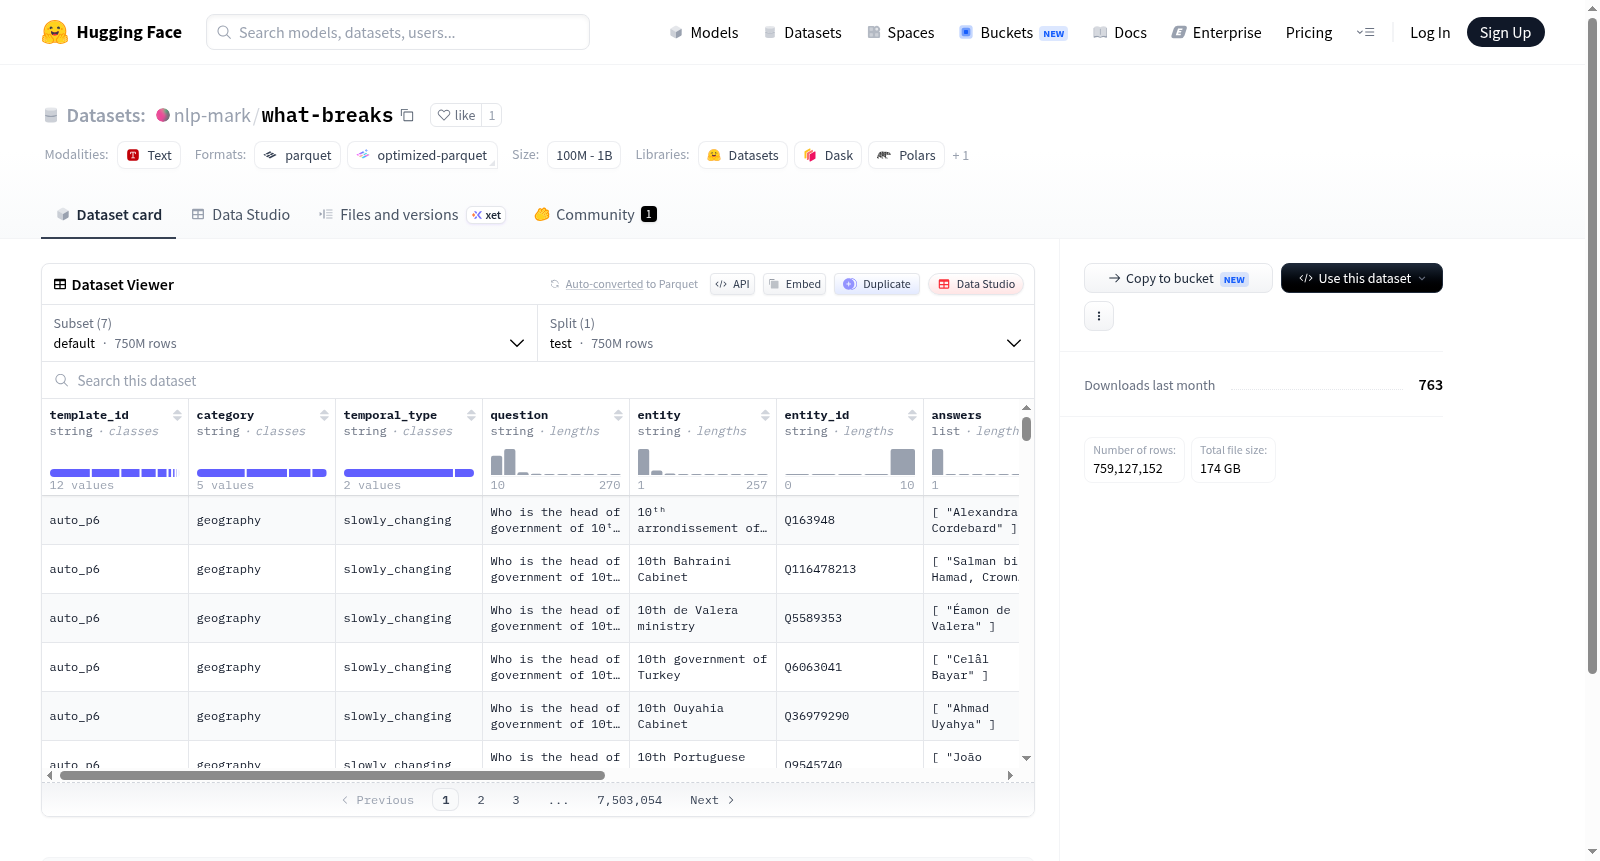
该数据集是一个大规模结构化问答数据集,提供多种规模配置,包括100K、250K、500K、1M、2M、5M及默认配置,所有配置均包含测试集,样本量从约9.3万到7.5亿不等。每个样本包含11个字段:模板ID(template_id)、问题类别(category)、时间类型(temporal_type)、自然语言问题(question)、实体名称(entity)、实体ID(entity_id)、答案列表(answers)、答案实体ID列表(answer_entity_ids)、类别解释(category_explanation)、时间解释(temporal_explanation)以及截断标志(truncated)。数据集设计适用于知识问答、实体链接、时间推理等自然语言处理任务,其结构化特征支持对问题类型、时间信息和实体关系的深入分析。
This dataset is a large-scale structured question-answering dataset, offering multiple size configurations including 100K, 250K, 500K, 1M, 2M, 5M, and a default configuration. All configurations include test sets, with sample sizes ranging from approximately 93,000 to 750 million. Each sample contains 11 fields: template ID (template_id), question category (category), temporal type (temporal_type), natural language question (question), entity name (entity), entity ID (entity_id), answer list (answers), answer entity ID list (answer_entity_ids), category explanation (category_explanation), temporal explanation (temporal_explanation), and truncation flag (truncated). The dataset is designed for natural language processing tasks such as knowledge question answering, entity linking, and temporal reasoning, with its structured features supporting in-depth analysis of question types, temporal information, and entity relationships.
数据集名称
What Breaks
数据集地址
https://huggingface.co/datasets/nlp-mark/what-breaks
数据集概览
该数据集包含多个配置(config),每个配置对应不同规模的子集,所有配置的数据集特征结构一致。数据集仅包含 test 拆分的样本,没有 train 或 validation 拆分。
特征字段
每个样本包含以下字段:
- template_id(字符串):模板ID。
- category(字符串):类别。
- temporal_type(字符串):时间类型。
- question(字符串):问题内容。
- entity(字符串):实体名称。
- entity_id(字符串):实体ID。
- answers(字符串列表):答案列表。
- answer_entity_ids(字符串列表):答案对应的实体ID列表。
- category_explanation(字符串):类别解释。
- temporal_explanation(字符串):时间解释。
- truncated(布尔值):是否被截断。
配置与规模
| 配置名称 | 数据集大小(字节) | 下载大小(字节) | 样本数 |
|---|---|---|---|
| 100K | 124,728,886 | 93,446,584 | 93,348 |
| 250K | 261,999,341 | 176,108,410 | 251,686 |
| 500K | 432,210,144 | 274,191,320 | 461,365 |
| 1M | 1,038,433,361 | 602,440,758 | 1,266,596 |
| 2M | 1,697,426,517 | 931,888,950 | 2,218,676 |
| 5M | 3,197,211,915 | 1,627,610,922 | 4,530,110 |
| default | 481,603,053,422 | 170,559,310,170 | 750,305,371 |
数据文件
每个配置对应的数据文件路径如下:
- 100K:
100K/train-* - 1M:
1M/train-* - 250K:
250K/train-* - 2M:
2M/train-* - 500K:
500K/train-* - 5M:
5M/train-* - default:
data/train-*