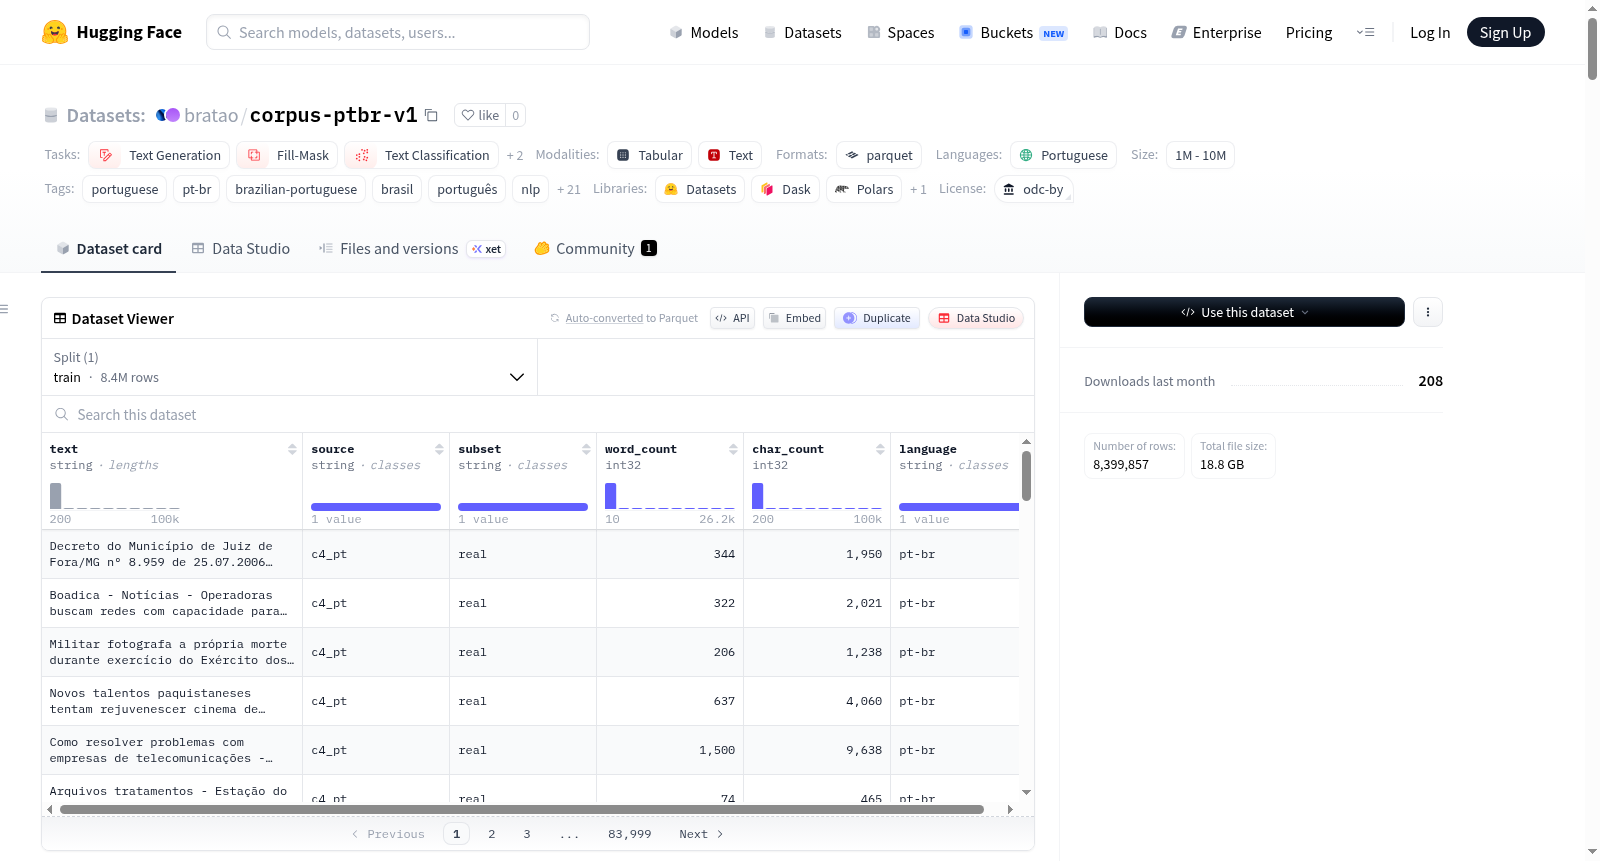
bratao/corpus-ptbr-v1
收藏资源简介:
Corpus PT-BR v1是一个巴西葡萄牙语语料库,包含840万文档和63亿标记,用于大型语言模型(LLM)的预训练和微调。该数据集结合了经过SBERT质量过滤的真实数据和由多种高质量LLMs生成的合成数据,以增强风格、词汇和论述多样性。真实数据来源于公共数据集如Common Crawl(C4)和FineWeb2的葡萄牙语子集,而合成数据则通过多种LLM生成,包括Qwen、DeepSeek、Llama等模型,并覆盖了多种文本风格和提示。数据集还提供了详细的统计信息、使用方法(如加载和过滤数据)、数据处理流程(如质量过滤和去重)以及许可证信息。
Corpus PT-BR v1 is a Brazilian Portuguese corpus with 8.4 million documents and 6.3 billion tokens for pre-training and fine-tuning LLMs. It combines curated real data with a synthetic layer generated by multiple high-quality LLMs to enhance stylistic, lexical, and discursive diversity. The real data comes from public sources like Common Crawl (C4) and FineWeb2s Portuguese subsets, while the synthetic data is generated by various LLMs (e.g., Qwen, DeepSeek, Llama) using diverse text styles and prompts. The dataset includes detailed statistics, usage examples (e.g., loading and filtering data), processing pipelines (e.g., quality filtering and deduplication), and licensing information.