oliverkinch/doab-da-bt
收藏资源简介:
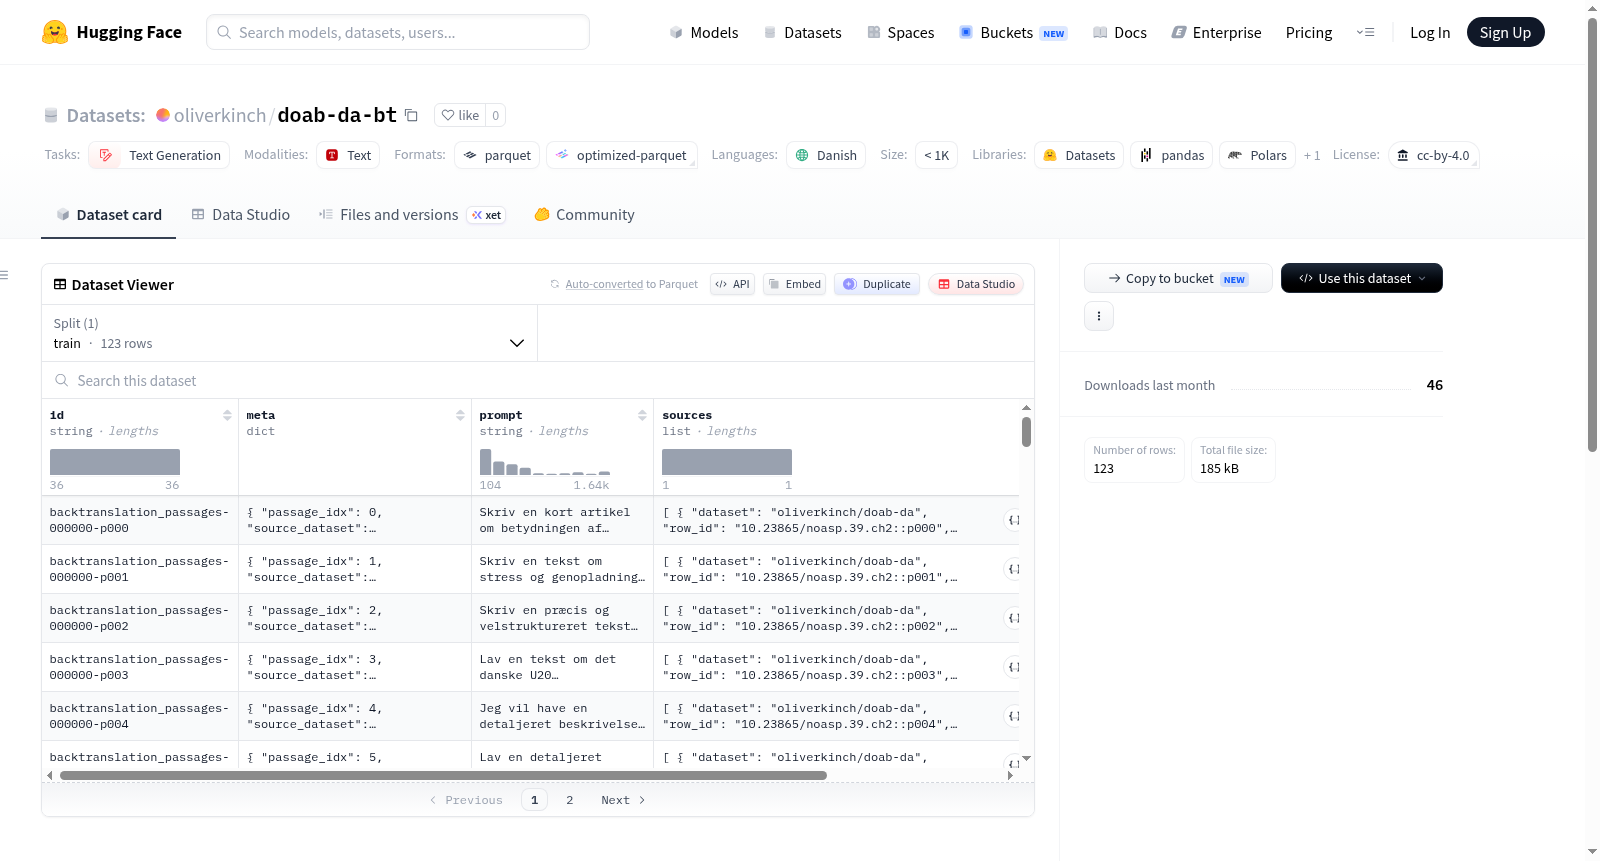
该数据集是一个丹麦语的文本生成数据集,许可证为cc-by-4.0。数据集包含123个训练示例,大小为280346字节。数据集的结构包括id、meta、prompt、sources和target等字段。meta字段包含多个子字段,如passage_idx、source_dataset、source_id等。数据集的生成方法是指令回译,即使用源语料库的段落作为目标,由LLM生成每个段落的提示。提示通过使用nvidia/Nemotron-Personas-USA中的人物进行多样化处理。数据集的来源是oliverkinch/doab-da,包含113行,列包括id、meta、prompt、sources和target。
This dataset is a Danish text generation dataset licensed under cc-by-4.0. It contains 123 training examples with a size of 280346 bytes. The dataset structure includes fields such as id, meta, prompt, sources, and target. The meta field contains multiple subfields like passage_idx, source_dataset, source_id, etc. The generation method of the dataset is instruction backtranslation, where passages from the source corpus are used as targets, and an LLM generates the prompt that would have produced each passage. Prompts are diversified using personas from nvidia/Nemotron-Personas-USA. The dataset source is oliverkinch/doab-da, containing 113 rows with columns including id, meta, prompt, sources, and target.