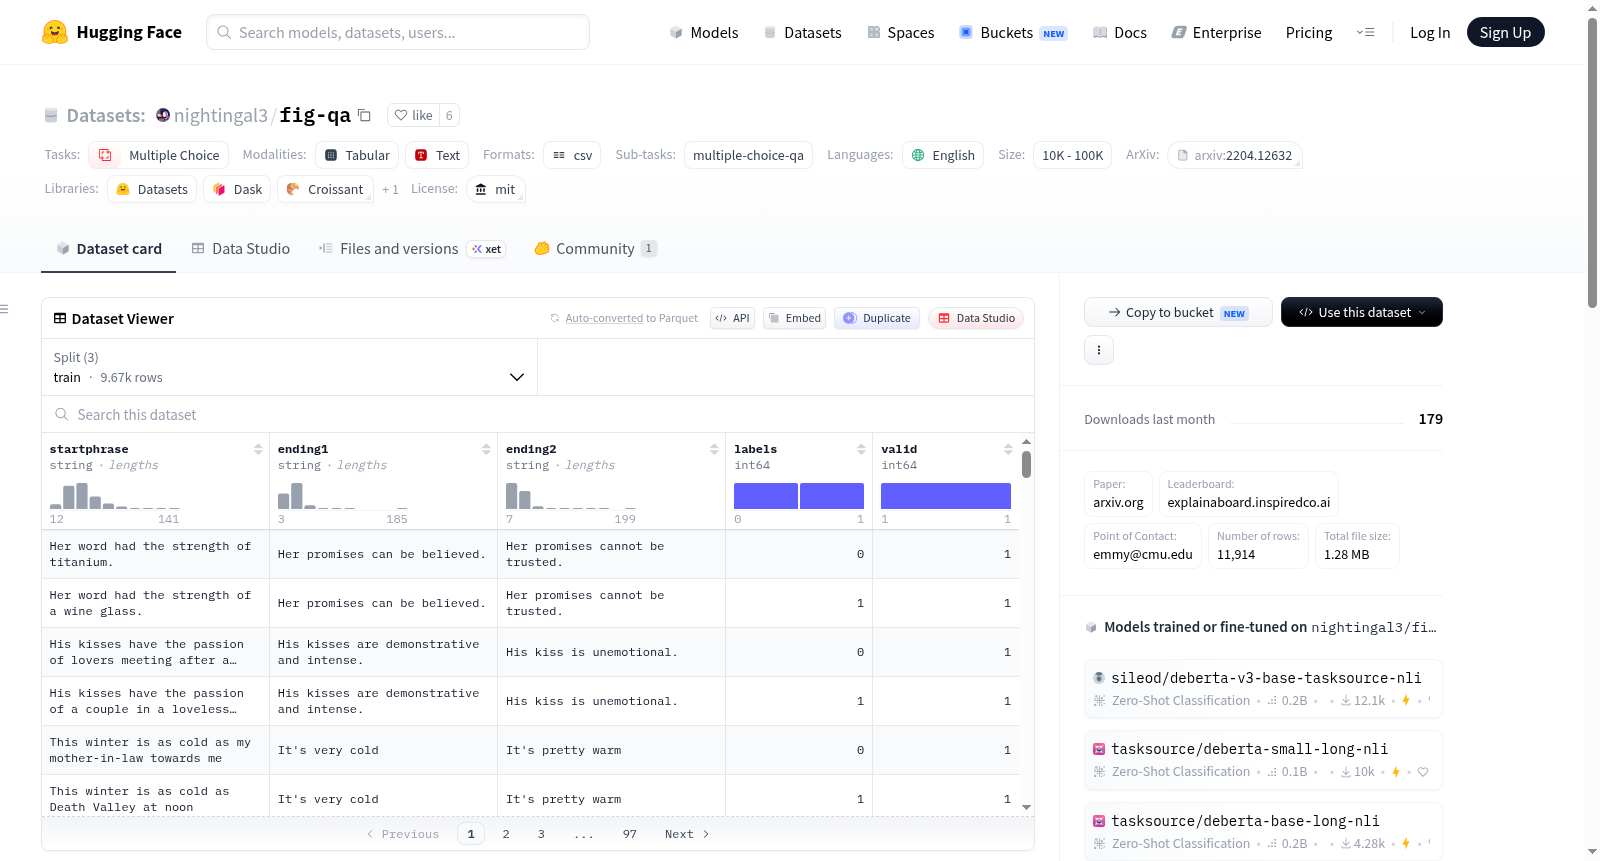
nightingal3/fig-qa
收藏资源简介:
--- annotations_creators: - expert-generated - crowdsourced language_creators: - crowdsourced language: - en license: - mit multilinguality: - monolingual pretty_name: Fig-QA size_categories: - 10K<n<100K source_datasets: - original task_categories: - multiple-choice task_ids: - multiple-choice-qa --- # Dataset Card for Fig-QA ## Table of Contents - [Table of Contents](#table-of-contents) - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Supported Tasks and Leaderboards](#supported-tasks-and-leaderboards) - [Languages](#languages) - [Dataset Structure](#dataset-structure) - [Data Splits](#data-splits) - [Considerations for Using the Data](#considerations-for-using-the-data) - [Discussion of Biases](#discussion-of-biases) - [Additional Information](#additional-information) - [Licensing Information](#licensing-information) - [Citation Information](#citation-information) ## Dataset Description - **Repository:** https://github.com/nightingal3/Fig-QA - **Paper:** https://arxiv.org/abs/2204.12632 - **Leaderboard:** https://explainaboard.inspiredco.ai/leaderboards?dataset=fig_qa - **Point of Contact:** emmy@cmu.edu ### Dataset Summary This is the dataset for the paper [Testing the Ability of Language Models to Interpret Figurative Language](https://arxiv.org/abs/2204.12632). Fig-QA consists of 10256 examples of human-written creative metaphors that are paired as a Winograd schema. It can be used to evaluate the commonsense reasoning of models. The metaphors themselves can also be used as training data for other tasks, such as metaphor detection or generation. ### Supported Tasks and Leaderboards You can evaluate your models on the test set by submitting to the [leaderboard](https://explainaboard.inspiredco.ai/leaderboards?dataset=fig_qa) on Explainaboard. Click on "New" and select `qa-multiple-choice` for the task field. Select `accuracy` for the metric. You should upload results in the form of a system output file in JSON or JSONL format. ### Languages This is the English version. Multilingual version can be found [here](https://huggingface.co/datasets/cmu-lti/multi-figqa). ### Data Splits Train-{S, M(no suffix), XL}: different training set sizes Dev Test (labels not provided for test set) ## Considerations for Using the Data ### Discussion of Biases These metaphors are human-generated and may contain insults or other explicit content. Authors of the paper manually removed offensive content, but users should keep in mind that some potentially offensive content may remain in the dataset. ## Additional Information ### Licensing Information MIT License ### Citation Information If you found the dataset useful, please cite this paper: @misc{https://doi.org/10.48550/arxiv.2204.12632, doi = {10.48550/ARXIV.2204.12632}, url = {https://arxiv.org/abs/2204.12632}, author = {Liu, Emmy and Cui, Chen and Zheng, Kenneth and Neubig, Graham}, keywords = {Computation and Language (cs.CL), Artificial Intelligence (cs.AI), FOS: Computer and information sciences, FOS: Computer and information sciences}, title = {Testing the Ability of Language Models to Interpret Figurative Language}, publisher = {arXiv}, year = {2022}, copyright = {Creative Commons Attribution Share Alike 4.0 International} }
annotations_creators: - 专家生成 - 众包 language_creators: - 众包 language: - 英语(en) license: - MIT许可证 multilinguality: - 单语言 pretty_name: Fig-QA size_categories: - 10K<n<100K source_datasets: - 原创数据集 task_categories: - 多项选择 task_ids: - 多项选择问答 # Fig-QA 数据集卡片 ## 目录 - [目录](#目录) - [数据集描述](#数据集描述) - [数据集概述](#数据集概述) - [支持任务与评测榜单](#支持任务与评测榜单) - [语言说明](#语言说明) - [数据集结构](#数据集结构) - [数据划分](#数据划分) - [数据集使用注意事项](#数据集使用注意事项) - [偏见讨论](#偏见讨论) - [附加信息](#附加信息) - [许可证信息](#许可证信息) - [引用信息](#引用信息) ## 数据集描述 - **代码仓库**:https://github.com/nightingal3/Fig-QA - **相关论文**:https://arxiv.org/abs/2204.12632 - **评测榜单**:https://explainaboard.inspiredco.ai/leaderboards?dataset=fig_qa - **联系人**:emmy@cmu.edu ### 数据集概述 本数据集对应论文《Testing the Ability of Language Models to Interpret Figurative Language》(测试大语言模型(Large Language Model)解读比喻性语言的能力)。Fig-QA 包含10256条由人类创作的创意隐喻样本,这些样本以威诺格拉德模式(Winograd schema)的形式成对出现。该数据集可用于评估模型的常识推理能力,其中的隐喻样本也可作为训练数据,用于隐喻检测或隐喻生成等其他任务。 ### 支持任务与评测榜单 你可通过向Explainaboard的[评测榜单](https://explainaboard.inspiredco.ai/leaderboards?dataset=fig_qa)提交结果,在测试集上评估你的模型。点击"New"并选择`qa-multiple-choice`作为任务字段,选择`accuracy`作为评估指标。你需以JSON或JSONL格式的系统输出文件形式上传评估结果。 ### 语言说明 本数据集为英文版本。多语言版本可参见[此处](https://huggingface.co/datasets/cmu-lti/multi-figqa)。 ### 数据划分 训练集-{S, M(无后缀), XL}:不同规模的训练子集 开发集(Dev) 测试集(Test,测试集不提供标签) ## 数据集使用注意事项 ### 偏见讨论 本数据集的隐喻均由人类创作,可能包含侮辱性或其他显性不当内容。论文作者已手动移除冒犯性内容,但用户仍需注意,数据集中仍可能残留潜在的冒犯性内容。 ## 附加信息 ### 许可证信息 MIT 许可证 ### 引用信息 若你认为本数据集对你的研究有所帮助,请引用如下论文: bibtex @misc{https://doi.org/10.48550/arxiv.2204.12632, doi = {10.48550/ARXIV.2204.12632}, url = {https://arxiv.org/abs/2204.12632}, author = {Liu, Emmy and Cui, Chen and Zheng, Kenneth and Neubig, Graham}, keywords = {Computation and Language (cs.CL), 人工智能 (cs.AI), FOS: 计算机与信息科学, FOS: Computer and information sciences}, title = {Testing the Ability of Language Models to Interpret Figurative Language}, publisher = {arXiv}, year = {2022}, copyright = {Creative Commons Attribution Share Alike 4.0 International} }
数据集概述
数据集名称
- 名称: Fig-QA
数据集基本信息
- 语言: 英语 (
en) - 许可证: MIT License
- 多语言性: 单语种
- 大小: 10K<n<100K
- 来源: 原始数据
- 任务类别: 多项选择
- 任务ID: 多项选择问答 (
multiple-choice-qa)
数据集描述
- 概述: Fig-QA包含10256个人类编写的创意隐喻示例,这些示例作为Winograd模式配对,用于评估模型的常识推理能力。这些隐喻也可用于其他任务,如隐喻检测或生成。
- 支持的任务和排行榜: 可通过提交模型到Explainaboard的排行榜来评估模型在测试集上的表现。
数据集结构
- 数据分割: 训练集(不同大小)、开发集、测试集(测试集标签未提供)
使用数据的考虑
- 偏见讨论: 数据集中的隐喻由人类生成,可能包含侮辱或其他明确内容。虽然论文作者手动移除了攻击性内容,但用户应注意可能仍存在潜在的攻击性内容。
附加信息
- 许可证信息: MIT License
- 引用信息: 如果发现数据集有用,请引用相关论文。