jiacheng-ye/logiqa-zh
收藏资源简介:
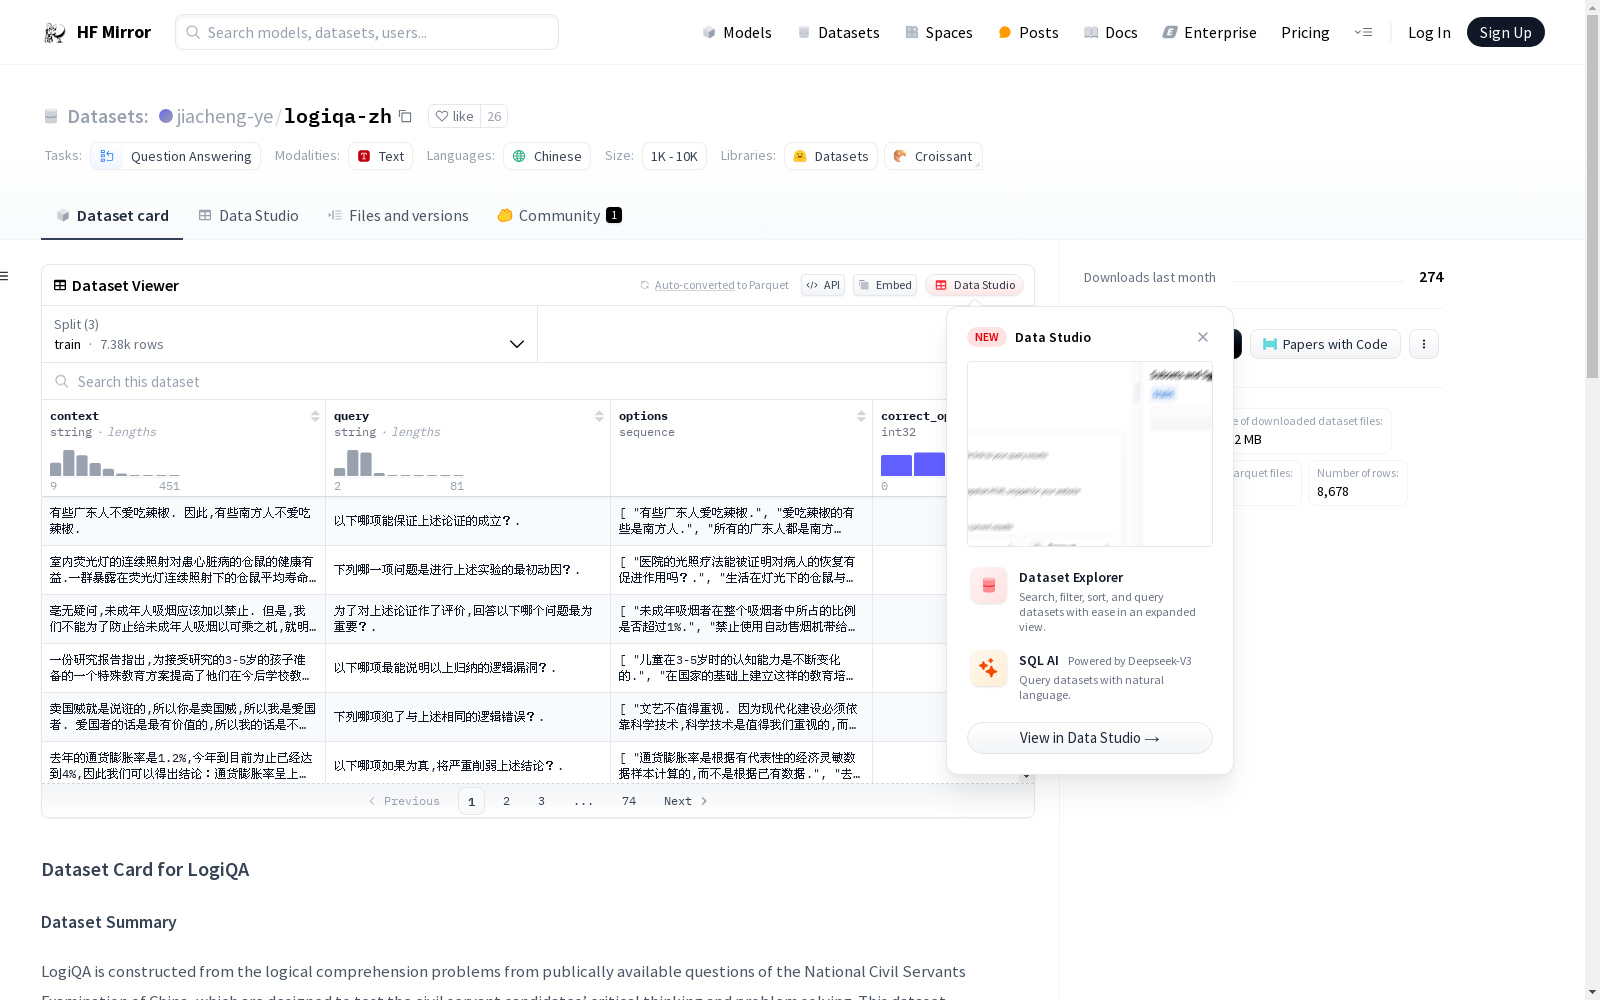
--- task_categories: - question-answering language: - zh pretty_name: LogiQA-zh size_categories: - 1K<n<10K paperswithcode_id: logiqa dataset_info: features: - name: context dtype: string - name: query dtype: string - name: options sequence: dtype: string - name: correct_option dtype: string splits: - name: train num_examples: 7376 - name: validation num_examples: 651 - name: test num_examples: 651 --- # Dataset Card for LogiQA ## Dataset Description - **Homepage:** - **Repository:** - **Paper:** - **Leaderboard:** - **Point of Contact:** ### Dataset Summary LogiQA is constructed from the logical comprehension problems from publically available questions of the National Civil Servants Examination of China, which are designed to test the civil servant candidates’ critical thinking and problem solving. This dataset includes the Chinese versions only. ## Dataset Structure ### Data Instances An example from `train` looks as follows: ``` {'context': '有些广东人不爱吃辣椒.因此,有些南方人不爱吃辣椒.', 'query': '以下哪项能保证上述论证的成立?', 'options': ['有些广东人爱吃辣椒', '爱吃辣椒的有些是南方人', '所有的广东人都是南方人', '有些广东人不爱吃辣椒也不爱吃甜食'], 'correct_option': 2} ``` ### Data Fields - `context`: a `string` feature. - `query`: a `string` feature. - `answers`: a `list` feature containing `string` features. - `correct_option`: a `string` feature. ### Data Splits |train|validation|test| |----:|---------:|---:| | 7376| 651| 651| ## Additional Information ### Dataset Curators The original LogiQA was produced by Jian Liu, Leyang Cui , Hanmeng Liu, Dandan Huang, Yile Wang, and Yue Zhang. ### Licensing Information [More Information Needed] ### Citation Information ``` @article{liu2020logiqa, title={Logiqa: A challenge dataset for machine reading comprehension with logical reasoning}, author={Liu, Jian and Cui, Leyang and Liu, Hanmeng and Huang, Dandan and Wang, Yile and Zhang, Yue}, journal={arXiv preprint arXiv:2007.08124}, year={2020} } ``` ### Contributions [@jiacheng-ye](https://github.com/jiacheng-ye) added this Chinese dataset. [@lucasmccabe](https://github.com/lucasmccabe) added the English dataset.
task_categories: - 问答(question-answering) language: - 中文(zh) pretty_name: LogiQA-zh size_categories: - 样本量介于1000至10000之间(1K<n<10K) paperswithcode_id: logiqa dataset_info: features: - name: 上下文(context) dtype: 字符串(string) - name: 查询(query) dtype: 字符串(string) - name: 选项(options) sequence: dtype: 字符串(string) - name: 正确选项(correct_option) dtype: 字符串(string) splits: - name: 训练集(train) num_examples: 7376 - name: 验证集(validation) num_examples: 651 - name: 测试集(test) num_examples: 651 --- # LogiQA 数据集卡片 ## 数据集说明 - **主页:** 无 - **代码仓库:** 无 - **相关论文:** 无 - **排行榜:** 无 - **联系人:** 无 ### 数据集概述 LogiQA 源自中国国家公务员考试公开的逻辑理解类试题,此类试题旨在考查公务员招录考生的批判性思维与问题解决能力。本数据集仅包含中文版本。 ## 数据集结构 ### 数据样例 训练集的一条样例如下: {'context': '有些广东人不爱吃辣椒。因此,有些南方人不爱吃辣椒。', 'query': '以下哪项能保证上述论证的成立?', 'options': ['有些广东人爱吃辣椒', '爱吃辣椒的有些是南方人', '所有的广东人都是南方人', '有些广东人不爱吃辣椒也不爱吃甜食'], 'correct_option': 2} ### 数据字段 - `context`: 字符串型特征。 - `query`: 字符串型特征。 - `answers`: 包含字符串元素的列表型特征。 - `correct_option`: 字符串型特征。 ### 数据划分 | 训练集(train) | 验证集(validation) | 测试集(test) | |----------------:|-------------------:|--------------:| | 7376 | 651 | 651 | ## 附加信息 ### 数据集主创人员 原版 LogiQA 数据集由 Jian Liu、Leyang Cui、Hanmeng Liu、Dandan Huang、Yile Wang、Yue Zhang 共同构建。 ### 许可信息 [需补充更多信息] ### 引用信息 @article{liu2020logiqa, title={LogiQA: A challenge dataset for machine reading comprehension with logical reasoning}, author={Liu, Jian and Cui, Leyang and Liu, Hanmeng and Huang, Dandan and Wang, Yile and Zhang, Yue}, journal={arXiv preprint arXiv:2007.08124}, year={2020} } ### 贡献信息 [@jiacheng-ye](https://github.com/jiacheng-ye) 贡献了本中文数据集。 [@lucasmccabe](https://github.com/lucasmccabe) 贡献了英文数据集。
数据集概述
- 名称: LogiQA-zh
- 任务类别: 问答(question-answering)
- 语言: 中文(zh)
- 大小: 1K<n<10K
- 论文代码ID: logiqa
数据集结构
数据实例
- 字段:
context: 字符串类型query: 字符串类型options: 字符串序列correct_option: 字符串类型
数据分割
| 分割 | 示例数量 |
|---|---|
| train | 7376 |
| validation | 651 |
| test | 651 |
数据集来源
- 来源: 中国国家公务员考试公开题目
- 目的: 测试公务员候选人的批判性思维和问题解决能力
贡献者
- 中文数据集添加者: @jiacheng-ye
- 英文数据集添加者: @lucasmccabe