REFUSE-BENCH
收藏资源简介:
REFUSE-BENCH是由巴尔的摩马里兰大学创建的一个用于二进制函数相似性检测的基准数据集。该数据集包含243,128个二进制文件,涵盖了多种编译配置和优化设置,旨在模拟真实世界的计算机安全场景。数据集的创建过程包括从GitHub上抓取源代码并进行编译,确保了数据的高质量和多样性。REFUSE-BENCH主要应用于逆向工程、恶意软件分析和漏洞检测等领域,旨在评估和提升现有二进制函数相似性检测模型的性能。
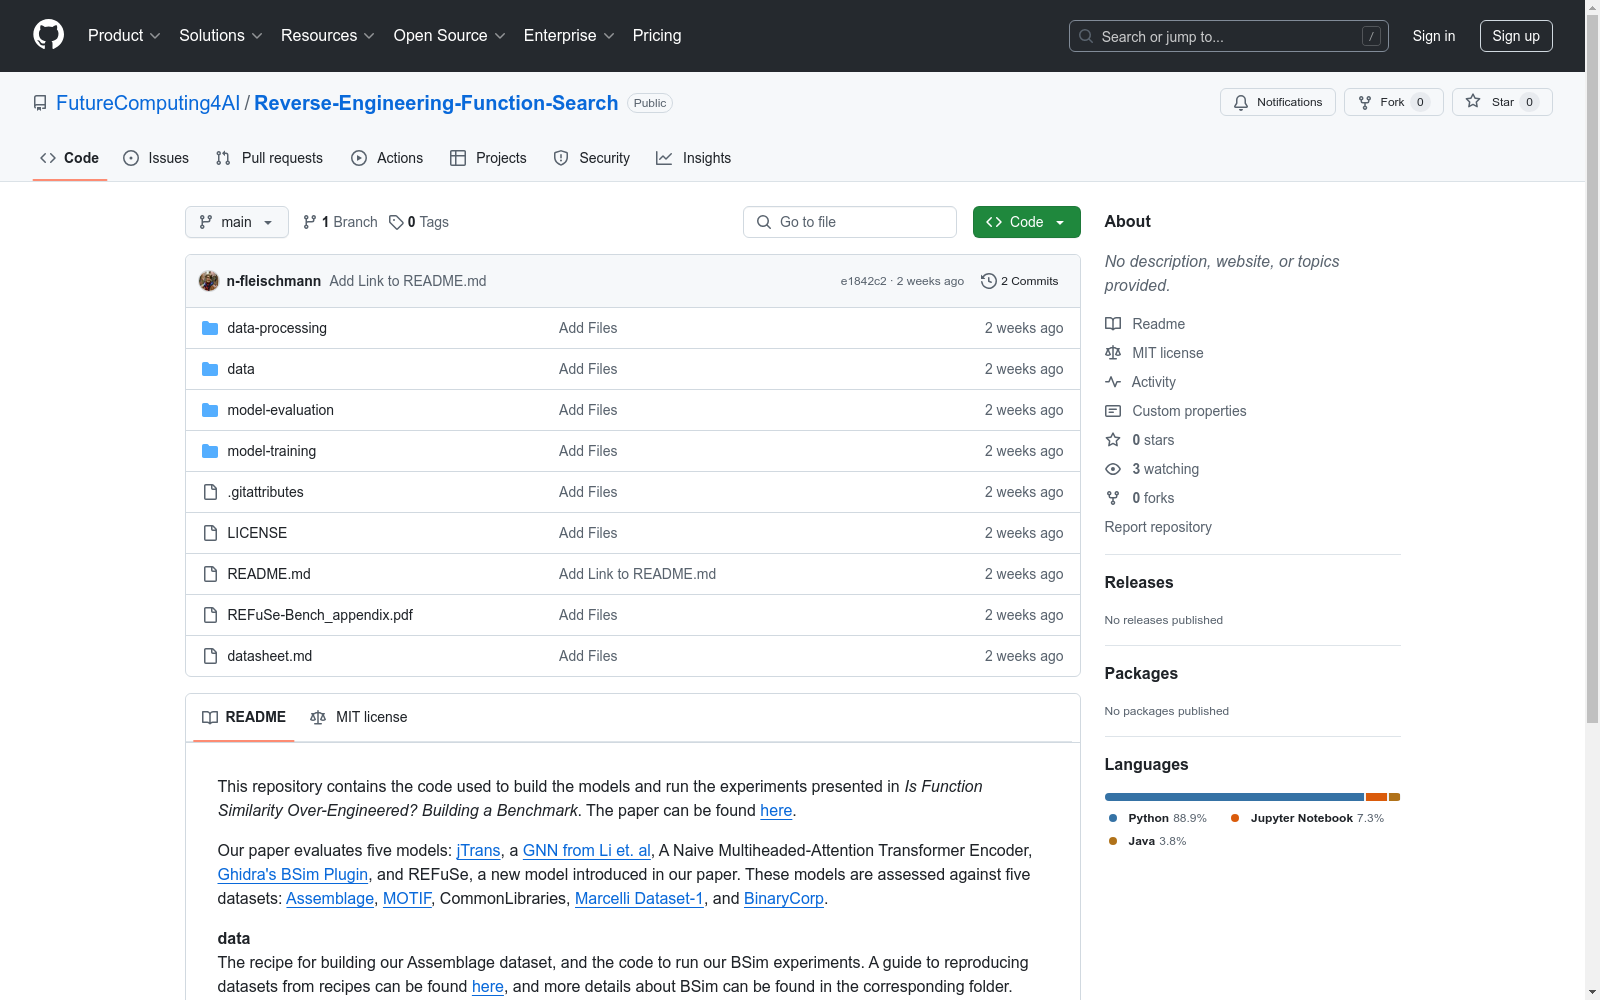
REFUSE-BENCH is a benchmark dataset for binary function similarity detection, developed by the University of Maryland, Baltimore. This dataset contains 243,128 binary files covering various compilation configurations and optimization settings, designed to simulate real-world computer security scenarios. The dataset was created by scraping source code from GitHub and compiling it, ensuring high data quality and diversity. REFUSE-BENCH is mainly applied in fields such as reverse engineering, malware analysis and vulnerability detection, aiming to evaluate and improve the performance of existing binary function similarity detection models.
数据集概述
数据集名称
- Assemblage
数据集描述
- Assemblage 是一个用于评估函数相似性模型的数据集。
相关模型
- 该数据集用于评估以下五个模型:
- jTrans
- GNN from Li et. al
- Naive Multiheaded-Attention Transformer Encoder
- Ghidras BSim Plugin
- REFuSe
数据集构建
- 提供了构建 Assemblage 数据集的配方和运行 BSim 实验的代码。
- 有关如何从配方中重现数据集的指南可以在 这里 找到。
数据处理
- 提供了预处理数据以进行实验的代码。
模型训练
- 提供了在 Assemblage 数据上训练模型的代码。
模型评估
- 提供了在数据集上评估模型的代码。