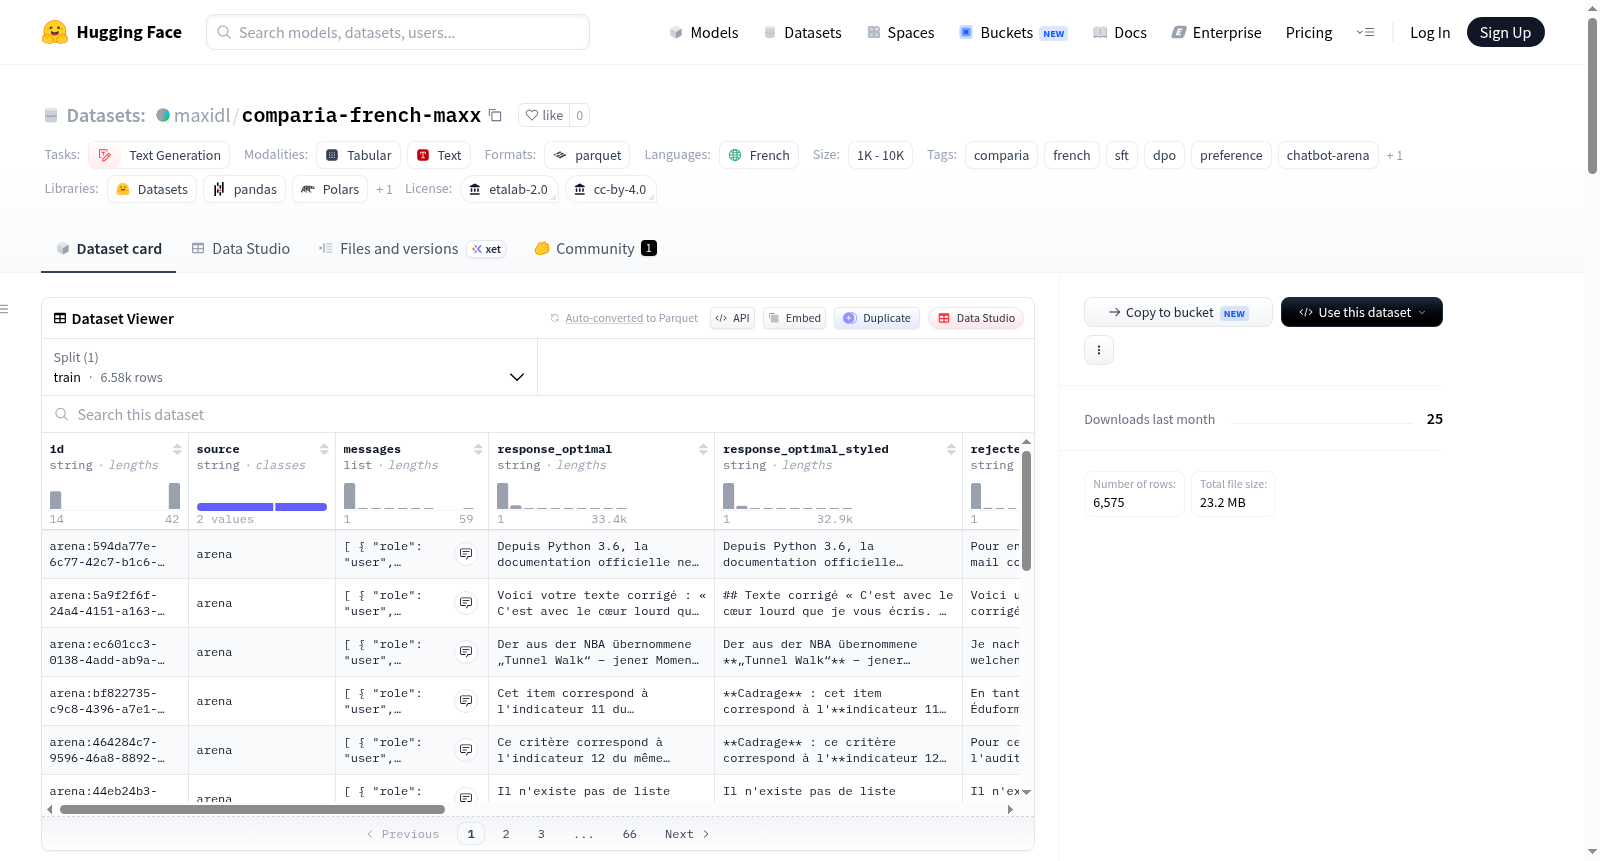
comparia-french-maxx
收藏资源简介:
Compar:IA-French-Maxx 是一个针对法语 Compar:IA 对话平台优化的高质量偏好数据集,旨在提升 Compar:IA 竞技场排行榜的性能。数据集包含 6,075 条助手回复,每条回复都是针对真实 Compar:IA 对话的“最佳可能”回答,并与被击败的较弱回复配对。数据分为三个子集:Arena - general(1,500 行,来自竞技场中较难的两个原始回复之一与最优回复的比较)、Arena - both_bad(2,400 行,来自用户评价为“两者都差”的两个回复)、Reactions(2,175 行,来自用户负面反应的确切助手消息)。共提供 6,059 个可用偏好对,其中 4,907 个强偏好、1,031 个中等偏好、121 个弱偏好、16 个无偏好。每条记录包含对话历史(messages)、最优回复(response_optimal 及其格式化版本 response_optimal_styled)、被击败的回复(rejected 和可选的 rejected_2)、偏好强度(pref_strength)、缺陷标签(incorrect, superficial, instructions_not_followed,仅反应子集有)、对话轮次信息(conversation_turns, is_multi_turn, prompt_chars)以及来源标识(source, id)。数据集适用于监督微调(SFT)和偏好优化(如 DPO、ORPO、KTO),并支持按偏好强度、缺陷类型或对话结构进行过滤。注意:回复由模型生成,偏好判断为近似值;弱/中等偏好对可能噪声较大;源数据许可为 Etalab 2.0 和 CC-BY-4.0,已过滤 PII,保留未审核内容。
Compar:IA-French-Maxx is a high-quality preference dataset optimized for the French Compar:IA dialogue platform, aimed at improving the performance of the Compar:IA Arena leaderboard. The dataset contains 6,075 assistant responses, each being the best possible answer to a real Compar:IA conversation, paired with a defeated weaker response. The data is divided into three subsets: Arena - general (1,500 rows, comparing one of two original difficult responses from the arena with the optimal response), Arena - both_bad (2,400 rows, from two responses rated as both bad by users), and Reactions (2,175 rows, from exact assistant messages that received negative user reactions). It provides a total of 6,059 usable preference pairs, including 4,907 strong preferences, 1,031 moderate preferences, 121 weak preferences, and 16 no preferences. Each record includes conversation history (messages), optimal response (response_optimal and its formatted version response_optimal_styled), defeated response (rejected and optional rejected_2), preference strength (pref_strength), defect labels (incorrect, superficial, instructions_not_followed, only in Reactions subset), conversation turn information (conversation_turns, is_multi_turn, prompt_chars), and source identifiers (source, id). The dataset is suitable for supervised fine-tuning (SFT) and preference optimization (e.g., DPO, ORPO, KTO), and supports filtering by preference strength, defect type, or dialogue structure. Note: Responses are model-generated, preference judgments are approximate; weak/moderate preference pairs may have high noise; source data is licensed under Etalab 2.0 and CC-BY-4.0, PII filtered, unmoderated content retained.
Compar:IA-French-Maxx 数据集概述
基本信息
- 数据集名称: Compar:IA-French-Maxx
- 语言: 法语
- 任务类型: 文本生成(text-generation)
- 标签: comparia、french、sft、dpo、preference、chatbot-arena、instruction-tuning
- 数据规模: 1K < n < 10K(共 6,575 行)
- 许可证: etalab-2.0 和 cc-by-4.0
- 数据格式: Parquet(单个训练集文件,位于
data/train-00000-of-00001.parquet)
数据集内容
该数据集包含针对真实 Compar:IA 对话的优化响应,共 6,575 条助手回复,每条回复都被设计为对真实 Compar:IA 对话的“最佳可能”回答,并配有被其击败的较弱回复。可用于监督微调(SFT)、偏好优化(如 DPO) 等任务。
数据子集构成
| 子集 | 行数 | 说明 |
|---|---|---|
| Arena - general | 1,500 | 原始竞技场两条回复中较难的一条(1,485 行有值);第二条竞技场回复(1,476 行有值) |
| Arena - both_bad | 2,400 | 人类投票者标记为 both_bad 的两条回复中较难的一条;另一条人类拒绝的回复 |
| Reactions | 2,675 | 收到用户负面反应的精确助手消息(2,674 行有值) |
| 总计 | 6,575 | 6,559 个可用偏好对;3,876 行有第二个负面回应 |
偏好强度分布
- strong: 5,359 对
- medium: 1,055 对
- weak: 145 对
- none: 16 对
核心列说明
| 列名 | 类型 | 用途 |
|---|---|---|
messages |
list[{role, content}] | 对话历史(以用户回合结束),用于 SFT 上下文或偏好提示 |
response_optimal |
string | 优化回复(纯文本、内容优先),用于 SFT 目标或偏好 chosen |
response_optimal_styled |
string | 相同内容但已格式化(标题/粗体/列表) |
rejected |
string | null |
rejected_2 |
string | null |
pref_strength |
string | null |
incorrect |
bool | null |
superficial |
bool | null |
instructions_not_followed |
bool | null |
conversation_turns |
int | 消息中的用户回合数 |
is_multi_turn |
bool | 用户回合数是否大于 1 |
prompt_chars |
int | 最终用户消息的字符数 |
source |
string | arena 或 reactions |
id |
string | 回溯到源数据集的可溯源标识 |
可筛选的标注信号
反应行保留了用户的非排他性缺陷标签(竞技场行为空值):
- incorrect(1,185 行): 用户标记回复为事实上或实质上不正确
- superficial(918 行): 用户标记回复过于浅显或不完整
- instructions_not_followed(817 行): 用户标记未遵循指令
优化回复的生成方法
- 使用 Le Chaton Fat 的代理流水线生成,并经过独立交叉评审和绝对批评者门控
- 竞技场数据: 优化回复经盲法成对评判,击败两个竞技场模型回复,并应用 Compar:IA 的风格控制,使其在实质上而非格式上获胜
- 反应数据: 优化回复修复了用户标记的特定缺陷,并经专家批评者门控
- 多轮竞技场对话使用优化的早期回复作为历史上下文
使用建议
- SFT: 将
response_optimal作为最终助手回合附加到messages后 - 偏好优化: 筛选有 rejected 的行(6,559 对),可选仅保留 strong 对(5,359 对);将
messages作为 prompt、response_optimal作为 chosen、rejected作为 rejected - 格式变体: 可将
response_optimal替换为response_optimal_styled以训练展示格式变体 - 按缺陷或对话形态筛选: 可依据
instructions_not_followed、is_multi_turn、superficial及prompt_chars等字段过滤
注意事项
- 回复为模型生成,LLM-as-judge 的偏好判断近似但不等于人类偏好
- weak/medium 对噪声较大,建议按
pref_strength过滤以获得干净的偏好训练数据 - 源数据许可和隐私条款适用(Etalab 2.0 / CC-BY-4.0,经 PII 过滤,保留未审核内容)