bilingual_children_speech
收藏资源简介:
双语儿童语音数据集是一个用于文本分类任务的数据集,特别关注于从儿童的英语语音模式预测其第一语言。数据集基于Kaggle的双语儿童语音语料库,提取了儿童的英语话语、第一语言(L1)、儿童ID和年龄信息,并将其整理为适合监督学习中长文本块的形式。数据集包含两种配置:原始配置仅包含来自CHILDES/Paradis语料库的原始话语;平衡配置则在原始数据基础上,为代表性不足的L1群体添加了由ChatGPT生成的合成话语。数据收集于2002年加拿大埃德蒙顿,25名以英语为第二语言的儿童参与了访谈,涵盖了多种话题。数据集包含的L1语言有:波斯语、阿拉伯语、粤语、西班牙语、普通话、韩语、乌克兰语、日语和罗马尼亚语。该数据集适用于研究和教育目的,尤其适合学术文本分类任务。
The Bilingual Child Speech Dataset is a dataset for text classification tasks, specifically focused on predicting childrens first language from their English speech patterns. Based on Kaggles Bilingual Child Speech Corpus, it extracts childrens English utterances, first language (L1), child ID, and age information, and organizes them into a format suitable for supervised learning with long text chunks. The dataset includes two configurations: the original configuration contains only raw utterances from the CHILDES/Paradis corpus, while the balanced configuration adds synthetic utterances generated by ChatGPT for underrepresented L1 groups. Data was collected in 2002 in Edmonton, Canada, with 25 children who speak English as a second language participating in interviews covering various topics. The L1 languages included are: Persian, Arabic, Cantonese, Spanish, Mandarin, Korean, Ukrainian, Japanese, and Romanian. This dataset is suitable for research and educational purposes, particularly for academic text classification tasks.
双语儿童语音数据集概述
数据集基本信息
- 数据集名称:Bilingual Children Speech Dataset
- 语言:英语
- 任务类型:文本分类(多类分类)
- 数据规模:1,000 < n < 10,000
- 标签:儿童语言、双语、语言学、母语识别、合成数据
数据集来源
数据集来源于以下两个主要来源:
原始数据于2002年在加拿大埃德蒙顿收集,25名学习英语作为第二语言的儿童参与了访谈,话题涉及年龄、喜爱的食物、上学情况等。
数据集特征
每条数据包含以下字段:
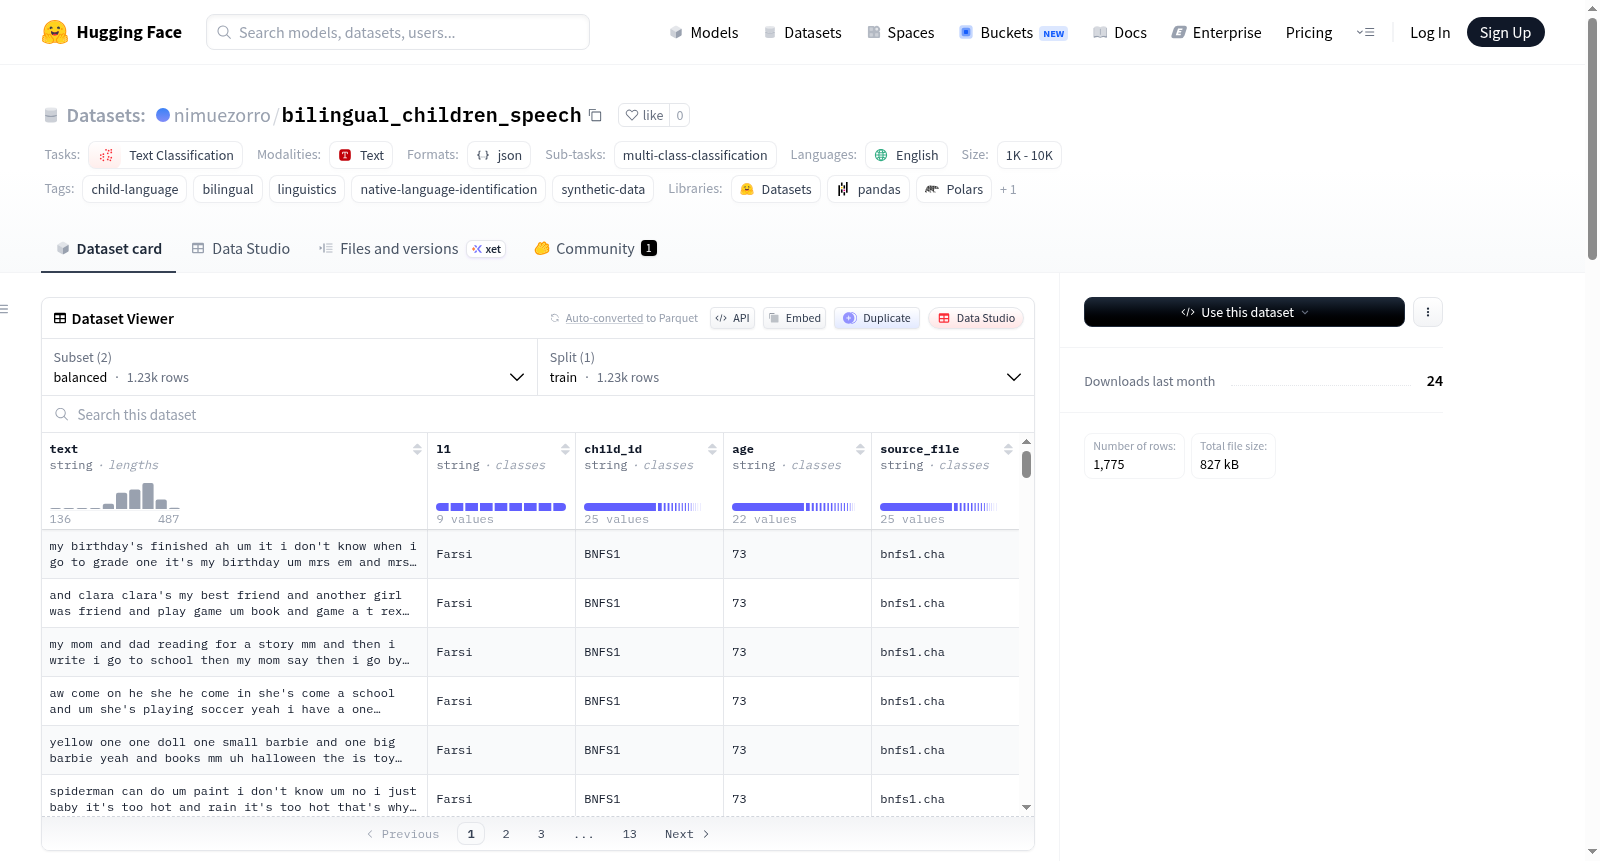
| 字段名 | 类型 | 说明 |
|---|---|---|
| text | 字符串 | 儿童英语话语文本 |
| l1 | 字符串 | 儿童的第一语言 |
| child_id | 字符串 | 儿童唯一标识 |
| age | 字符串 | 儿童年龄 |
| source_file | 字符串 | 源文件名 |
可用配置
original(原始版本)
- 数据文件:
childes_l1_dataset.jsonl - 仅包含来自原始CHILDES/Paradis语料库的话语
balanced(平衡版本)
- 数据文件:
childes_l1_dataset_balanced.jsonl - 包含原始数据以及通过ChatGPT生成的合成数据,用于平衡各L1组别的样本数量
- 合成数据的
child_id、age和source_file字段均标记为synthetic
包含的第一语言类别
- Farsi(波斯语)
- Arabic(阿拉伯语)
- Cantonese(粤语)
- Spanish(西班牙语)
- Mandarin(普通话)
- Korean(韩语)
- Ukrainian(乌克兰语)
- Japanese(日语)
- Romanian(罗马尼亚语)
数据用途
- 该数据集专为学术文本分类任务创建,目标是根据英语语音模式预测儿童的第一语言(母语识别)
- 数据集规模较小,主要用于研究和教育目的,不适合生产系统
数据示例
json { "text": "my birthdays finished ah um it i dont know when i go to grade one its my birthday um mrs em and mrs bee um two of them yes i like everything but i just i dont like blocks i dont like it everybody fight with blocks nobody giving that to me nobody giving that to her and they say doesnt want to give me blocks um paint and house and school and paint and draw", "l1": "Farsi", "child_id": "BNFS1", "age": "73", "source_file": "bnfs1.cha" }