timeomni-1-testbed
收藏资源简介:
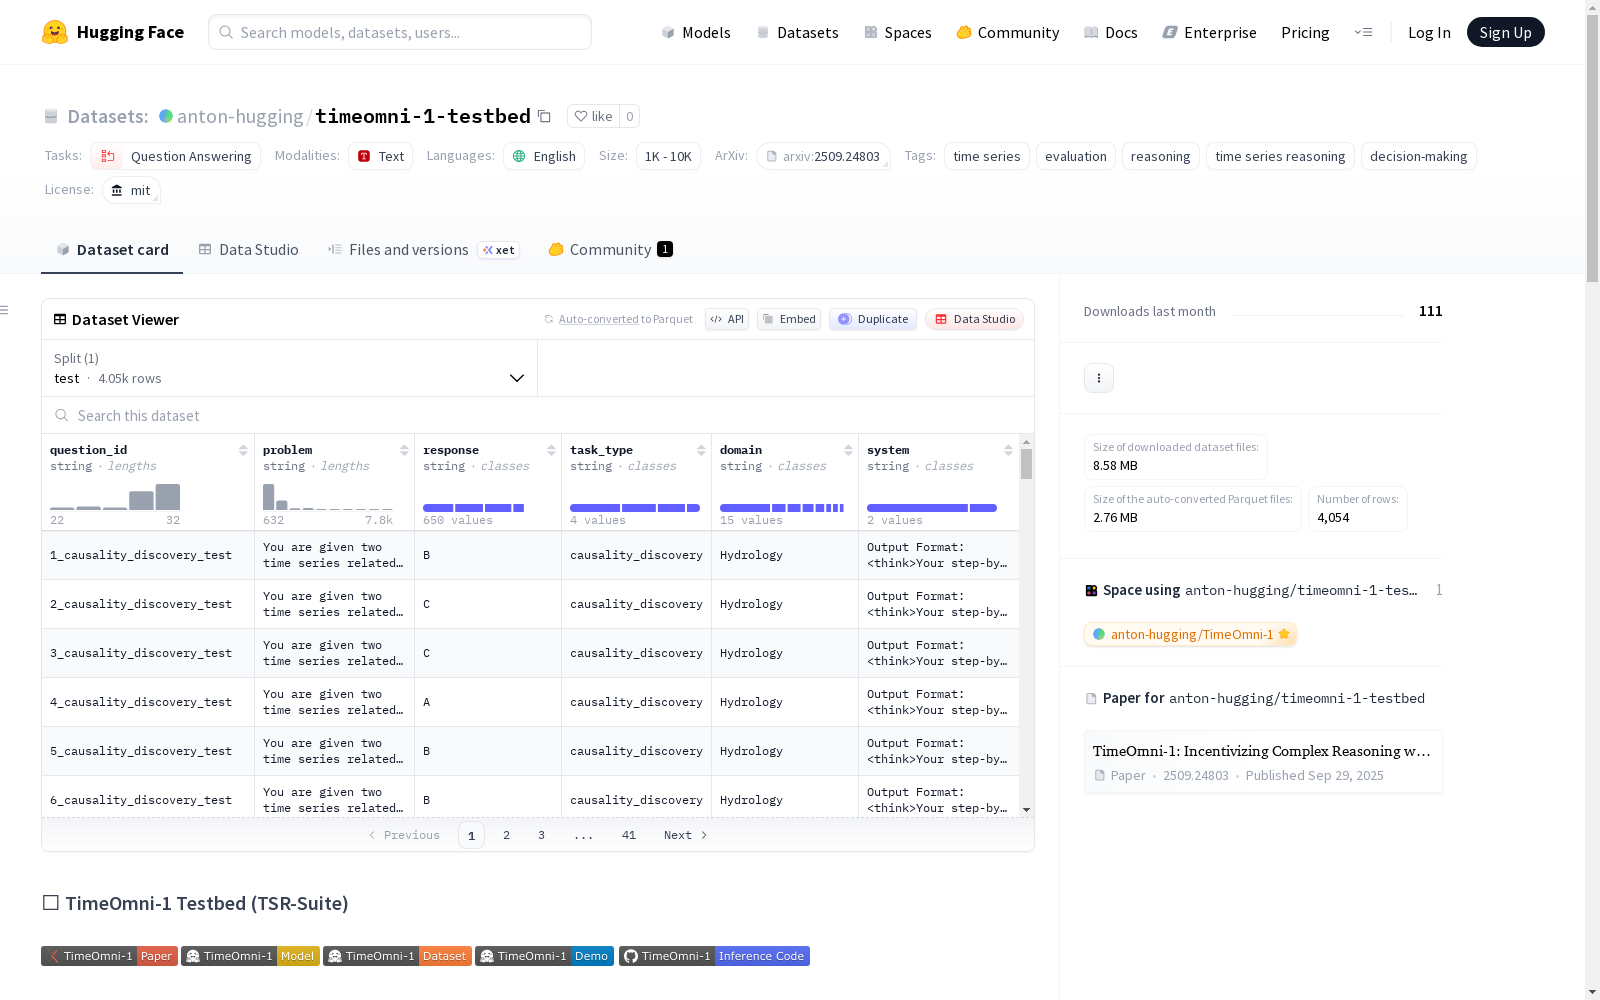
TimeOmni-1 Testbed (TSR-Suite) 是一个专注于时间序列推理的数据集,旨在评估模型在感知、外推和决策制定等核心能力上的表现。数据集包含四种任务类型:场景理解、因果关系发现、事件感知预测和决策制定。数据分为分布内测试集(id_test,1,606个样本)和分布外测试集(ood_test,2,448个样本),总计4,054个样本。每个样本包含以下字段:question_id(唯一标识符,格式为{number}_{task_type}_test)、problem(问题陈述,包含时间序列和辅助上下文)、response(真实答案,通常为单个大写字母或预测序列)、task_type(任务类型)、domain(时间序列的来源领域,如水文、能源电池套利)和system(模型输出格式的系统提示)。数据集适用于问答任务,主要用于时间序列推理和决策制定的评估。
TimeOmni-1 Testbed (TSR-Suite) is a dataset dedicated to time series reasoning, designed to evaluate model performance on core capabilities including perception, extrapolation, and decision-making. The dataset includes four task categories: scenario understanding, causal discovery, event perception and prediction, and decision-making. The dataset is split into an in-distribution test set (id_test, 1,606 samples) and an out-of-distribution test set (ood_test, 2,448 samples), with a total of 4,054 samples. Each sample contains the following fields: question_id (unique identifier formatted as {number}_{task_type}_test), problem (problem statement that includes time series data and auxiliary context), response (ground-truth answer, typically a single uppercase letter or a predicted sequence), task_type (the type of the task), domain (the source domain of the time series, e.g., hydrology, energy battery arbitrage), and system (system prompt specifying the model output format). This dataset is tailored for question answering tasks, and is primarily utilized for evaluating time series reasoning and decision-making capabilities.
TimeOmni-1 Testbed (TSR-Suite) 数据集概述
数据集基本信息
- 许可证: MIT
- 任务类别: 问答
- 标签: 时间序列、评估、推理、时间序列推理、决策制定
- 语言: 英语
- 数据规模: 1K<n<10K
核心能力与任务类型
该数据集旨在评估时间序列推理的三个核心能力,涵盖以下四种任务类型:
- 感知能力
- 任务1:场景理解:识别生成给定时间序列的场景。
- 任务2:因果发现:发现时间序列之间的因果关系。
- 外推能力
- 任务3:事件感知预测:在考虑外部事件的情况下进行预测。
- 决策制定能力
- 任务4:决策制定:做出最大化下游效用(例如利润)的最优行动。
数据集信息
1. 数据集划分
- id_test: 分布内测试集(1,606个样本)
- ood_test: 分布外测试集(2,448个样本)
2. 数据集统计
| 任务类型 | ID 测试集 | OOD 测试集 | 总计 |
|---|---|---|---|
| 场景理解 | 200 | 899 | 1,099 |
| 因果发现 | 800 | 800 | 1,600 |
| 事件感知预测 | 418 | 476 | 894 |
| 决策制定 | 188 | 273 | 461 |
| 总计 | 1,606 | 2,448 | 4,054 |
3. 数据字段
question_id: 唯一标识符,格式为{数字}_{任务类型}_testproblem: 问题陈述,包含时间序列(及任何辅助上下文)和问题。response: 真实答案(通常为单个大写字母或预测序列)task_type: 上述四种任务类型之一domain: 时间序列的源领域(例如,水文学、能源电池套利)system: 模型输出格式的系统提示
使用方法
python from datasets import load_dataset
dataset = load_dataset("anton-hugging/timeomni-1-testbed") id_test = dataset["id_test"] ood_test = dataset["ood_test"]
评估方法
报告成功率(SR),即模型输出产生有效且可提取答案的比例。所有后续评估指标仅在这些有效案例上计算,以确保性能反映时间序列推理能力而非指令遵循合规性。
- 对于任务1、2和4:模型输出单个大写字母(A、B、C或D)。准确率(ACC)为正确预测的百分比。
- 对于任务3:模型输出预测序列(例如,[2, 20, 21, ..., 83])。准确率通过平均绝对误差(MAE)衡量。
引用
bibtex @inproceedings{ guan2026timeomni, title={TimeOmni-1: Incentivizing Complex Reasoning with Time Series in Large Language Models}, author={Tong Guan and Zijie Meng and Dianqi Li and Shiyu Wang and Chao-Han Huck Yang and Qingsong Wen and Zuozhu Liu and Sabato Marco Siniscalchi and Ming Jin and Shirui Pan}, booktitle={The Fourteenth International Conference on Learning Representations}, year={2026}, url={https://openreview.net/forum?id=kOIclg7muL} }