project-gutenberg-clean
收藏资源简介:
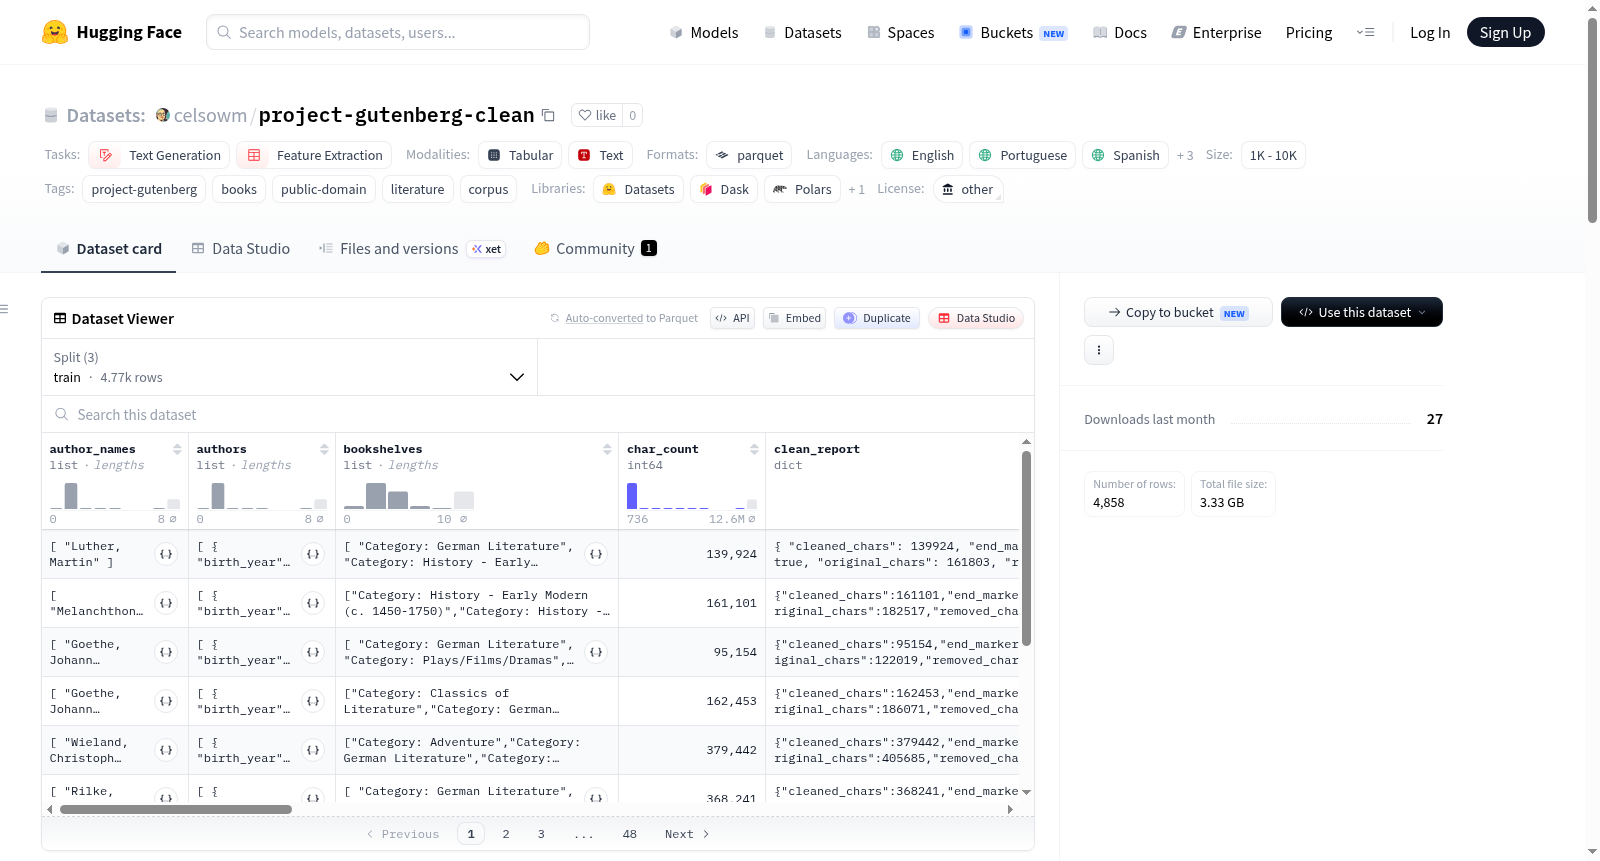
project-gutenberg-clean 是一个经过清理的 Project Gutenberg 书籍数据集,通过 Gutendex API 下载并处理而成。该数据集的主要目的是移除原始 Project Gutenberg 文本中的页眉、页脚、许可证声明和样板文本等非内容部分,从而提供更干净的文本语料,适用于文本生成和特征提取等自然语言处理任务。数据集按语言进行分区,目前包含葡萄牙语(pt)版本,总计 160 条记录,其中训练集 158 条,验证集和测试集各 1 条。数据结构以 Parquet 文件(可能还有 JSONL 文件)组织,按语言目录(如 data/pt)存放训练、验证和测试分割。每个数据样本包含多个字段:gutenberg_id(Project Gutenberg 中的书籍 ID)、title(书名)、authors 和 author_names(作者信息)、languages(元数据中的语言)、language_partition(分区语言)、subjects 和 bookshelves(主题和书架分类)、copyright(版权信息)、gutenberg_url 和 source_text_url(原始 URL)、text(清理后的文本内容)、char_count 和 word_count(文本的字符和单词计数)以及 license_note(使用和清理说明)。数据来源于 Project Gutenberg 的原始文本和 Gutendex 的元数据,清理工作由 gutenberg-dataset-builder 工具完成。用户需注意,尽管数据集已进行清理,但使用前仍应自行核实相关版权和许可规定,确保符合所在司法管辖区的法律要求。
project-gutenberg-clean is a cleaned dataset of Project Gutenberg books, downloaded and processed via the Gutendex API. Its primary purpose is to remove non-content parts such as headers, footers, license statements, and boilerplate text from the original Project Gutenberg texts, providing a cleaner text corpus suitable for natural language processing tasks like text generation and feature extraction. The dataset is partitioned by language, currently including a Portuguese (pt) version with a total of 160 records, comprising 158 training samples, and 1 validation and 1 test sample each. The data is organized in Parquet files (and possibly JSONL files) within language-specific directories (e.g., data/pt) for training, validation, and test splits. Each data sample contains multiple fields: gutenberg_id (book ID in Project Gutenberg), title (book title), authors and author_names (author information), languages (language from metadata), language_partition (partitioned language), subjects and bookshelves (subject and bookshelf classifications), copyright (copyright information), gutenberg_url and source_text_url (original URLs), text (cleaned text content), char_count and word_count (character and word counts of the text), and license_note (usage and cleaning notes). The data originates from Project Gutenbergs original texts and Gutendexs metadata, with cleaning performed by the gutenberg-dataset-builder tool. Users should note that, although the dataset has been cleaned, they should verify relevant copyright and licensing regulations before use to ensure compliance with legal requirements in their jurisdiction.
数据集概述:project-gutenberg-clean
基本信息
- 数据集名称:project-gutenberg-clean
- 许可协议:other(其他)
- 语言:英语(en)、葡萄牙语(pt)、西班牙语(es)、法语(fr)、德语(de)、意大利语(it)
- 任务类别:文本生成(text-generation)、特征提取(feature-extraction)
- 标签:project-gutenberg、books、public-domain、literature、corpus
- 数据规模:1K < 记录数 < 10K
- 总记录数:1,260 条
- 生成日期:2026-05-20
- 语言模式:all(包含所有语言)
数据来源与处理
数据来源于 Project Gutenberg,通过 Gutendex API 下载,并经过深度清洗处理,专注于为 LLM 训练提供高质量文本。主要处理亮点包括:
- 深度清洗:移除标准页眉/页脚、转录注释、编辑前言以及多语言 OCR 伪影(如
[Illustration]、[Music]等标签) - 注释处理:识别并移除由特殊字符序列(如哈希符号
####)分隔的注释块 - 数据划分:按语言组织,并分为训练集(train)、验证集(validation)和测试集(test),可直接使用
datasets库加载
数据结构
数据集按语言分目录存储,每个语言目录下包含三个 Parquet 文件:
data/ en/ train.parquet validation.parquet test.parquet pt/ train.parquet validation.parquet test.parquet
(若生成时指定 --formats parquet,jsonl 参数,可能还会存在 .jsonl 文件)
字段说明
| 字段名 | 说明 |
|---|---|
gutenberg_id |
书籍在 Project Gutenberg 中的 ID |
title |
书籍标题 |
authors / author_names |
作者信息(来自 Gutendex 元数据) |
languages |
原始元数据中的语言 |
language_partition |
记录所在文件夹的语言 |
subjects / bookshelves |
来源分类信息 |
copyright |
来源报告的版权状态 |
gutenberg_url / source_text_url |
来源 URL |
text |
清洗后的纯文本内容 |
char_count / word_count |
清洗后文本的字符数和单词数 |
license_note |
使用和清洗说明 |
各语言数据分布
| 语言 | 训练集 | 验证集 | 测试集 | 总计 |
|---|---|---|---|---|
| 英语(en) | 86 | 1 | 1 | 88 |
| 葡萄牙语(pt) | 263 | 2 | 2 | 267 |
| 西班牙语(es) | 289 | 2 | 2 | 293 |
| 法语(fr) | 166 | 1 | 1 | 168 |
| 德语(de) | 251 | 2 | 2 | 255 |
| 意大利语(it) | 187 | 1 | 1 | 189 |
加载示例
python from datasets import load_dataset
加载英语数据
ds_en = load_dataset("celsowm/project-gutenberg-clean", data_dir="data/en")
加载葡萄牙语数据
ds_pt = load_dataset("celsowm/project-gutenberg-clean", data_dir="data/pt")
许可与使用注意事项
- Project Gutenberg 基于美国版权法评估文本版权状态
- 本数据集管道在检测到标记时移除了页眉/页脚以及许可证/商标引用
- 数据集用户仍负责根据其所在司法管辖区和使用场景核实相关权限