ethanz001/CANLegalRagBench
收藏资源简介:
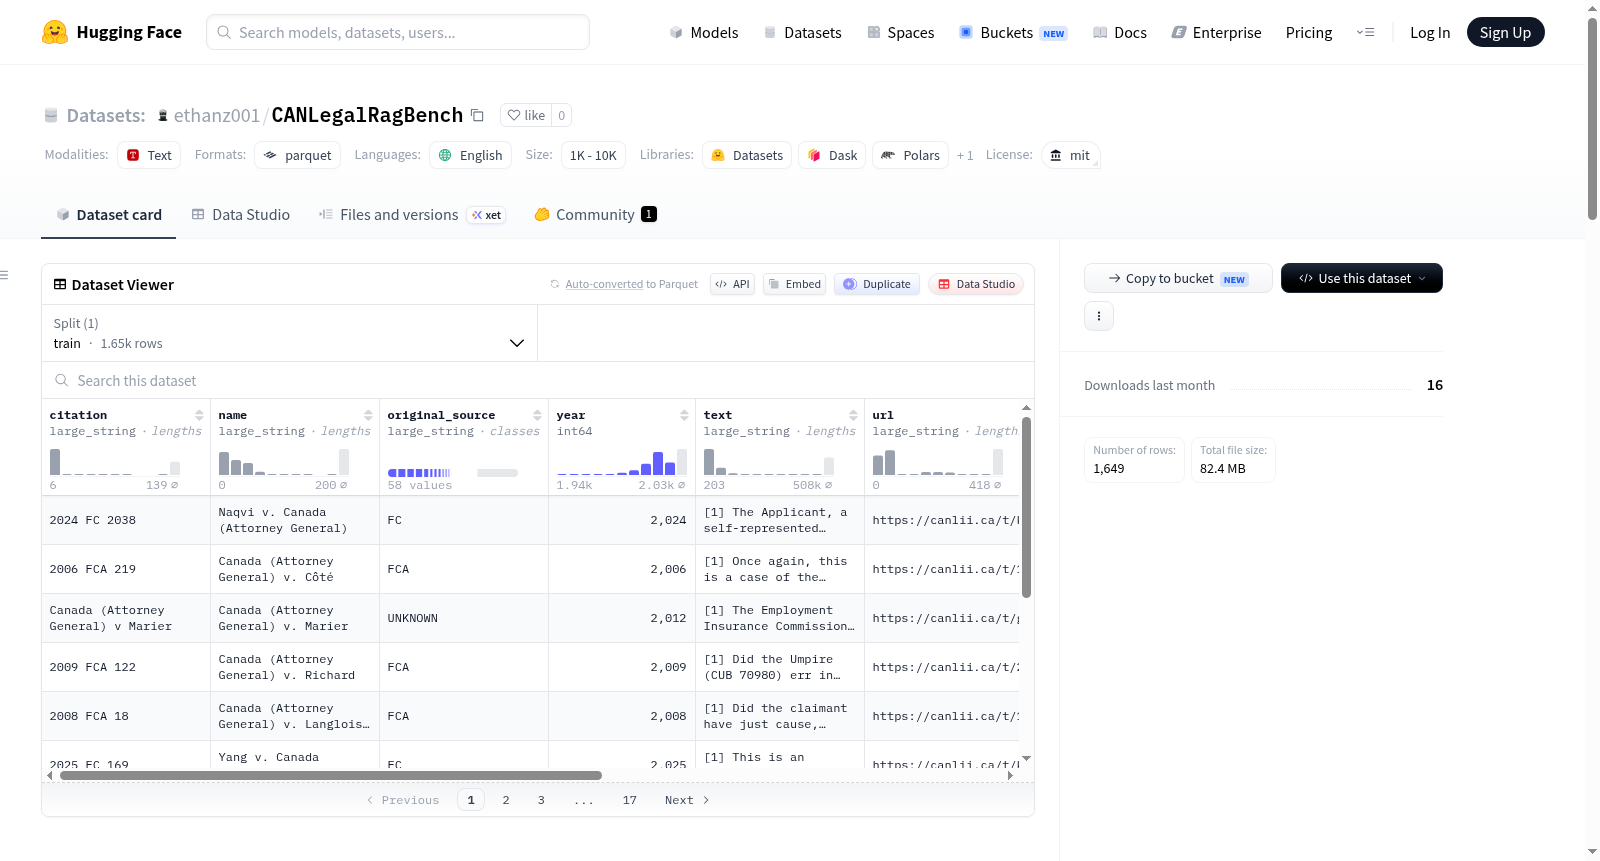
CanLegalRAGBench 是一个用于加拿大法律检索增强生成(RAG)任务的数据集。该数据集主要包含来自不同加拿大来源的案例法(判例法)以及少量法规。查询设计旨在模拟AI聊天机器人用户的真实问题,这些查询通过Gemini-2.5-Pro生成,并由行业专家验证样本。案例法通过人工注释员收集作为真实检索的基础,并补充了来自A2AJ加拿大法律数据集和CasewayAI提供的私人文档。数据集支持研究和开发AI系统以改善司法访问,提供法律查询、真实检索文档以及由LLM生成并经专家注释员验证的答案,用于评估检索和文本生成性能。数据集结构包括检索文档字段(如引用、名称、原始来源、年份、文本、URL等)和查询字段(如查询ID、查询文本、答案、批次ID等)。数据集由UBC NLP Lab策划,资金来自Mitacs和Caseway,语言主要为英语(部分法语文档),许可证为MIT(但检索文档来源文本受其自身许可证约束)。
CanLegalRAGBench is a dataset for Canadian legal Retrieval-Augmented Generation (RAG) tasks. It primarily contains case law from various Canadian sources and a small amount of legislation. The queries are designed to mimic real questions from users of an AI chatbot, generated via Gemini-2.5-Pro with samples verified by an industry expert. Case laws were gathered by human annotators for ground truth retrieval, supplemented by the A2AJ Canadian Legal Dataset and private documents from CasewayAI. The dataset is intended for research into developing AI systems to improve justice, providing legal queries, ground truth retrieval documents, and answers generated by an LLM and edited/verified by expert annotators for evaluating retrieval and text generation. The dataset structure includes fields for retrieval documents (e.g., citation, name, original_source, year, text, url) and queries (e.g., query_id, query_text, answer, batch_id). It is curated by the UBC NLP Lab, funded by Mitacs and Caseway, with languages mainly English (some French in English documents), and licensed under MIT (though retrieval document source texts are subject to their own licenses).