sapienzanlp/ReTraceQA
收藏资源简介:
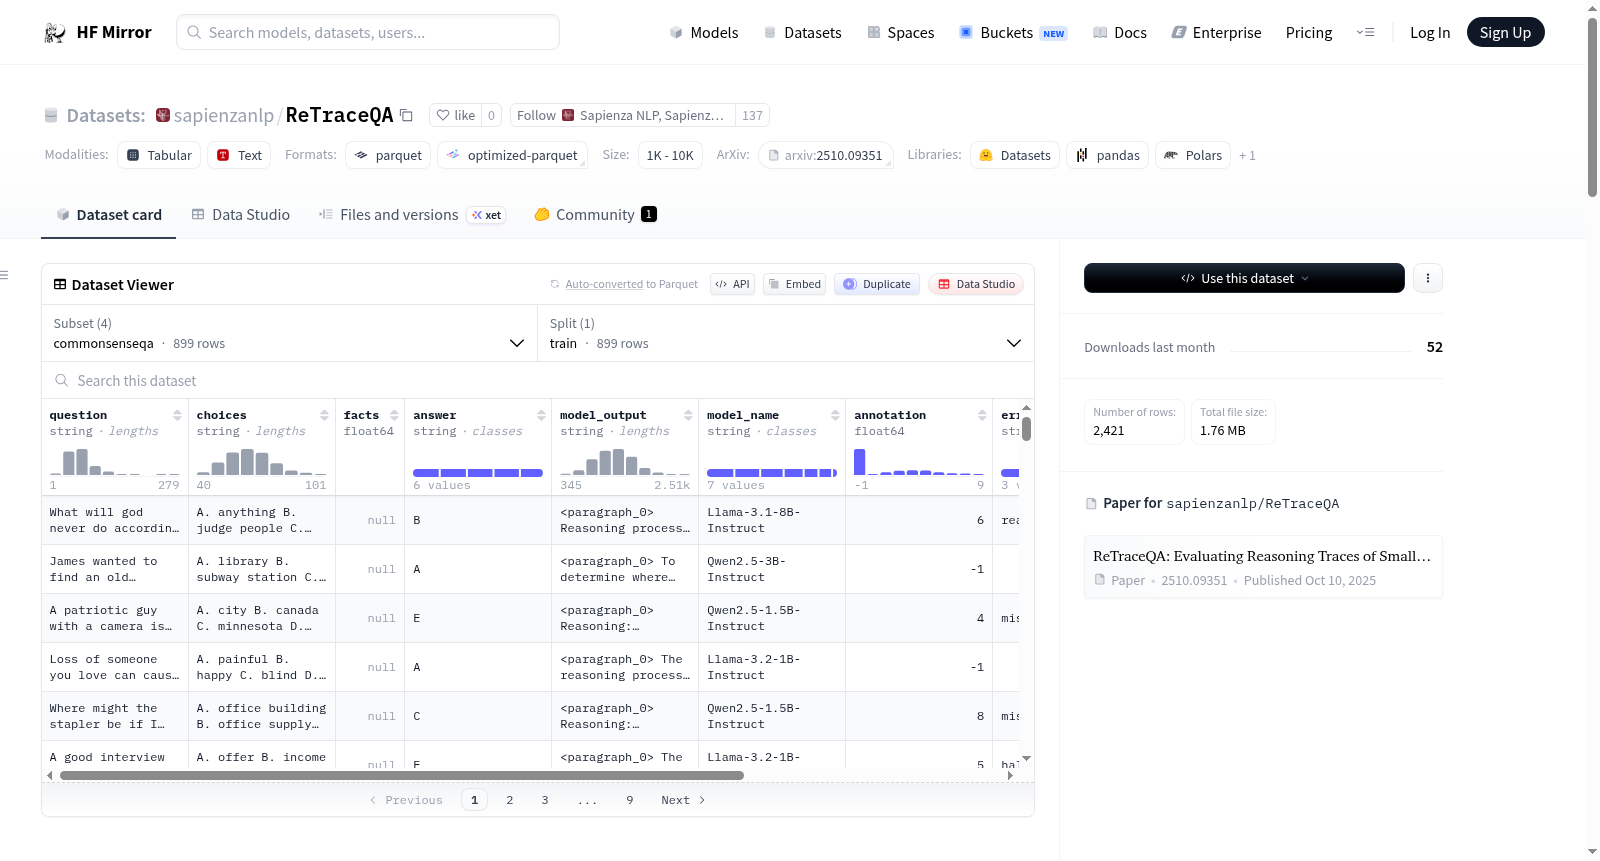
--- dataset_info: - config_name: commonsenseqa features: - name: question dtype: string - name: choices dtype: string - name: facts dtype: float64 - name: answer dtype: string - name: model_output dtype: string - name: model_name dtype: string - name: annotation dtype: float64 - name: error_class dtype: string - name: dataset_index dtype: string splits: - name: train num_bytes: 1343503 num_examples: 899 download_size: 608876 dataset_size: 1343503 - config_name: openbookqa features: - name: question dtype: string - name: choices dtype: string - name: facts dtype: string - name: answer dtype: string - name: model_output dtype: string - name: model_name dtype: string - name: annotation dtype: float64 - name: error_class dtype: string - name: dataset_index dtype: string splits: - name: train num_bytes: 697655 num_examples: 428 download_size: 322285 dataset_size: 697655 - config_name: qasc features: - name: question dtype: string - name: choices dtype: string - name: facts dtype: float64 - name: answer dtype: string - name: model_output dtype: string - name: model_name dtype: string - name: annotation dtype: float64 - name: error_class dtype: string - name: dataset_index dtype: string splits: - name: train num_bytes: 730605 num_examples: 464 download_size: 323909 dataset_size: 730605 - config_name: strategyqa features: - name: question dtype: string - name: choices dtype: float64 - name: facts dtype: string - name: answer dtype: bool - name: model_output dtype: string - name: model_name dtype: string - name: annotation dtype: float64 - name: error_class dtype: string - name: dataset_index dtype: string splits: - name: train num_bytes: 984730 num_examples: 630 download_size: 492766 dataset_size: 984730 configs: - config_name: commonsenseqa data_files: - split: train path: commonsenseqa/train-* - config_name: openbookqa data_files: - split: train path: openbookqa/train-* - config_name: qasc data_files: - split: train path: qasc/train-* - config_name: strategyqa data_files: - split: train path: strategyqa/train-* --- # Dataset Card for ReTraceQA ## Dataset Summary **ReTraceQA** is a dataset designed to evaluate the reasoning traces of Small Language Models (SLMs) on commonsense reasoning tasks. It includes model-generated traces across four benchmark datasets: `CommonsenseQA`, `OpenBookQA`, `QASC`, and `StrategyQA`. During the construction of ReTraceQA, only correct instances from the original benchmarks were retained, and erroneous instances were manually removed to ensure data quality. Each item in the dataset contains a reasoning trace segmented into atomic steps (“paragraphs”), along with a human-annotated label indicating the index of the first erroneous step. If no error is present, the label is set to `-1`, indicating that the reasoning trace is entirely correct. Additionally, for traces containing errors, each item includes an error classification specifying the type of mistake: `hallucination`, `reasoning`, or `misinterpretation`. For more details, refer to our paper: [ReTraceQA: Evaluating Reasoning Traces of Small Language Models in Commonsense Question Answering ](https://arxiv.org/abs/2510.09351). ## Languages This dataset is in English (en). ## Dataset Structure The dataset consists of four subset one for each dataset : `CommonsenseQA`, `OpenBookQA`, `QASC`, and `StrategyQA`. All the subsets share the same structure and contain the following fields: - **`question` (str)**: The text of the question, drawn from the commonsense benchmarks. - **`choices` (str)**: The text of the choices drawn from the commonsense benchmarks, it is not included for strategyqa benchmark. - **`facts` (str)**: The text of the facts used as ground truth for evaluation of strategyqa subset. - **`model_output` (str)**: A synthetic reasoning chain generated from SLMs, the text was postprocessed and divided into paragraphs. - **`model_name` (str)**: The name of the SLM used to generate the synthetic reasonig trace. - **`annotation` (int)**: The index of the first erroneous step if present in the `model_output`; `-1` if the trace is correct. - **`error_class` (str)**: The annotated error category for erroneous traces, the categories are: `hallucination`, `reasoning`, and `misinterpretation`. - **`dataset_index` (str)**: An unique index for the item. An example of instance (commonsenseqa) is as follows: ```json { "question": "What will god never do according to religion?", "choices": "A. anything\nB. judge people\nC. work miracles\nD. judge men\nE. everywhere", "facts": null, "answer": "B", "model_output": "<paragraph_0>\nReasoning process:\n</paragraph_0>\n\n<paragraph_1>\nTo answer this..." "model_name": "Llama-3.1-8B-Instruct", "annotation": 6, "error_class": "reasoning", "dataset_index": "b62d7d1b5eec31be0b65146a9fc069e0", } ``` ## Dataset Statistics ### Error Index Annotations Plot for the error index annotation over RetraceQA benchmark: <p align="center"> <img src="https://github.com/Andrew-Wyn/images/blob/master/retraceqa/benchmark_error_steps.png?raw=true" width="500"/> </p> ### Error Category Annotations Distribution of the error categories annotation over RetraceQA benchmark: <p align="center"> <img src="https://github.com/Andrew-Wyn/images/blob/master/retraceqa/avg-error-type.png?raw=true" width="500"/> </p> ## Citation If you use ReTraceQA in your research, please cite the following paper: ```bibtex @misc{molfese2025retraceqaevaluatingreasoningtraces, title={ReTraceQA: Evaluating Reasoning Traces of Small Language Models in Commonsense Question Answering}, author={Francesco Maria Molfese and Luca Moroni and Ciro Porcaro and Simone Conia and Roberto Navigli}, year={2025}, eprint={2510.09351}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2510.09351}, } ```