wikitongues
收藏资源简介:
WikiTongues语音语料库是一个包含700多种语言对话音频的集合,适用于口语建模或语音表示学习。数据集包含未经分割的原始音频,采样率为16kHz,单声道格式。每个音频片段通常为2-10分钟,包含一个或多个说话者用他们的语言进行对话,有时说话者可能在同一片段中切换语言。当前版本的数据集不包含每个片段所使用语言的标签,但计划在不久的将来更新中包含此信息。数据集总时长约为70小时。数据集从WikiTongues项目爬取,用于训练XEUS,一个支持4000多种语言的多语言语音编码器。
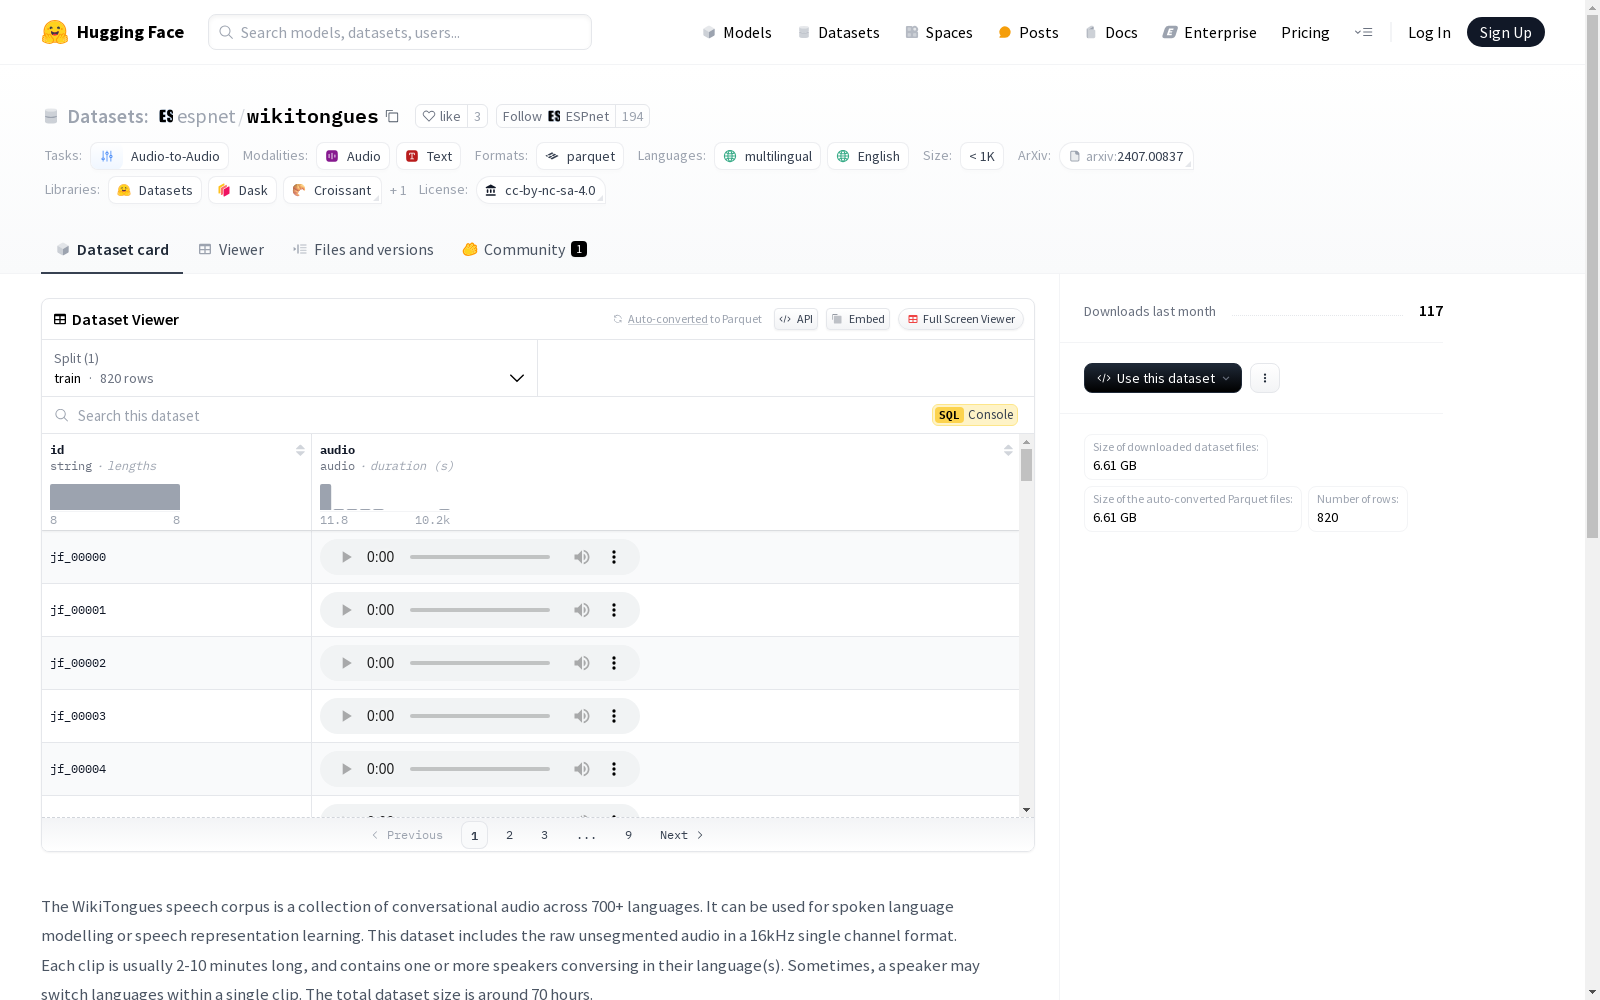
WikiTongues Speech Corpus is a collection of conversational audio spanning over 700 languages, tailored for spoken language modeling and speech representation learning. The dataset contains unsegmented raw audio encoded at a 16 kHz sampling rate in monaural format. Each audio clip typically ranges from 2 to 10 minutes in length, featuring conversations between one or more speakers in their respective languages, with occasional language switching by speakers within a single clip. The current iteration of the dataset does not include language labels for each clip, though this information is scheduled to be added in an upcoming update. The total cumulative duration of the dataset is approximately 70 hours. The dataset was crawled from the WikiTongues project, and is intended for training XEUS, a multilingual speech encoder that supports over 4000 languages.
数据集概述
数据集信息
- 特征:
id: 字符串类型audio: 音频类型,采样率为16000Hz
- 分割:
train: 包含820个样本,总字节数为6731807325
- 下载大小: 6611613572字节
- 数据集大小: 6731807325字节
- 配置:
default: 包含训练数据文件,路径为data/train-*
- 语言: 多语种,包括英语
- 任务类别: 音频到音频
数据集描述
- 内容: WikiTongues语音语料库包含700多种语言的对话音频。
- 格式: 原始未分割音频,16kHz单通道格式。
- 时长: 每个片段通常为2-10分钟,包含一个或多个说话者用其语言进行对话。
- 总时长: 约70小时。
- 当前版本: 不包含每个片段中使用的语言标签,该信息将在未来更新中包含。
许可证
- 许可证: Creative Commons Attribution-NonCommercial-ShareAlike 4.0