JUÁ
收藏资源简介:
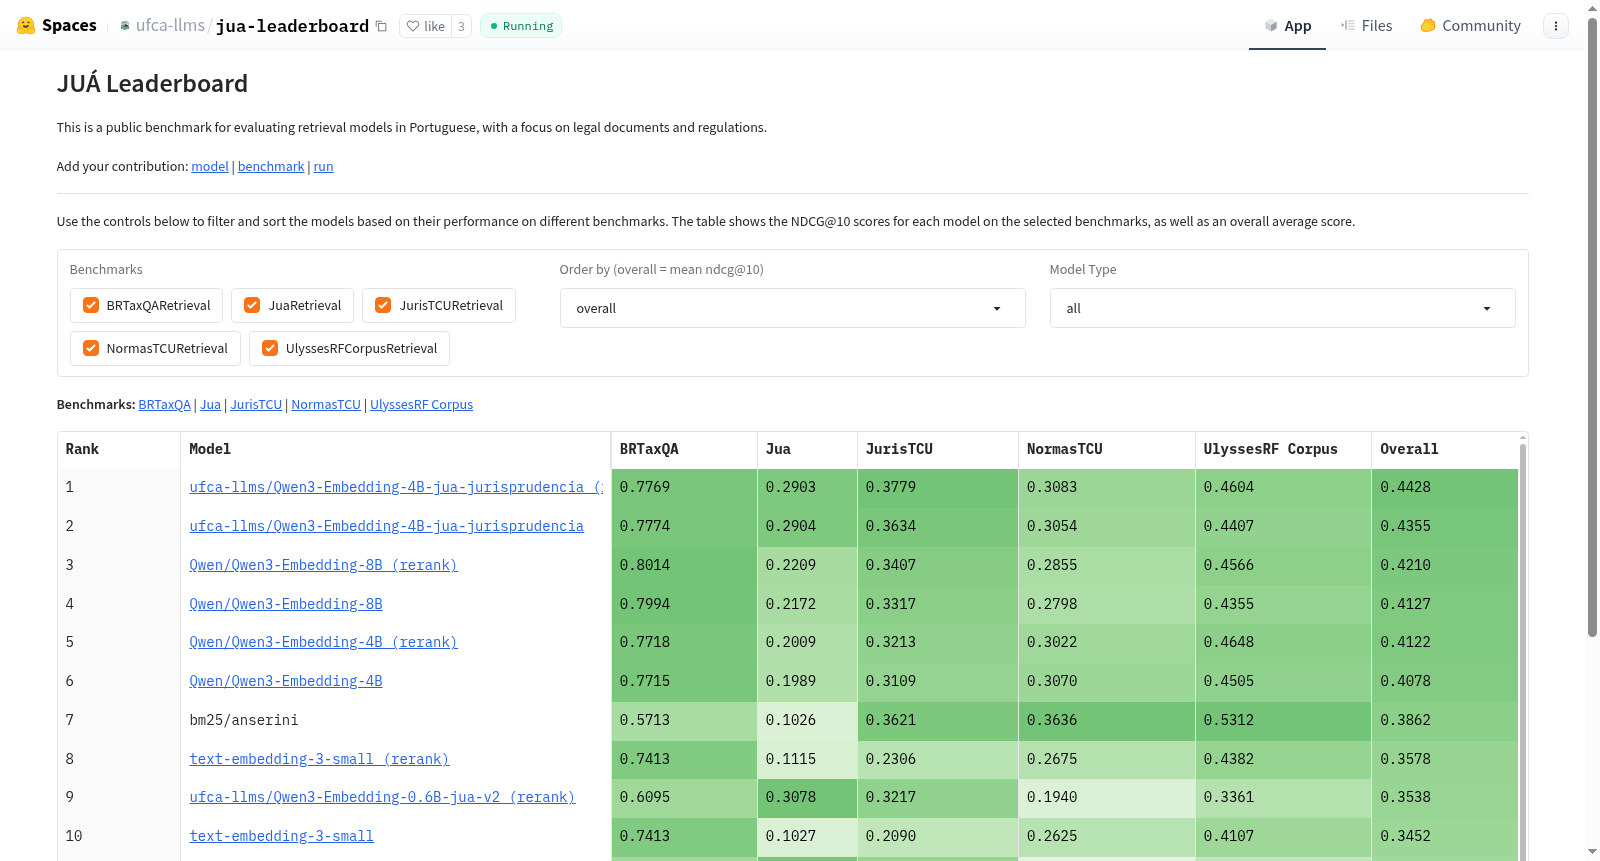
JUÁ是首个针对巴西法律文本的多领域信息检索基准测试,由卡拉里联邦大学等机构联合构建,涵盖判例、法规和问答式法律检索场景。数据集包含1714条测试样本,源自巴西联邦审计法院(TCU)精选判例库,采用难度分层抽样策略构建,并基于BM25算法标注检索难度等级。其核心数据为法律摘要(enunciado)与对应裁决摘要(excerto)的配对,支持二元精确匹配评估。该数据集旨在为葡萄牙语法律检索提供标准化评估框架,推动法律AI在判例分析、合规审查等场景的应用。
JUÁ is the first multi-domain information retrieval benchmark for Brazilian legal texts, jointly constructed by institutions including the Federal University of Cariri and other partners. It covers three scenarios: case law, statutory regulations, and question-answering legal retrieval scenarios. The dataset contains 1714 test samples sourced from the curated case law repository of the Brazilian Federal Court of Audit (TCU), and was built using a stratified difficulty sampling strategy. The retrieval difficulty levels of the samples were annotated based on the BM25 algorithm. Its core data consists of paired legal summaries (enunciado) and their corresponding ruling summaries (excerto), which supports binary exact match evaluation. This dataset aims to provide a standardized evaluation framework for Portuguese legal retrieval, and promote the application of legal AI in scenarios such as case law analysis and compliance review.