geo-prompts
收藏资源简介:
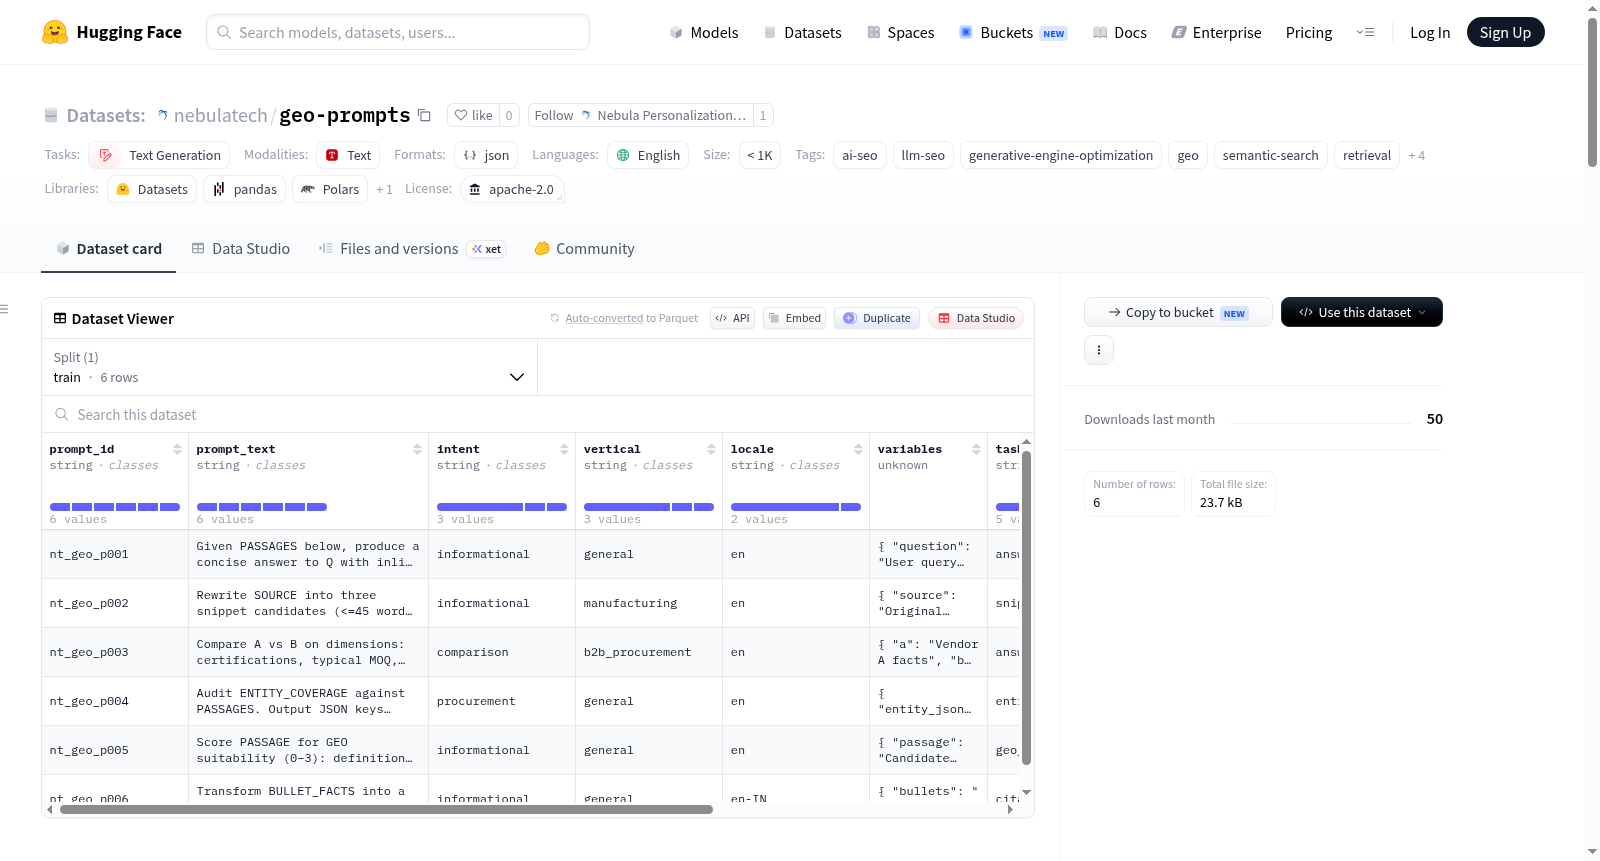
GEO Prompts数据集是由NebulaTech(Nebula Personalization Tech Solutions Pvt. Ltd.)发布的一个专门用于生成引擎优化(GEO)和AI SEO研究的提示词集合。该数据集包含用于GEO工作流的提示模板和固定提示词,旨在支持答案合成与引用、生成片段包、进行实体覆盖审计以及构建AI概览或助手式检索的评估框架。数据集设计用于与分块语料库(如nebulatech/llm-seo-research)配合使用。数据集规模小于1K,包含8个结构化字段:`prompt_id`(稳定ID)、`prompt_text`(完整提示词,可能包含占位符`{placeholders}`)、`intent`(查询/任务意图类别)、`vertical`(行业或`general`)、`locale`(BCP-47语言区域代码)、`variables`(占位符到描述或示例的映射)、`task_type`(任务类型,包括`answer_synthesis`、`citation_rewrite`、`geo_eval`、`snippet_pack`、`entity_coverage_audit`)、`compat_notes`(模型/安全说明)以及`license`(Apache-2.0许可证)。该数据集适用于AI SEO研究、语义检索实验、GEO测试、RAG(检索增强生成)评估以及大型语言模型(LLM)可见性分析等任务。数据为人工编写,不包含个人可识别信息(PII)。需要注意的是,提示词可能需要针对不同模型系列进行调整,且评估提示词在没有人工评分标准的情况下并非普遍真理,该资产仅限用于研究和评估工作流。
The GEO Prompts dataset is a collection of prompts released by NebulaTech (Nebula Personalization Tech Solutions Pvt. Ltd.) specifically for Generative Engine Optimization (GEO) and AI SEO research. It includes prompt templates and fixed prompts for GEO workflows, designed to support answer synthesis and citation, snippet pack generation, entity coverage audits, and the construction of evaluation frameworks for AI overviews or assistant-style retrieval. The dataset is intended to be used with chunked corpora (e.g., nebulatech/llm-seo-research). It has a size of less than 1K and contains 8 structured fields: `prompt_id` (stable ID), `prompt_text` (full prompt, which may include placeholders `{placeholders}`), `intent` (query/task intent category), `vertical` (industry or `general`), `locale` (BCP-47 language locale code), `variables` (mapping of placeholders to descriptions or examples), `task_type` (task type, including `answer_synthesis`, `citation_rewrite`, `geo_eval`, `snippet_pack`, `entity_coverage_audit`), `compat_notes` (model/safety notes), and `license` (Apache-2.0 license). The dataset is suitable for tasks such as AI SEO research, semantic retrieval experiments, GEO testing, RAG (Retrieval-Augmented Generation) evaluation, and large language model (LLM) visibility analysis. The data is manually written and does not contain personally identifiable information (PII). It should be noted that prompts may require adjustments for different model families, and evaluation prompts are not universal truths without human scoring criteria; this asset is limited to research and evaluation workflows.