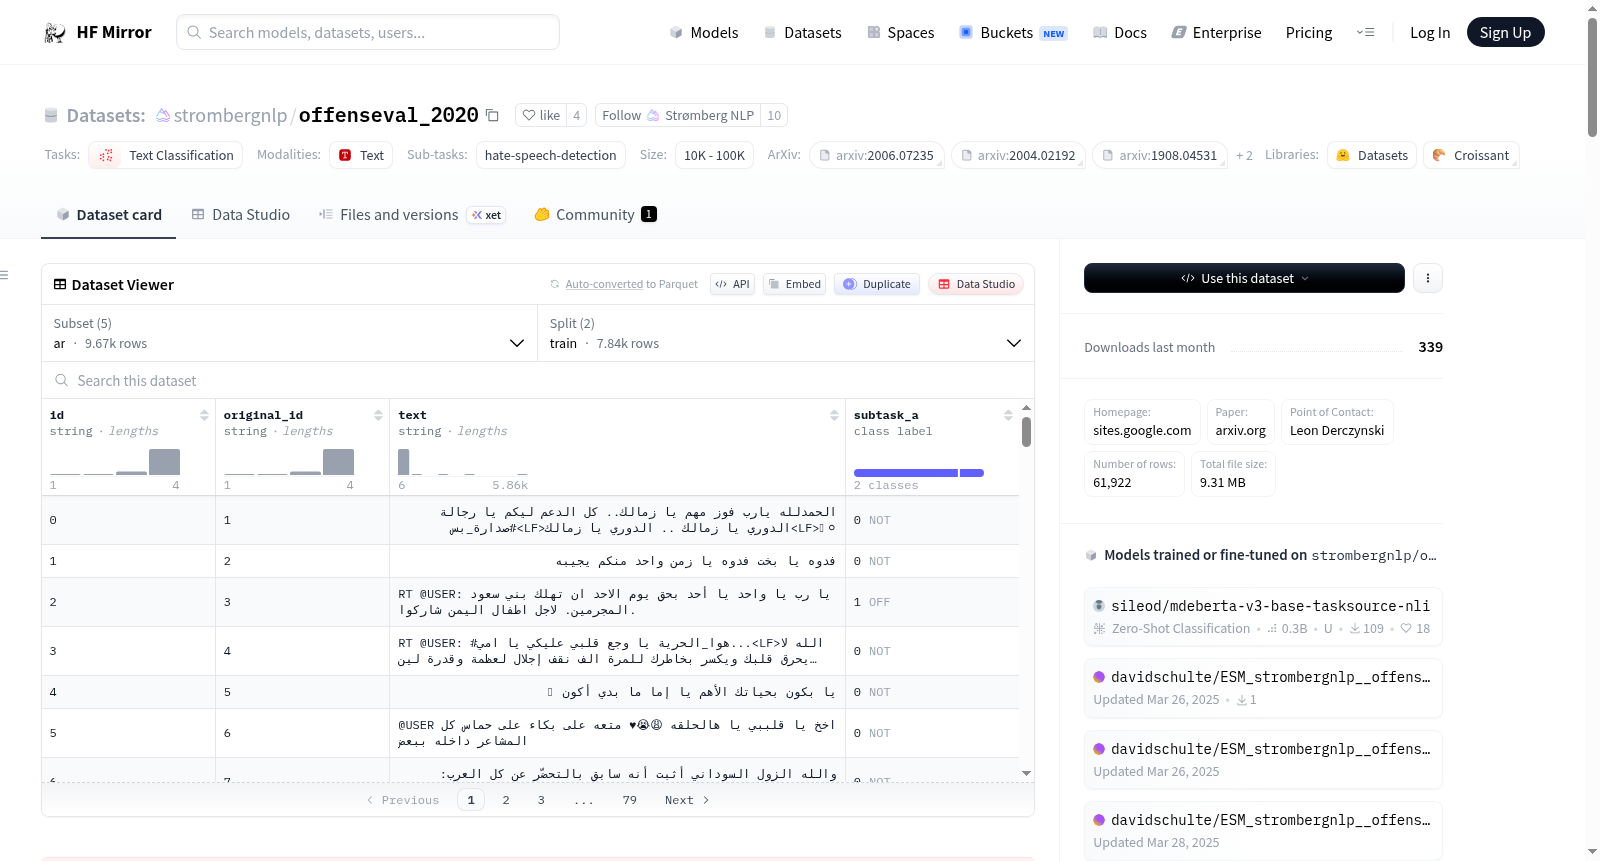
strombergnlp/offenseval_2020
收藏资源简介:
--- annotations_creators: - expert-generated language_creators: - found languages: - ar - da - en - gr - tr licenses: - cc-by-4.0 multilinguality: - multilingual pretty_name: OffensEval 2020 size_categories: - 10K<n<100K source_datasets: - original task_categories: - text-classification task_ids: - hate-speech-detection - text-classification-other-hate-speech-detection extra_gated_prompt: "Warning: this repository contains harmful content (abusive language, hate speech)." paperswithcode_id: - dkhate - ogtd --- # Dataset Card for "offenseval_2020" ## Table of Contents - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [Supported Tasks and Leaderboards](#supported-tasks-and-leaderboards) - [Languages](#languages) - [Dataset Structure](#dataset-structure) - [Data Instances](#data-instances) - [Data Fields](#data-fields) - [Data Splits](#data-splits) - [Dataset Creation](#dataset-creation) - [Curation Rationale](#curation-rationale) - [Source Data](#source-data) - [Annotations](#annotations) - [Personal and Sensitive Information](#personal-and-sensitive-information) - [Considerations for Using the Data](#considerations-for-using-the-data) - [Social Impact of Dataset](#social-impact-of-dataset) - [Discussion of Biases](#discussion-of-biases) - [Other Known Limitations](#other-known-limitations) - [Additional Information](#additional-information) - [Dataset Curators](#dataset-curators) - [Licensing Information](#licensing-information) - [Citation Information](#citation-information) - [Contributions](#contributions) ## Dataset Description - **Homepage:** [https://sites.google.com/site/offensevalsharedtask/results-and-paper-submission](https://sites.google.com/site/offensevalsharedtask/results-and-paper-submission) - **Repository:** - **Paper:** [https://aclanthology.org/2020.semeval-1.188/](https://aclanthology.org/2020.semeval-1.188/), [https://arxiv.org/abs/2006.07235](https://arxiv.org/abs/2006.07235) - **Point of Contact:** [Leon Derczynski](https://github.com/leondz) ### Dataset Summary OffensEval 2020 features a multilingual dataset with five languages. The languages included in OffensEval 2020 are: * Arabic * Danish * English * Greek * Turkish The annotation follows the hierarchical tagset proposed in the Offensive Language Identification Dataset (OLID) and used in OffensEval 2019. In this taxonomy we break down offensive content into the following three sub-tasks taking the type and target of offensive content into account. The following sub-tasks were organized: * Sub-task A - Offensive language identification; * Sub-task B - Automatic categorization of offense types; * Sub-task C - Offense target identification. English training data is omitted so needs to be collected otherwise (see [https://zenodo.org/record/3950379#.XxZ-aFVKipp](https://zenodo.org/record/3950379#.XxZ-aFVKipp)) The source datasets come from: * Arabic [https://arxiv.org/pdf/2004.02192.pdf](https://arxiv.org/pdf/2004.02192.pdf), [https://aclanthology.org/2021.wanlp-1.13/](https://aclanthology.org/2021.wanlp-1.13/) * Danish [https://arxiv.org/pdf/1908.04531.pdf](https://arxiv.org/pdf/1908.04531.pdf), [https://aclanthology.org/2020.lrec-1.430/?ref=https://githubhelp.com](https://aclanthology.org/2020.lrec-1.430/) * English [https://arxiv.org/pdf/2004.14454.pdf](https://arxiv.org/pdf/2004.14454.pdf), [https://aclanthology.org/2021.findings-acl.80.pdf](https://aclanthology.org/2021.findings-acl.80.pdf) * Greek [https://arxiv.org/pdf/2003.07459.pdf](https://arxiv.org/pdf/2003.07459.pdf), [https://aclanthology.org/2020.lrec-1.629/](https://aclanthology.org/2020.lrec-1.629/) * Turkish [https://aclanthology.org/2020.lrec-1.758/](https://aclanthology.org/2020.lrec-1.758/) ### Supported Tasks and Leaderboards * [OffensEval 2020](https://sites.google.com/site/offensevalsharedtask/results-and-paper-submission) ### Languages Five are covered: bcp47 `ar;da;en;gr;tr` ## Dataset Structure There are five named configs, one per language: * `ar` Arabic * `da` Danish * `en` English * `gr` Greek * `tr` Turkish The training data for English is absent - this is 9M tweets that need to be rehydrated on their own. See [https://zenodo.org/record/3950379#.XxZ-aFVKipp](https://zenodo.org/record/3950379#.XxZ-aFVKipp) ### Data Instances An example of 'train' looks as follows. ``` { 'id': '0', 'text': 'PLACEHOLDER TEXT', 'subtask_a': 1, } ``` ### Data Fields - `id`: a `string` feature. - `text`: a `string`. - `subtask_a`: whether or not the instance is offensive; `0: NOT, 1: OFF` ### Data Splits | name |train|test| |---------|----:|---:| |ar|7839|1827| |da|2961|329| |en|0|3887| |gr|8743|1544| |tr|31277|3515| ## Dataset Creation ### Curation Rationale Collecting data for abusive language classification. Different rational for each dataset. ### Source Data #### Initial Data Collection and Normalization Varies per language dataset #### Who are the source language producers? Social media users ### Annotations #### Annotation process Varies per language dataset #### Who are the annotators? Varies per language dataset; native speakers ### Personal and Sensitive Information The data was public at the time of collection. No PII removal has been performed. ## Considerations for Using the Data ### Social Impact of Dataset The data definitely contains abusive language. The data could be used to develop and propagate offensive language against every target group involved, i.e. ableism, racism, sexism, ageism, and so on. ### Discussion of Biases ### Other Known Limitations ## Additional Information ### Dataset Curators The datasets is curated by each sub-part's paper authors. ### Licensing Information This data is available and distributed under Creative Commons attribution license, CC-BY 4.0. ### Citation Information ``` @inproceedings{zampieri-etal-2020-semeval, title = "{S}em{E}val-2020 Task 12: Multilingual Offensive Language Identification in Social Media ({O}ffens{E}val 2020)", author = {Zampieri, Marcos and Nakov, Preslav and Rosenthal, Sara and Atanasova, Pepa and Karadzhov, Georgi and Mubarak, Hamdy and Derczynski, Leon and Pitenis, Zeses and {\c{C}}{\"o}ltekin, {\c{C}}a{\u{g}}r{\i}}, booktitle = "Proceedings of the Fourteenth Workshop on Semantic Evaluation", month = dec, year = "2020", address = "Barcelona (online)", publisher = "International Committee for Computational Linguistics", url = "https://aclanthology.org/2020.semeval-1.188", doi = "10.18653/v1/2020.semeval-1.188", pages = "1425--1447", abstract = "We present the results and the main findings of SemEval-2020 Task 12 on Multilingual Offensive Language Identification in Social Media (OffensEval-2020). The task included three subtasks corresponding to the hierarchical taxonomy of the OLID schema from OffensEval-2019, and it was offered in five languages: Arabic, Danish, English, Greek, and Turkish. OffensEval-2020 was one of the most popular tasks at SemEval-2020, attracting a large number of participants across all subtasks and languages: a total of 528 teams signed up to participate in the task, 145 teams submitted official runs on the test data, and 70 teams submitted system description papers.", } ``` ### Contributions Author-added dataset [@leondz](https://github.com/leondz)
数据集概述
数据集名称
- Pretty Name: OffensEval 2020
数据集语言
- Languages: Arabic, Danish, English, Greek, Turkish
数据集许可证
- Licenses: cc-by-4.0
数据集大小
- Size Categories: 10K<n<100K
数据集多语言性
- Multilinguality: multilingual
数据集任务
- Task Categories: text-classification
- Task IDs: hate-speech-detection, text-classification-other-hate-speech-detection
数据集结构
- Data Instances:
- id: string
- text: string
- subtask_a: 0: NOT, 1: OFF
数据集分割
- Data Splits:
- ar: train=7839, test=1827
- da: train=2961, test=329
- en: train=0, test=3887
- gr: train=8743, test=1544
- tr: train=31277, test=3515
数据集创建
- Source Data:
- Arabic: https://arxiv.org/pdf/2004.02192.pdf, https://aclanthology.org/2021.wanlp-1.13/
- Danish: https://arxiv.org/pdf/1908.04531.pdf, https://aclanthology.org/2020.lrec-1.430/
- English: https://arxiv.org/pdf/2004.14454.pdf, https://aclanthology.org/2021.findings-acl.80.pdf
- Greek: https://arxiv.org/pdf/2003.07459.pdf, https://aclanthology.org/2020.lrec-1.629/
- Turkish: https://aclanthology.org/2020.lrec-1.758/
数据集注意事项
- Warning: Contains harmful content (abusive language, hate speech).