hannxu/hc_var
收藏资源简介:
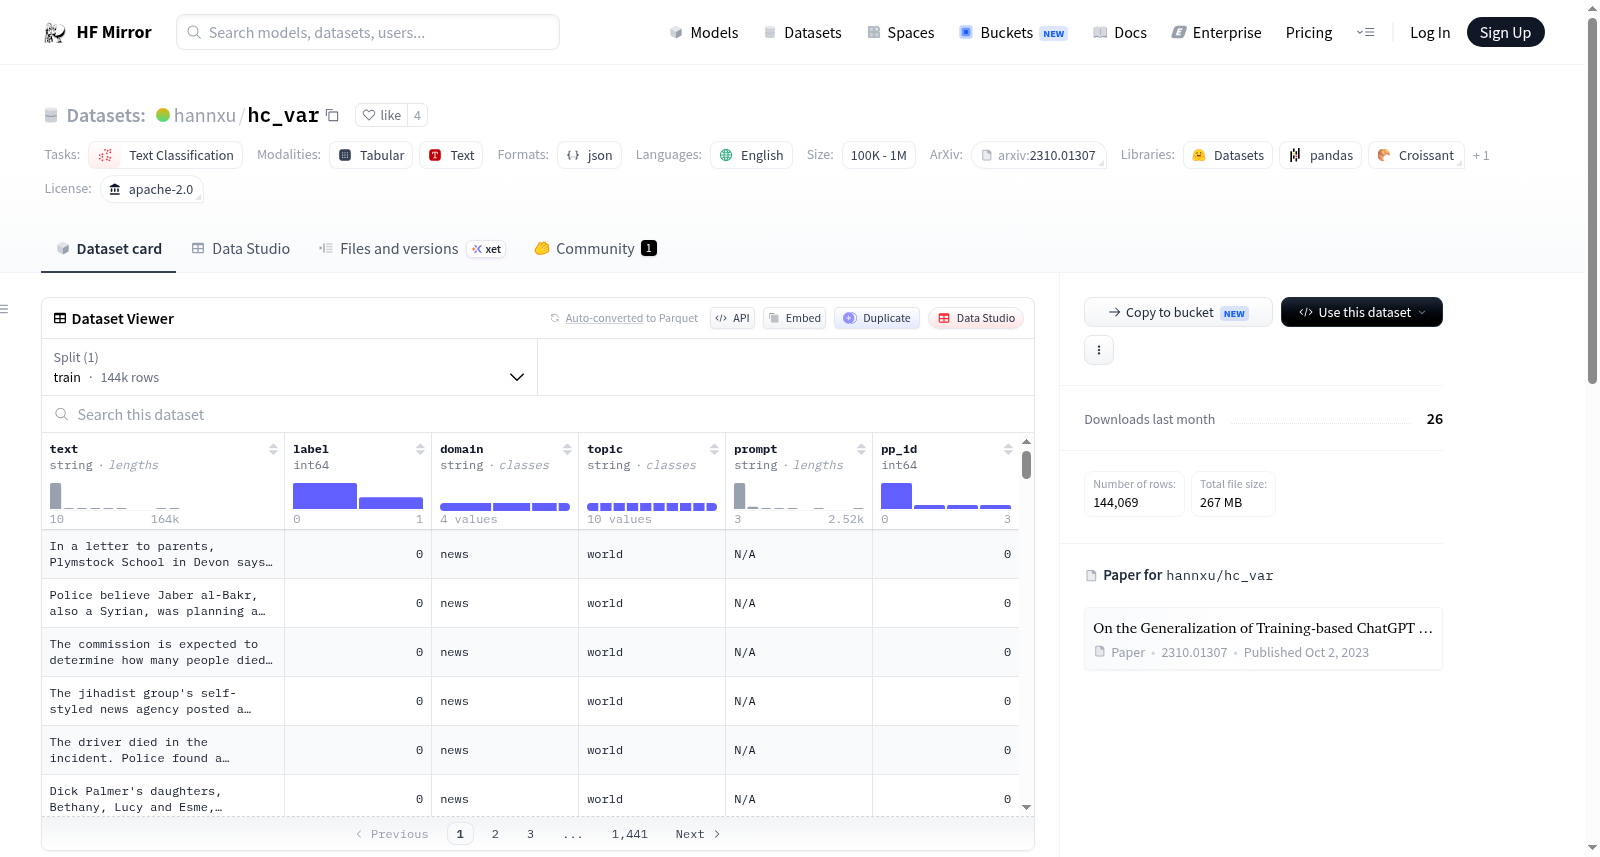
--- license: apache-2.0 task_categories: - text-classification language: - en size_categories: - 100M<n<1B --- # Dataset Card for HC-Var (Human and ChatGPT Texts with Variety) This is a collection of human texts and ChatGPT (GPT3.5-Turbo) generated texts, to faciliate studies such as generated texts detection. It includes the texts which are generated / human written to accomplish various language tasks with various approaches. The included language tasks and topics are summarized below. Note: For each language task, this dataset considers 3 different prompts to inquire ChatGPT outputs. The example code to train binary classification models is in [this website](https://github.com/hannxu123/hc_var). A technical report on some representative detection methods can be find in [this paper](https://arxiv.org/abs/2310.01307). This dataset is collected by Han Xu from Michigan State University. Potential issues and suggestions are welcomed to be dicussed in the community panel or emails to xuhan1@msu.edu. ## Key variables in the dataset: **text**: The text body (including either human or ChatGPT texts.)\ **domain**: The language tasks included in this dataset: News, Review, (Essay) Writing, QA\ **topic**: The topic in each task.\ **prompt**: The prompt used to obtain ChatGPT outputs. "N/A" for human texts.\ **pp_id**: Each task has 3 prompts to inquire ChatGPT outputs. The "pp_id" denotes the index of prompt. "0" for human texts. "1-3" for ChatGPT texts.\ **label**: "0" for human texts. "1" for ChatGPT texts. ## To cite this dataset ``` @misc{xu2023generalization, title={On the Generalization of Training-based ChatGPT Detection Methods}, author={Han Xu and Jie Ren and Pengfei He and Shenglai Zeng and Yingqian Cui and Amy Liu and Hui Liu and Jiliang Tang}, year={2023}, eprint={2310.01307}, archivePrefix={arXiv}, primaryClass={cs.CL} } ```
--- 许可证:Apache-2.0 任务类别: - 文本分类(text-classification) 语言: - 英语(en) 规模区间: - 100M < n < 1B --- # 数据集卡片:HC-Var(人类与ChatGPT(GPT3.5-Turbo)生成文本多样化数据集) 本数据集收录人类撰写文本与ChatGPT(GPT3.5-Turbo)生成的文本,旨在助力生成文本检测等相关研究。所收录文本均通过多种方法完成各类语言任务,涵盖人类撰写内容与AI生成内容两类。 数据集涵盖的语言任务与主题汇总如下。注意:针对每一类语言任务,本数据集均采用3种不同提示词(prompt)生成ChatGPT输出。 用于训练二分类模型的示例代码可参见[该链接](https://github.com/hannxu123/hc_var)。 关于部分代表性检测方法的技术报告可参阅[该论文](https://arxiv.org/abs/2310.01307)。 本数据集由密歇根州立大学的韩旭收集整理。若您发现数据集存在潜在问题或有改进建议,欢迎在社区板块中讨论,或发送邮件至xuhan1@msu.edu进行沟通。 ## 数据集核心变量 **text**:文本主体(包含人类撰写文本与ChatGPT生成文本) **domain**:数据集涵盖的语言任务类型:新闻、评论、(议论文)写作、问答 **topic**:对应任务下的具体主题 **prompt**:用于生成ChatGPT输出的提示词。人类撰写文本对应的此项为"N/A" **pp_id**:针对每类语言任务,数据集采用3种提示词生成ChatGPT输出。pp_id用于标识提示词的索引:人类撰写文本对应pp_id为0,ChatGPT生成文本对应pp_id为1至3 **label**:文本标签,0代表人类撰写文本,1代表ChatGPT生成文本 ## 数据集引用方式 @misc{xu2023generalization, title={On the Generalization of Training-based ChatGPT Detection Methods}, author={Han Xu and Jie Ren and Pengfei He and Shenglai Zeng and Yingqian Cui and Amy Liu and Hui Liu and Jiliang Tang}, year={2023}, eprint={2310.01307}, archivePrefix={arXiv}, primaryClass={cs.CL} }
数据集卡片 for HC-Var (Human and ChatGPT Texts with Variety)
概述
HC-Var 数据集是一个包含人类文本和 ChatGPT (GPT3.5-Turbo) 生成文本的集合,旨在促进生成文本检测等研究。该数据集包括用于完成各种语言任务的生成文本和人类书写文本,涵盖多种语言任务和主题。
语言任务和主题
数据集包含以下语言任务和主题:
- 任务: 新闻、评论、(论文)写作、问答
- 主题: 每个任务的具体主题
关键变量
- text: 文本内容(包括人类或 ChatGPT 文本)
- domain: 数据集包含的语言任务:新闻、评论、(论文)写作、问答
- topic: 每个任务中的主题
- prompt: 用于获取 ChatGPT 输出的提示。人类文本为 "N/A"
- pp_id: 每个任务有 3 个提示用于获取 ChatGPT 输出。"pp_id" 表示提示的索引。人类文本为 "0",ChatGPT 文本为 "1-3"
- label: 人类文本为 "0",ChatGPT 文本为 "1"
引用
@misc{xu2023generalization, title={On the Generalization of Training-based ChatGPT Detection Methods}, author={Han Xu and Jie Ren and Pengfei He and Shenglai Zeng and Yingqian Cui and Amy Liu and Hui Liu and Jiliang Tang}, year={2023}, eprint={2310.01307}, archivePrefix={arXiv}, primaryClass={cs.CL} }