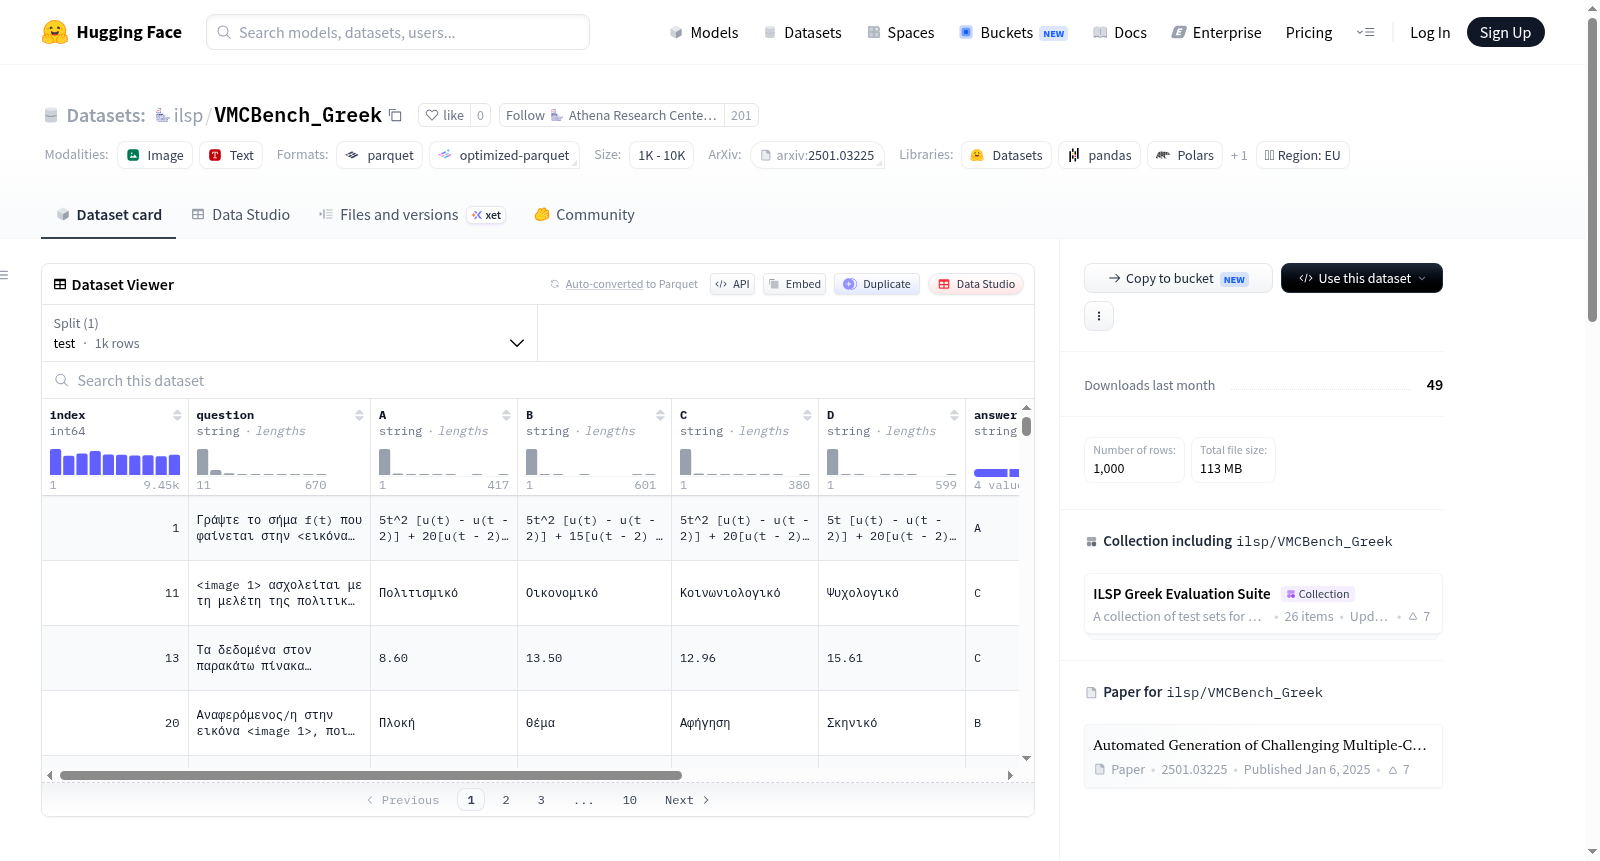
ilsp/VMCBench_Greek
收藏资源简介:
该数据集是VMCBench的希腊语翻译版本,旨在作为评估支持希腊语的视觉语言模型的基准。它保留了原始VMCBench数据集的结构和列名,但问题和答案选项已被翻译成希腊语。每个示例包含一张图像、一个问题、四个答案选项、正确答案标签以及示例的来源/类别。数据集用于评估希腊语环境下的多模态多选择题回答能力,典型评估提示要求模型检查图像、阅读希腊语问题和选项,并仅输出四个标签(A、B、C或D)中的一个。
This dataset is a Greek translation of VMCBench, a visual multiple-choice benchmark for evaluating Vision-Language Models (VLMs). The goal of this version is to make VMCBench usable as an evaluation benchmark for Greek-capable VLMs. The dataset keeps the same structure and column names as the original VMCBench dataset, with the question and answer options translated into Greek. Each example contains an image, a question, four answer options, the correct answer label, and the source/category of the example. It is intended for evaluating Vision-Language Models on multimodal multiple-choice question answering in Greek, with typical evaluation prompting the model to inspect the image, read the Greek question and options, and output only one of the four labels: A, B, C, or D.