goodwiki_finetune_corpus_1024-2040_tokens
收藏资源简介:
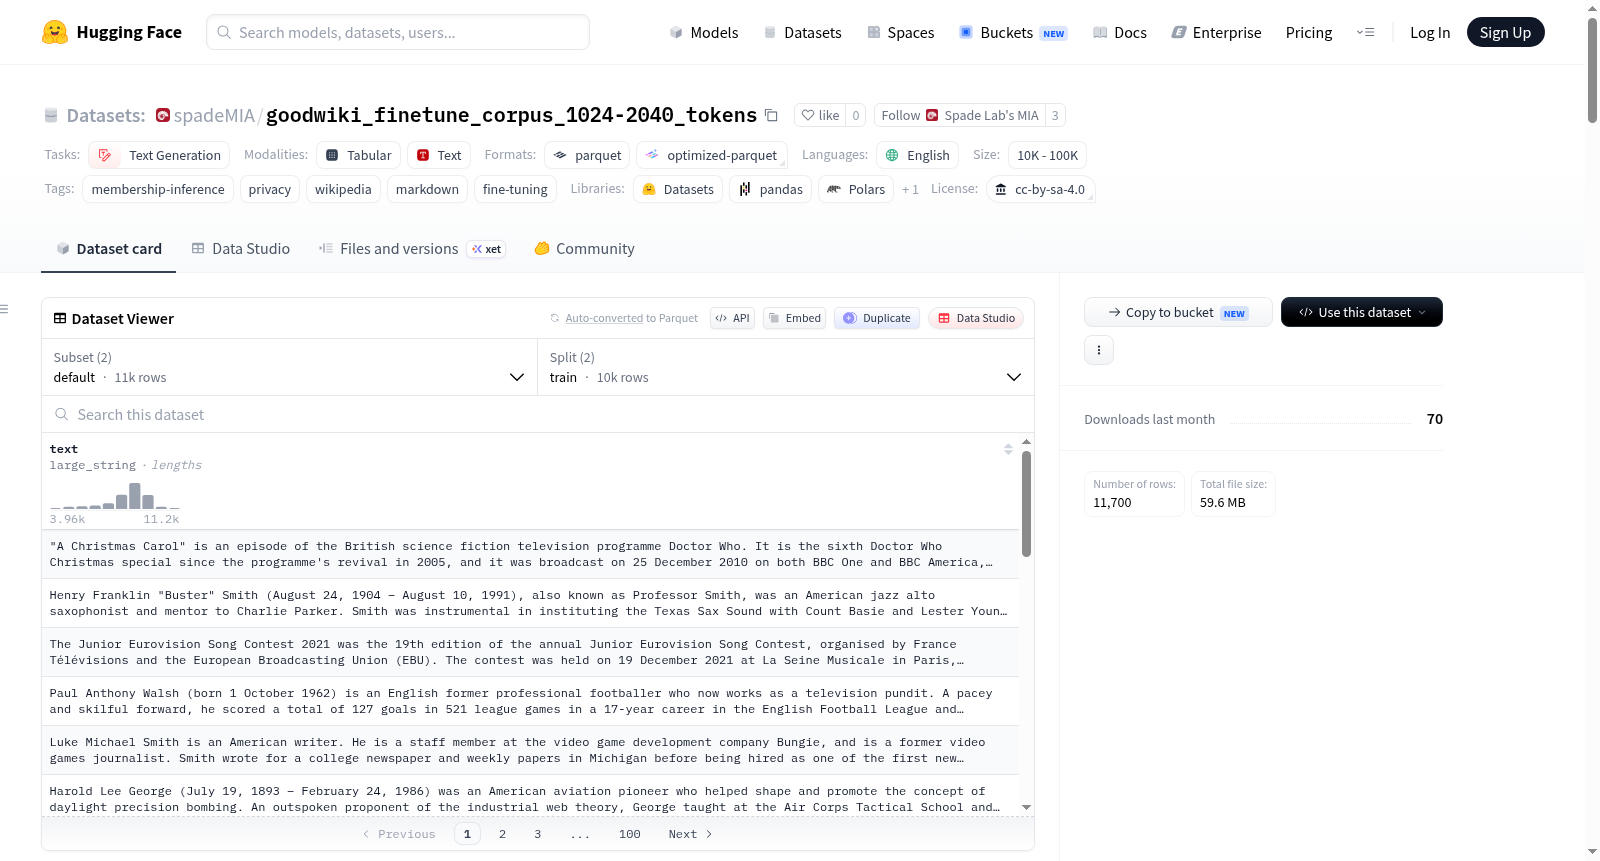
该数据集名为 GoodWiki 1024-2040,是一个用于成员推断攻击(MIA)实验的高质量细调语料库,专门针对在细调语言模型上评估隐私风险而设计。数据来源于英语维基百科的好/特色文章,从 euirim/goodwiki 数据集中提取,经过精心处理以确保每个样本的长度在 1024 到 2040 个令牌之间(使用 EleutherAI/pythia-2.8b 分词器,且仅包含一个 EOS 令牌)。数据集包含两个划分:训练集(train)有 10,000 个样本,作为成员;测试集(test)有 1,000 个样本,作为非成员。两者均来自同一篇文章池,通过随机种子 42 的排列选出,确保分布一致。每个样本仅包含一个字段 'text',存储为字符串类型,内容是文章的 Markdown 格式,以完整段落边界截断,保留了原始文章中的标题、链接、表格、列表和引用等结构。构建过程包括最小归一化(仅处理换行符和首尾空白)、段落截断(从末尾移除整段块,从不拆分段落)、去重和过滤(丢弃低于 1024 令牌或无法有效截断的文章)。最终 42,266 篇文章符合条件,其中 10,000 篇被选为训练集,1,000 篇为测试集,其余 31,266 篇未使用。该数据集专为成员推断攻击实验设计,要求测试集完全不可见,不得用于任何形式的模型训练或超参数调整。许可协议为 CC BY-SA 4.0。
The dataset named GoodWiki 1024-2040 is a high-quality fine-tuning corpus for membership inference attack (MIA) experiments, specifically designed to evaluate privacy risks on fine-tuned language models. The data is sourced from English Wikipedias good/featured articles, extracted from the euirim/goodwiki dataset, and carefully processed to ensure each sample has a length between 1024 and 2040 tokens (using the EleutherAI/pythia-2.8b tokenizer, with only one EOS token). The dataset contains two splits: training set (train) with 10,000 samples (members) and test set (test) with 1,000 samples (non-members). Both are drawn from the same article pool selected by a permutation with random seed 42, ensuring consistent distribution. Each sample contains only one field text stored as a string, in Markdown format, truncated at full paragraph boundaries, preserving structures such as titles, links, tables, lists, and citations from the original articles. The construction process includes minimal normalization (only handling line breaks and leading/trailing whitespace), paragraph truncation (removing whole blocks from the end, never splitting paragraphs), deduplication, and filtering (discarding articles below 1024 tokens or those that cannot be effectively truncated). Ultimately, 42,266 articles meet the criteria, of which 10,000 are selected for the training set, 1,000 for the test set, and the remaining 31,266 are unused. The dataset is specifically designed for membership inference attack experiments, requiring the test set to be completely invisible and not to be used for any form of model training or hyperparameter tuning. The license is CC BY-SA 4.0.
GoodWiki 1024-2040 段落截断 MIA 微调语料库
数据集概述
本数据集是一个用于成员推理攻击(Membership Inference Attack, MIA)实验的英文 Wikipedia 优质/精选文章段落截断语料库,基于 euirim/goodwiki 构建。数据集由 Koç 大学 SPADE 实验室的研究项目创建。
数据集用途
这是一个成员划分数据集,而非普通的训练/测试划分:
train(10,000 行):微调群体,即成员(members)test(1,000 行):留出集,即非成员(non-members)- 仅在
train上进行微调,test不得用于梯度更新、早停、检查点选择或攻击超参数调优,必须保持对目标模型不可见,仅用于最终成员推理实验
数据格式与字段
train 和 test 划分
| 字段 | 类型 | 描述 |
|---|---|---|
text |
string | 文章 Markdown 格式,为最小化规范化源文章的精确字符前缀,止于完整段落块边界 |
evaluation 划分(额外提供)
| 字段 | 类型 | 描述 |
|---|---|---|
text |
string | 与对应 train/test 行的 text 完全一致 |
label |
int64 | 1 = 成员(来自 train),0 = 非成员(来自 test) |
source_split |
string | "train" 或 "test",标明来源划分 |
source_index |
int64 | 在来源划分中的精确索引,便于追溯 |
规模统计
| 阶段 | 行数 |
|---|---|
| 源文章总数 | 44,754 |
| 低于 1,024 token 被剔除 | 2,459 |
| 无有效完整块前缀被剔除 | 29 |
| 合格文章(去重后) | 42,266 |
选入 train(成员) |
10,000 |
选入 test(非成员) |
1,000 |
| 未使用合格文章 | 31,266 |
evaluation 划分:固定 700 行,350 行来自 train(标签 1),350 行来自 test(标签 0),使用固定种子无放回抽样,完全可复现。
Token 约束
- 使用
EleutherAI/pythia-2.8b分词器,add_special_tokens=False - 存储文本 token 数范围:1,024 ≤ 存储文本 tokens ≤ 2,039
- 训练时序列构造追加恰好 1 个 EOS token(id 0),总长度 ≤ 2,040
构建方法
- 来源:
euirim/goodwiki的train划分,markdown列 - 最小化规范化:仅处理
strip(),不做 Markdown 转换、HTML 清洗、小写化或 Unicode 规范化 - 段落边界截断:超过 2,039 token 的文章仅从末尾移除完整段落块,从不从开头或中间移除,不拆分任何块
- 悬空标题规则:存储文本不以无正文的独立 ATX 标题结尾
- 排除规则:低于 1,024 token 的文章及无有效完整块前缀的文章被剔除
- 精确去重:最终文本精确去重(发现 0 个重复),使用 seed-42 NumPy 排列选取 10,000 训练行 + 1,000 测试行
验证结果
- 架构精确为
["text"];行数精确为 10,000/1,000 - 每行重新分词后均在 1,024–2,039 token 范围内(+1 EOS ≤ 2,040)
- 无空行、无外部空白、无悬空标题结尾
- 两个划分内零重复,
train/test零重叠 - 内容哈希(SHA-256):
train:9ee9a293c58451cc1ffa05ef630e3ae0da26e4c71a0fbf6ad9541494e9fc3adctest:68f88f610108b710b185751468a787807f4f3647eddd0bfecb2bf0563685fcc4
许可与归属
- 文章文本源自英文 Wikipedia,采用 CC BY-SA 4.0 许可
- 上游
euirim/goodwiki对其数据集打包和代码声明 MIT 许可 - 本衍生数据集仅保留文章文本前缀切片,不存储标题、页面 ID 或修订 ID
相关语料库说明
本数据集取代了 mia-llm/goodwiki_finetune_corpus(未截断文章记录,中位数约 3,445 Pythia tokens,约 79% 超过 2,048 token 上下文窗口)及其句子截断的 2,047-token 衍生版本。检查点只能针对其训练所用确切语料库进行解释——必须在本语料库上训练新的目标模型,切勿跨不同 GoodWiki 语料库训练的检查点比较攻击结果。