
Time-Aware Dataset
收藏资源简介:
Time-Aware Dataset是由捷克技术大学的研究人员创建的一个专门用于测试大型语言模型(LLMs)时间感知能力的数据集。该数据集包含2022年和2023年的1150个重要事件,涵盖政治、商业、科学、艺术和犯罪等多个领域。数据来源于全球各大新闻机构、学术期刊和政府出版物,确保了数据的准确性和可信度。数据集的创建过程包括从多个独立来源交叉验证事件,确保每个事件的时间和类别标签的准确性。该数据集旨在评估和提升LLMs在处理时间敏感事实方面的能力,特别是在虚拟助手、自动事实核查和时间相关问答系统中的应用。
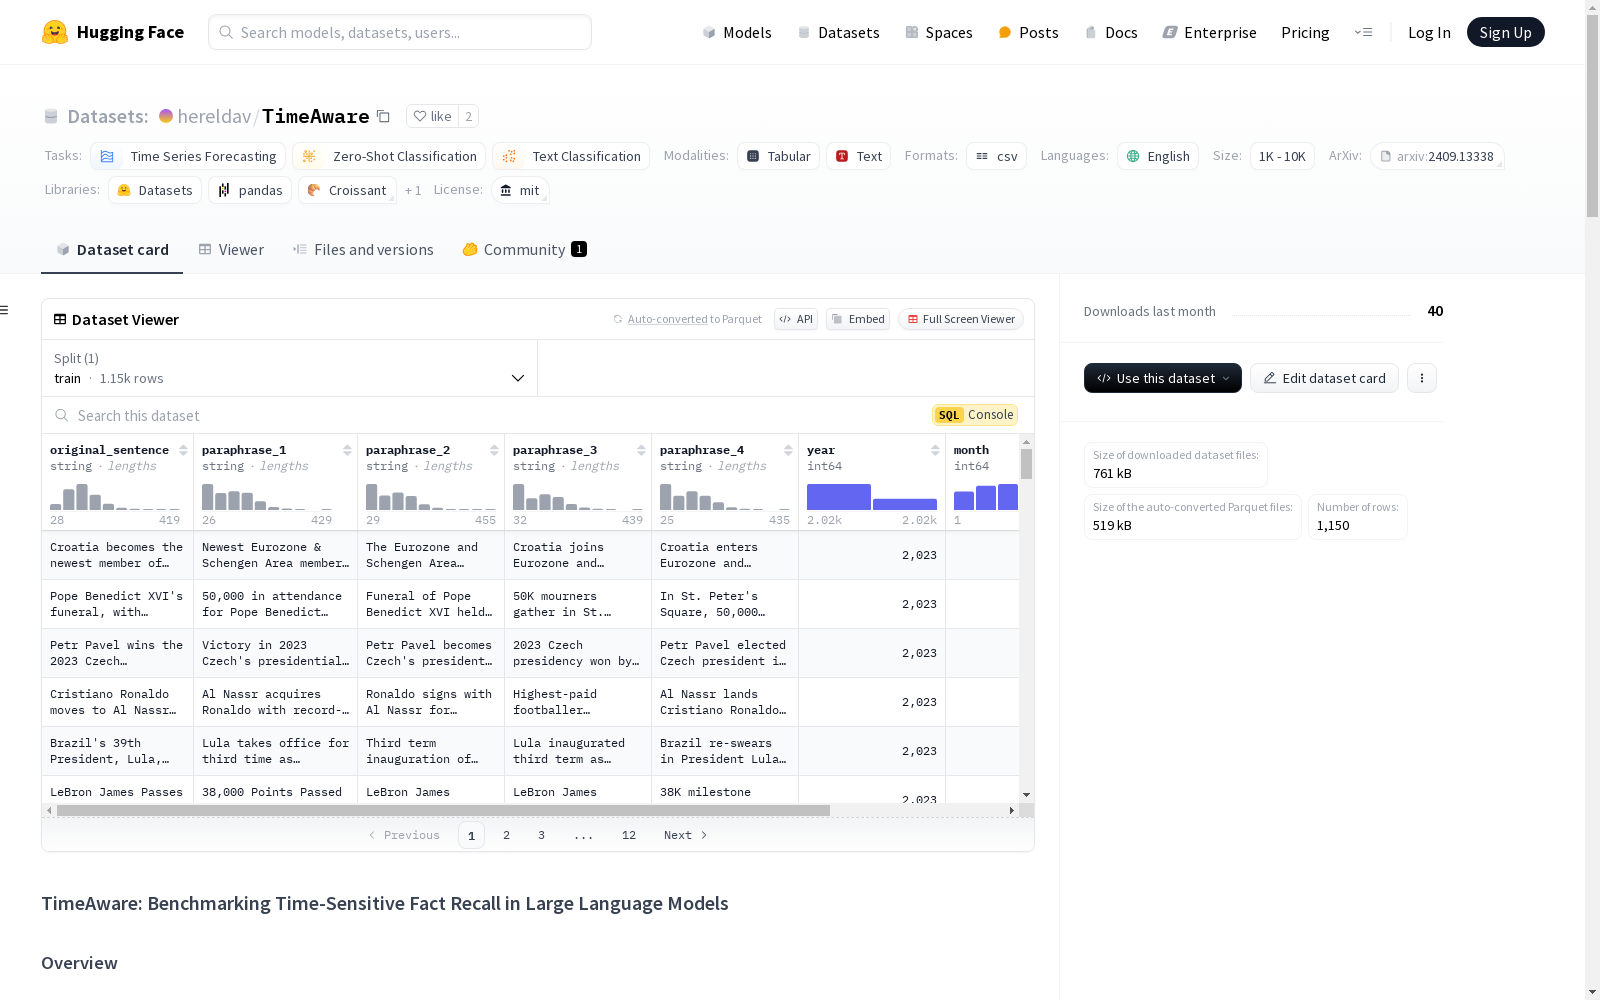
The Time-Aware Dataset is a benchmark dataset developed by researchers from the Czech Technical University, specifically designed to evaluate the temporal awareness capabilities of Large Language Models (LLMs). This dataset includes 1,150 significant events spanning 2022 and 2023, covering multiple domains such as politics, business, science, art, and crime. The data is sourced from major global news outlets, academic journals, and government publications, thus ensuring the accuracy and credibility of the dataset. The dataset creation process involves cross-validating events across multiple independent sources to guarantee the accuracy of both the temporal information and category labels for each event. This dataset aims to assess and enhance the capabilities of LLMs in handling time-sensitive factual information, with particular applications in virtual assistants, automated fact-checking, and time-related question answering systems.
- 1Time Awareness in Large Language Models: Benchmarking Fact Recall Across Time捷克技术大学 · 2024年


