ORIDa
收藏资源简介:
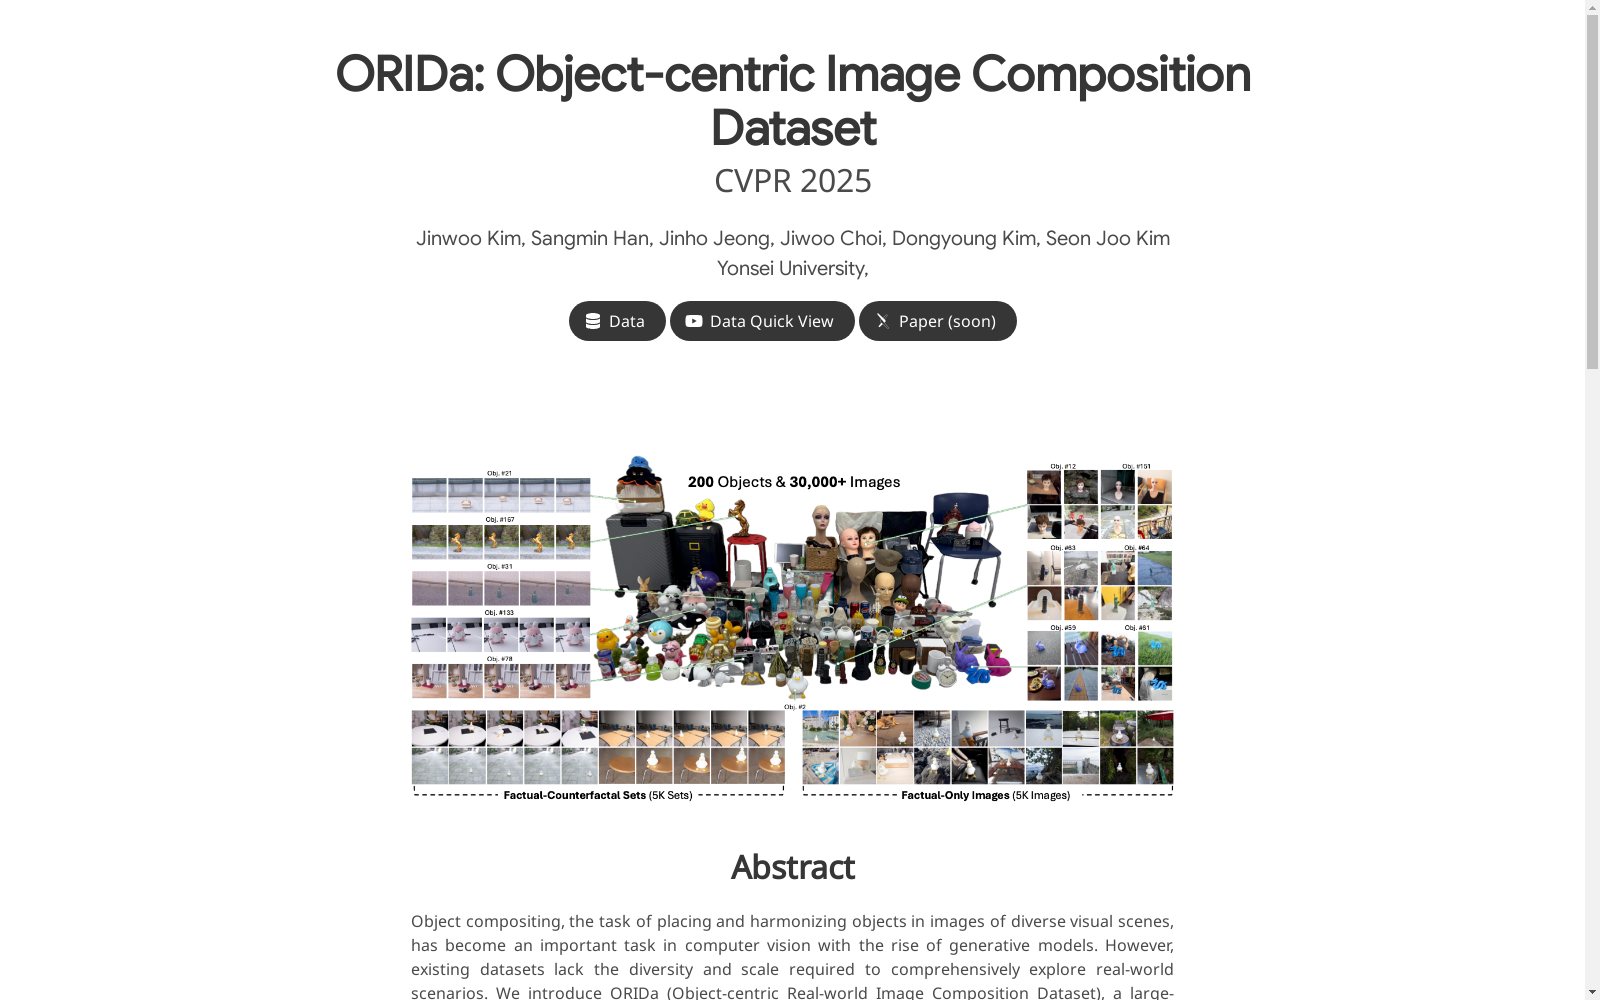
ORIDa是一个大规模的、真实拍摄的数据集,包含超过30,000张图像,涉及200个独特的物体,每个物体在50个不同的场景中展示。数据集包括事实-反事实集和仅事实场景两种类型的数据。事实-反事实集由四张事实图像和一张反事实图像组成,每张事实图像展示了物体在场景中的不同位置,反事实图像则展示了没有物体的场景。仅事实场景包括一张包含特定场景中的物体的图像。ORIDa是第一个公开可用的具有其规模和复杂性的真实世界图像合成数据集。广泛的分析和实验突出了ORIDa作为推进物体合成研究的重要资源。
ORIDa is a large-scale real-world captured dataset containing over 30,000 images, encompassing 200 distinct objects, with each object featured in 50 different scenes. The dataset comprises two data modalities: fact-counterfactual sets and fact-only scenarios. Fact-counterfactual sets are composed of four fact images and one counterfactual image: each fact image displays the object in a unique position within the scene, while the counterfactual image depicts the scene devoid of the object. Fact-only scenarios contain a single image that includes the object in a specific scene. ORIDa is the first publicly available real-world image synthesis dataset with its scale and complexity. Extensive analyses and experiments demonstrate that ORIDa serves as a pivotal resource for advancing research on object synthesis.
ORIDa: Object-centric Image Composition Dataset
基本信息
- 发表会议: CVPR 2025
- 作者: Jinwoo Kim, Sangmin Han, Jinho Jeong, Jiwoo Choi, Dongyoung Kim, Seon Joo Kim
- 机构: Yonsei University
数据集概述
- 名称: ORIDa (Object-centric Real-world Image Composition Dataset)
- 规模: 超过30,000张图像
- 对象数量: 200个独特对象
- 特点: 每个对象在不同位置和场景中呈现
数据类型
-
Factual-Counterfactual (F-CF) Sets
- 包含4张事实图像(对象在不同位置)和1张反事实图像(无对象的背景)
- 每个场景共5张图像
-
Factual-Only (F-Only) Images
- 单张图像,包含特定上下文中的对象
- 无对应的背景图像
数据集价值
- 首个公开的大规模、复杂度的真实世界图像合成数据集
- 为对象合成研究提供丰富资源
数据集示例
- F-CF Sets: 左侧展示一组F-CF图像(1张背景 + 4张不同位置的对象图像)
- F-Only Images: 右侧展示F-Only图像(对象在不同场景中的单张图像)
数据集统计
- 按对象统计: 展示事实-only和事实-反事实集合中每个对象的图像数量
- 按属性统计: 展示基于关键属性的对象百分比分布(颜色数量、透明度、反射率、粗糙度、语义类别)