Publishing/unclutching-corpus-v2
收藏资源简介:
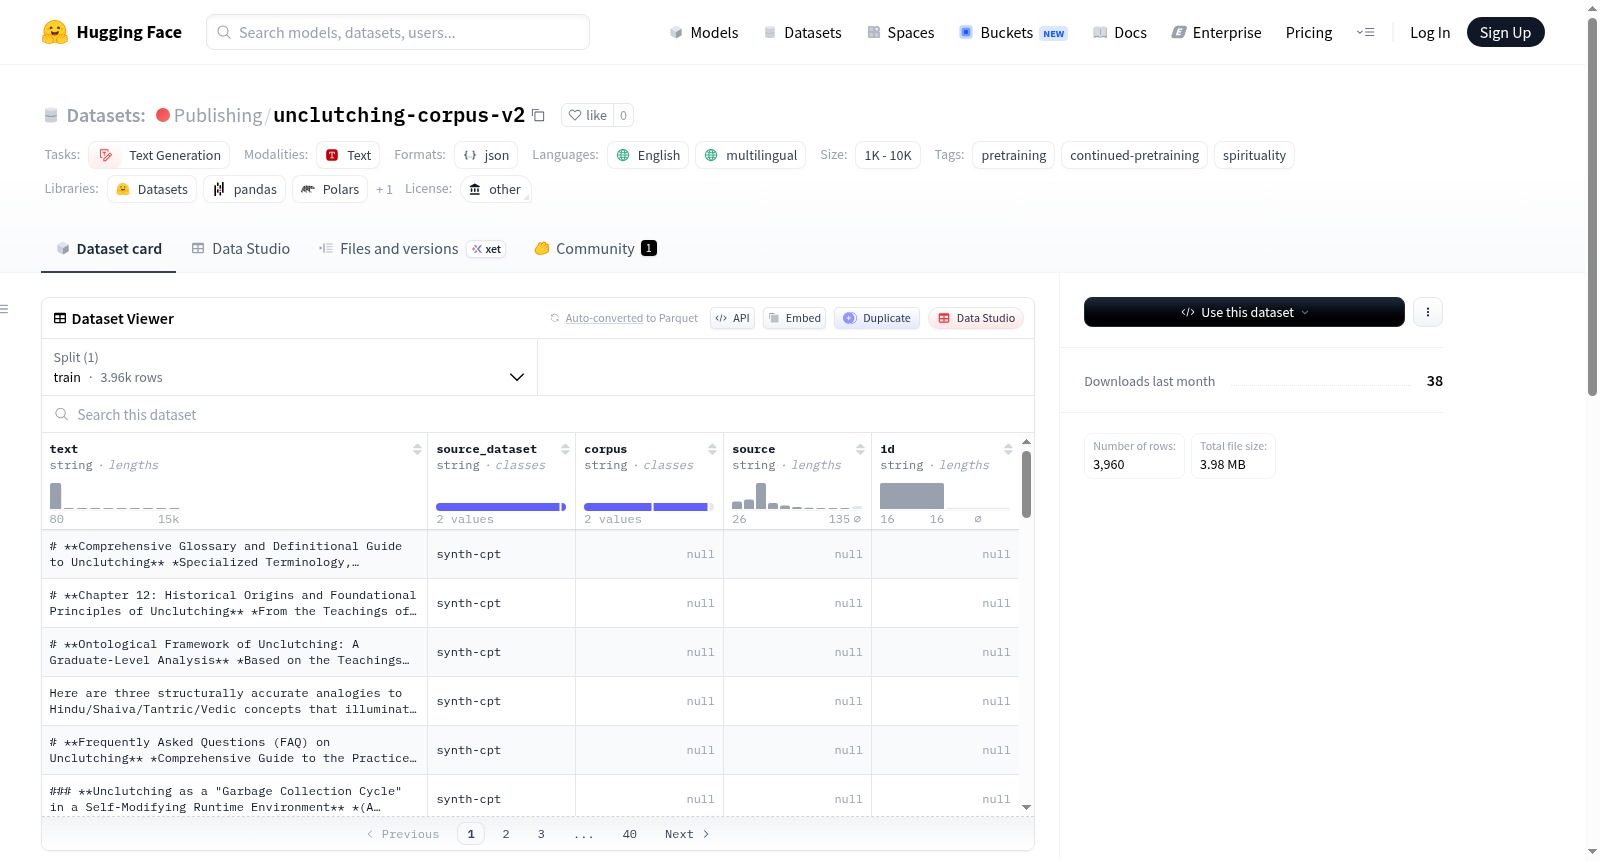
这是一个关于放手(Unclutching)主题的混合继续预训练语料库v2版本,结合了合成的说明性段落和经过去重处理的Kailasa wiki书籍语料库摘录。数据集包含3,960行数据,其中194行来自合成来源(synth-cpt),3,766行来自Kailasa wiki。数据格式为JSONL,每行包含text和source_dataset字段,wiki来源的数据还包含额外的元数据。合成数据是使用synth-cpt-cli生成的英文长段落,而wiki数据是多语言的书籍摘录(原字段名为excerpt,映射为text)。
Mixed continued-pretraining corpus on Unclutching combining synthesized expository passages with deduplicated excerpts from the Kailasa wiki book corpus. The dataset contains 3,960 rows, with 194 from synthetic source (synth-cpt) and 3,766 from Kailasa wiki. The format is JSONL, each row has text and source_dataset; wiki-sourced rows also carry additional metadata. The synthetic data consists of synthesized long-form English passages from synth-cpt-cli, while the wiki data are multilingual book excerpts (originally named excerpt, mapped to text).