ccdv/patent-classification
收藏资源简介:
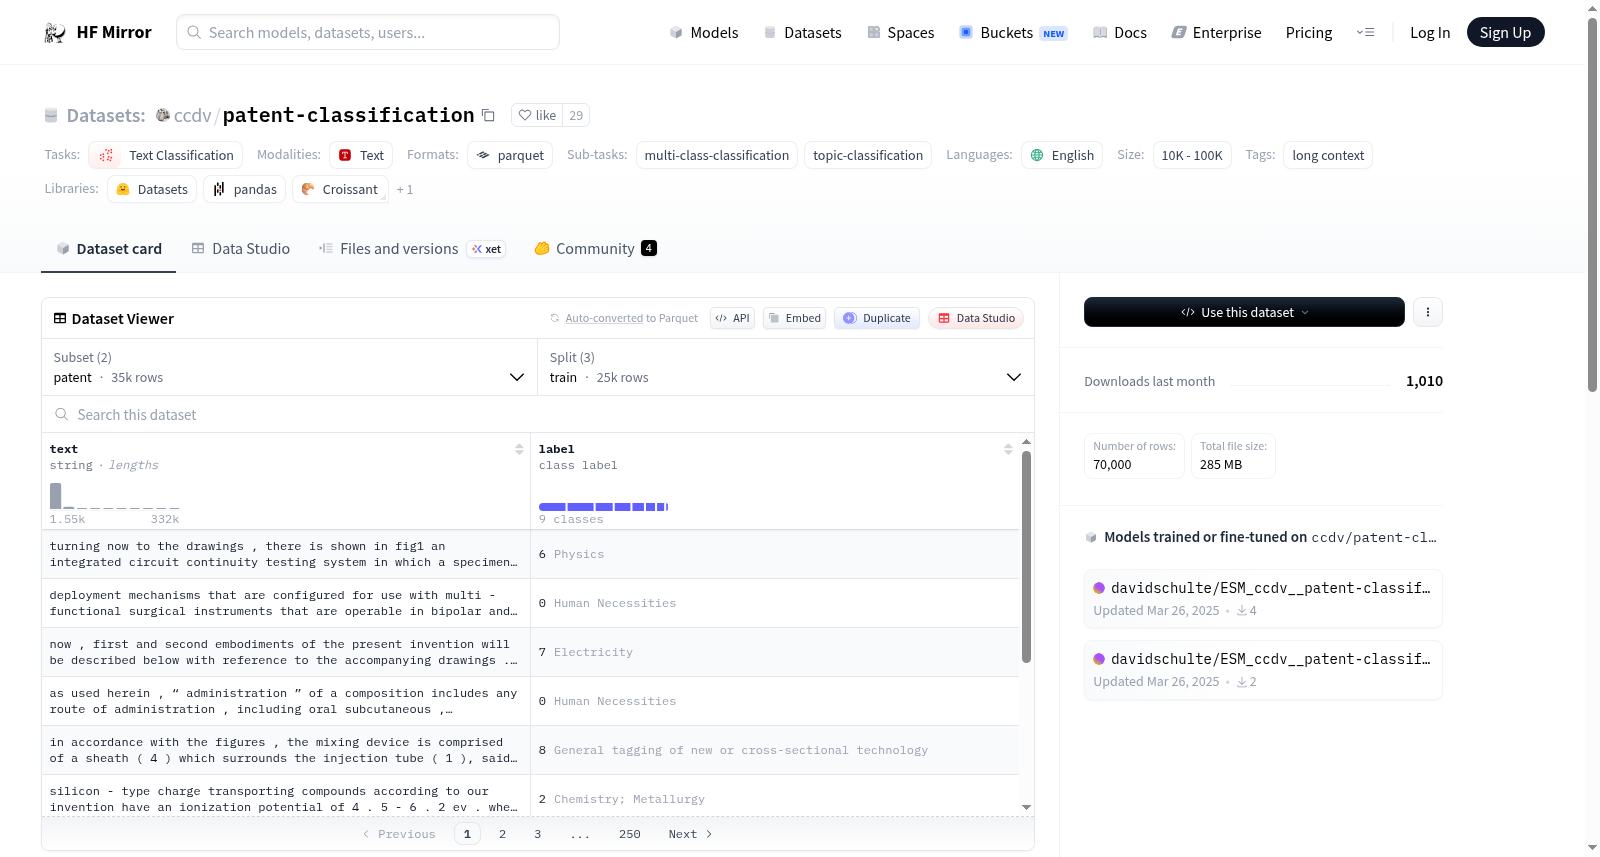
--- language: en task_categories: - text-classification tags: - long context task_ids: - multi-class-classification - topic-classification size_categories: 10K<n<100K --- **Patent Classification: a classification of Patents and abstracts (9 classes).** This dataset is intended for long context classification (non abstract documents are longer that 512 tokens). \ Data are sampled from "BIGPATENT: A Large-Scale Dataset for Abstractive and Coherent Summarization." by Eva Sharma, Chen Li and Lu Wang * See: https://aclanthology.org/P19-1212.pdf * See: https://evasharma.github.io/bigpatent/ It contains 9 unbalanced classes, 35k Patents and abstracts divided into 3 splits: train (25k), val (5k) and test (5k). **Note that documents are uncased and space separated (by authors)** Compatible with [run_glue.py](https://github.com/huggingface/transformers/tree/master/examples/pytorch/text-classification) script: ``` export MODEL_NAME=roberta-base export MAX_SEQ_LENGTH=512 python run_glue.py \ --model_name_or_path $MODEL_NAME \ --dataset_name ccdv/patent-classification \ --do_train \ --do_eval \ --max_seq_length $MAX_SEQ_LENGTH \ --per_device_train_batch_size 8 \ --gradient_accumulation_steps 4 \ --learning_rate 2e-5 \ --num_train_epochs 1 \ --max_eval_samples 500 \ --output_dir tmp/patent ```
language: 英语 task_categories: - 文本分类 tags: - 长上下文(long context) task_ids: - 多类别分类(multi-class-classification) - 主题分类(topic-classification) size_categories: 10K<n<100K **专利分类:专利与摘要的九类别分类任务** 本数据集旨在支持长上下文分类任务(非摘要类文档长度超过512个词元(Token))。数据采样自Eva Sharma、Chen Li与Lu Wang发表的论文《BIGPATENT: A Large-Scale Dataset for Abstractive and Coherent Summarization》,相关参考链接如下: * 参见:https://aclanthology.org/P19-1212.pdf * 参见:https://evasharma.github.io/bigpatent/ 该数据集包含9个非均衡类别,总计35000条专利及摘要数据,被划分为训练集(25000条)、验证集(5000条)与测试集(5000条)三个子集。 **请注意,文档均采用小写格式且以空格分隔(由原数据集作者设定)** 本数据集兼容[run_glue.py](https://github.com/huggingface/transformers/tree/master/examples/pytorch/text-classification)脚本,示例运行代码如下: export MODEL_NAME=roberta-base export MAX_SEQ_LENGTH=512 python run_glue.py --model_name_or_path $MODEL_NAME --dataset_name ccdv/patent-classification --do_train --do_eval --max_seq_length $MAX_SEQ_LENGTH --per_device_train_batch_size 8 --gradient_accumulation_steps 4 --learning_rate 2e-5 --num_train_epochs 1 --max_eval_samples 500 --output_dir tmp/patent
数据集概述
数据集名称
- Patent Classification
数据集用途
- 用于长文本分类任务,特别是专利和摘要的分类。
数据集特点
- 包含9个不平衡的分类标签。
- 数据集大小介于10,000到100,000之间。
- 文档长度超过512个令牌。
数据集组成
- 包含35,000个专利和摘要。
- 分为三个部分:训练集(25,000个样本)、验证集(5,000个样本)和测试集(5,000个样本)。
数据集来源
- 数据来源于"BIGPATENT: A Large-Scale Dataset for Abstractive and Coherent Summarization.",由Eva Sharma, Chen Li和Lu Wang提供。
数据集格式
- 文档为小写且空格分隔。
兼容性
- 兼容run_glue.py脚本,使用
roberta-base模型进行处理。