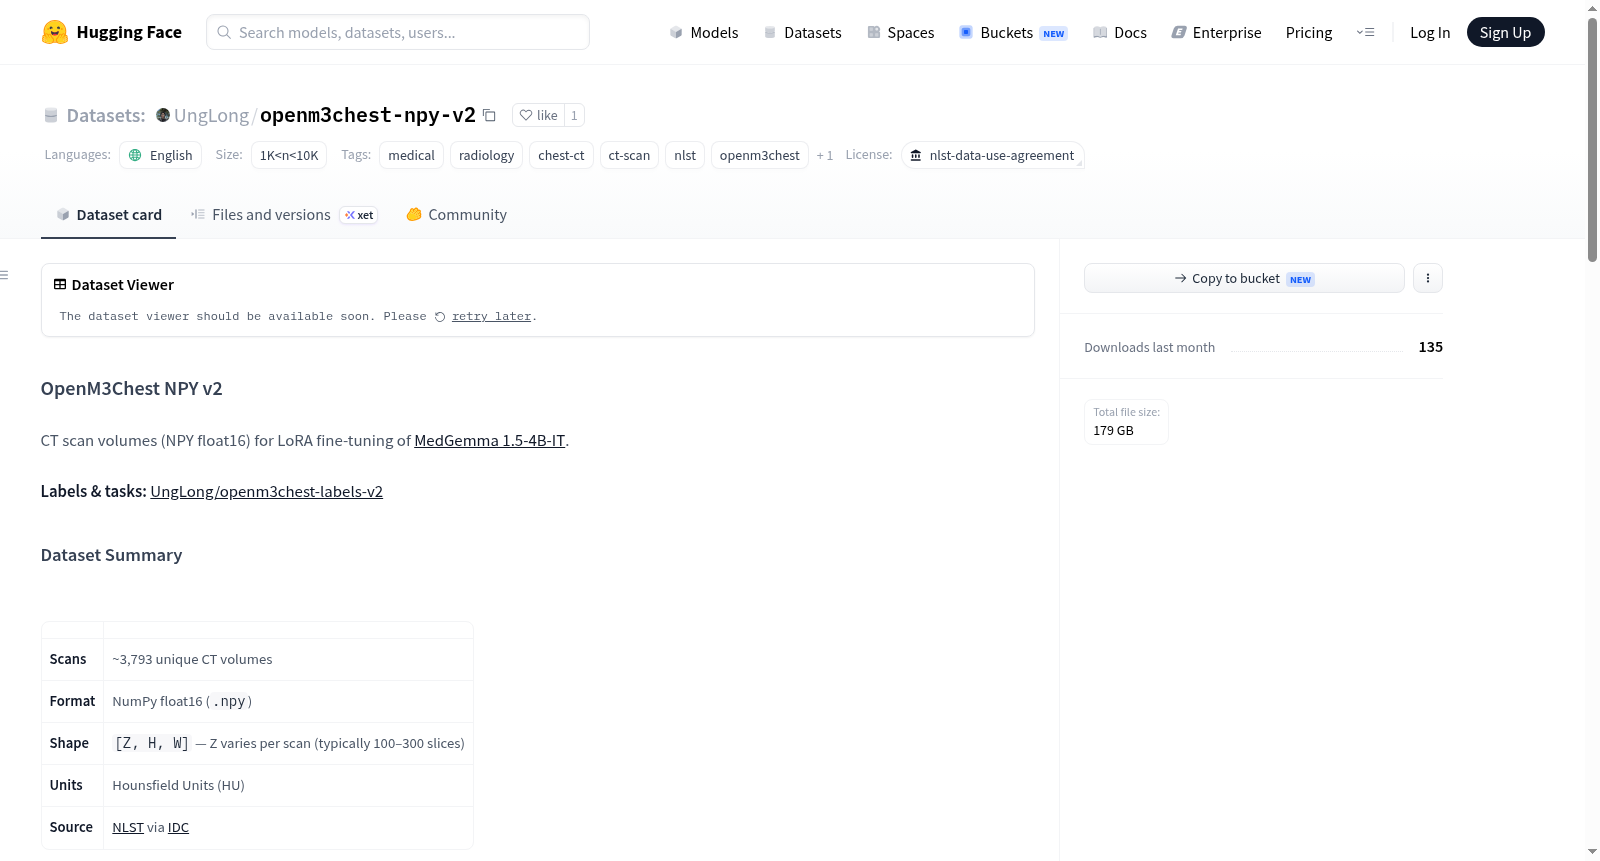
openm3chest-npy-v2
收藏资源简介:
OpenM3Chest NPY v2是一个用于医疗影像分析的数据集,专门为大型视觉语言模型MedGemma 1.5-4B-IT的LoRA(低秩适应)微调而构建。它包含从国家肺癌筛查试验(NLST)获取的胸部CT扫描数据,通过影像数据共享平台(IDC)处理得到。数据集以NumPy数组(.npy)格式存储,数据类型为float16,数值单位为亨氏单位(HU)。每个样本代表一个完整的CT扫描体积,形状为[Z, H, W],其中Z轴(切片数量)因扫描而异,通常在100到300片之间。数据集规模约为3,793个独立的CT体积,文件按照`{患者ID}/{序列实例UID}.npy`的层级结构组织。主要应用于胸部CT的放射学分析,支持的任务流程包括:第一步进行胸部异常筛查和结节存在性检测;若检测到结节,则进一步分析其位置、衰减特性、边缘特征和大小。数据预处理包含将单张CT切片转换为RGB图像的关键步骤,采用三个特定的HU窗位(分别针对骨骼/肺、软组织以及脑部组织)进行融合,以满足模型输入要求。数据集的标签(如结节存在性、属性等)存储在一个独立的关联数据集中。
OpenM3Chest NPY v2 is a dataset for medical image analysis, specifically built for LoRA (Low-Rank Adaptation) fine-tuning of the large vision-language model MedGemma 1.5-4B-IT. It contains chest CT scan data obtained from the National Lung Screening Trial (NLST) and processed via the Imaging Data Commons (IDC). The dataset is stored in NumPy array (.npy) format with data type float16 and values in Hounsfield Units (HU). Each sample represents a complete CT scan volume with shape [Z, H, W], where the Z-axis (number of slices) varies per scan, typically between 100 and 300 slices. The dataset comprises approximately 3,793 independent CT volumes, organized in a hierarchical file structure as `{patient ID}/{series instance UID}.npy`. Its primary application is radiological analysis of chest CT scans, supporting a task workflow that includes: first, screening for chest abnormalities and detecting nodule presence; if nodules are detected, further analyzing their location, attenuation characteristics, margin features, and size. Data preprocessing involves a key step of converting single CT slices into RGB images by fusing three specific HU window settings (for bone/lung, soft tissue, and brain tissue) to meet model input requirements. Labels for the dataset (such as nodule presence and attributes) are stored in a separate associated dataset.
数据集概述:OpenM3Chest NPY v2
该数据集是一个专为医学影像任务设计的CT扫描体积数据集,主要用于对MedGemma 1.5-4B-IT模型进行LoRA微调。
- 数据集名称:OpenM3Chest NPY v2 (pretty_name)
- 语言:英语 (en)
- 许可证:其他 (other),具体依据为 NLST Data Use Agreement (PDF链接)
- 数据规模:1K < n < 10K
- 标签和任务:关联标签数据集位于 UngLong/openm3chest-labels-v2
数据内容与格式
- 扫描数量:约 3,793 个独特的CT体积。
- 数据格式:NumPy float16 (
.npy) 文件。 - 数据形状:
[Z, H, W],其中Z轴(切片数量)因扫描而异,通常在100到300层之间。 - 数据单位:亨氏单位 (Hounsfield Units, HU)。
- 数据来源:数据源自 NLST(国家肺部筛查试验),通过 IDC(影像数据共享平台)获取。
- 原数据集为 OpenM3Chest
- 原始DICOM文件可通过 IDC (Imaging Data Commons) 获取。
文件结构
文件按照 {PatientID}/{SeriesInstanceUID}.npy 的路径组织。例如:118553/1.2.840.113654.2.55.100014252814244258018667405625953775316.npy。
加载与使用
- 加载体积数据:可使用
huggingface_hub库的hf_hub_download函数,通过指定患者ID和序列UID来下载特定的.npy文件,然后使用numpy.load()加载。 - 加载标签数据:可通过
datasets库加载标签数据集(如nodule_presence),并将标签中的ID信息与NPY文件路径结合,实现数据与标签的联合加载。 - 预处理(针对MedGemma 1.5):提供了将单张CT切片(HU值)转换为RGB图像的示例代码。该方法使用三个不同的HU窗口(骨/肺、软组织、脑)进行映射并堆叠,适用于模型的推理。
任务与使用流程(放射学顺序推理)
该数据集设计了一个分步推理流程:
- 筛查步骤:使用
chest_abn_54–61和nodule_presence标签,判断是否存在异常或结节。 - 结节分析步骤:如果存在结节,则进一步分析结节的 位置、衰减、边缘 和 大小。