CUBE-MT
收藏资源简介:
CUBE-MT(文化多模态基准)是一个用于多模态知识图谱构建的文化基准数据集,它包含了来自巴西、法国、印度、意大利、日本、尼日利亚、土耳其和美国的8个国家,以及饮食、地标和艺术等3个领域的300K个文化 artifact。数据集还包括了1000个用于评估生成AI模型文化意识的文本到图像生成提示。CUBE-MT扩展了原有的CUBE数据集,支持文本、盲文、语音、音乐、视频和3D等多种模态,并使用公共可用的Hugging Face模型生成了相应的多模态数据实例。
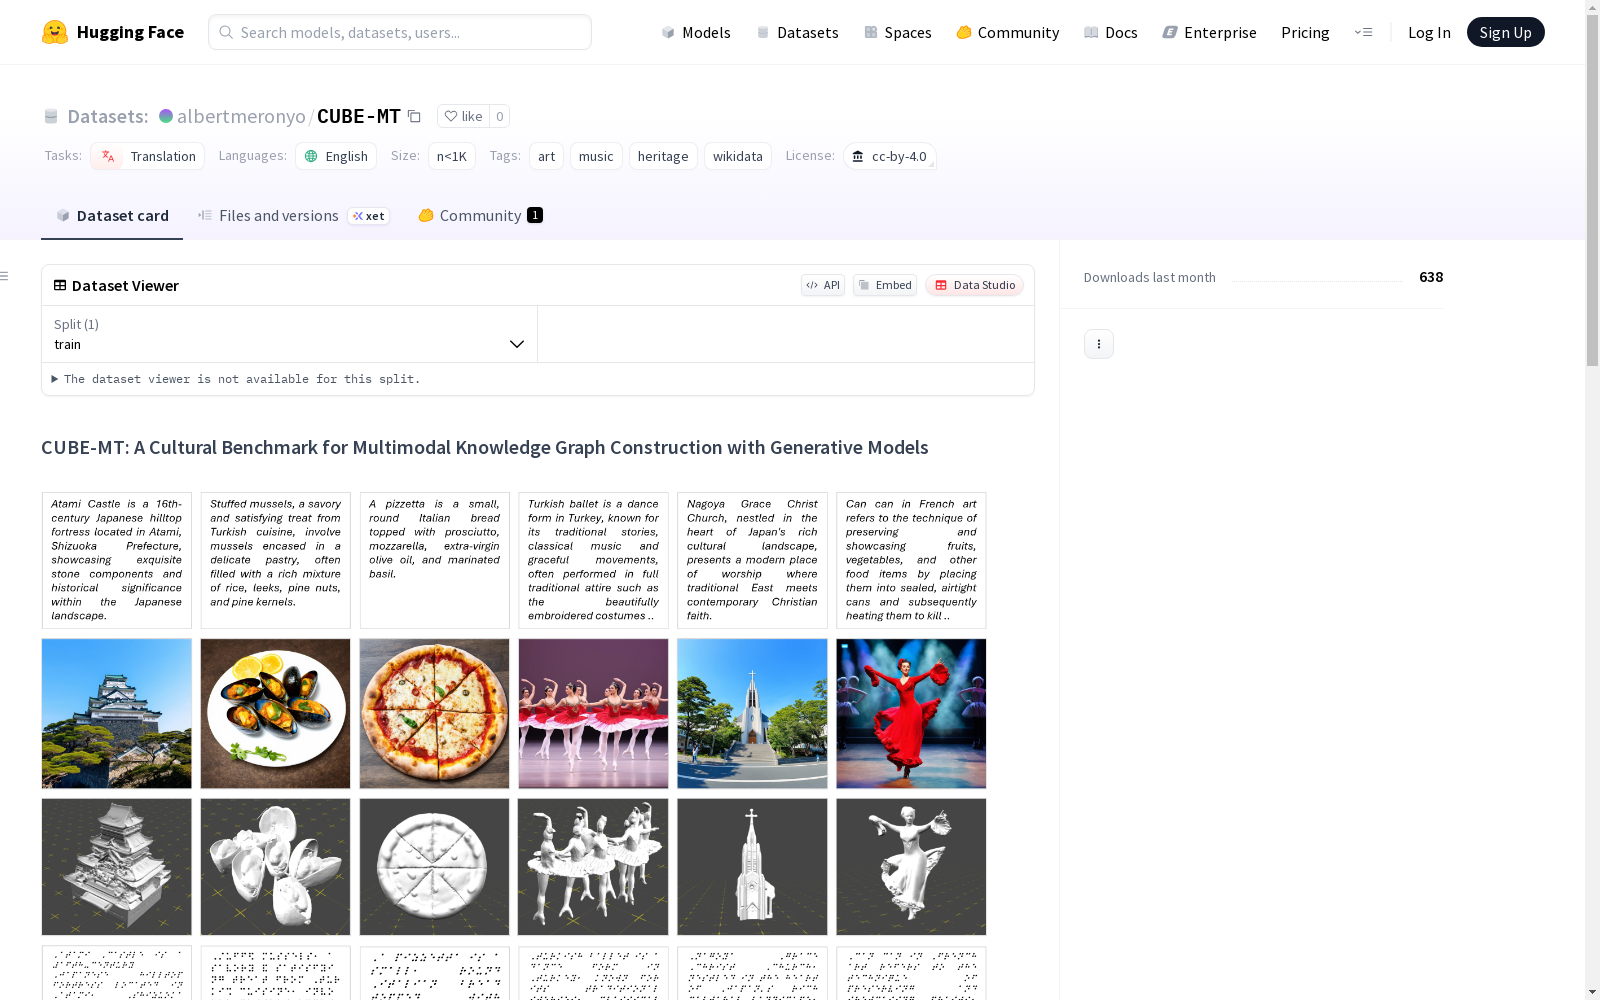
CUBE-MT (Cultural Multimodal Benchmark) is a cultural benchmark dataset for multimodal knowledge graph construction. It encompasses 300,000 cultural artifacts spanning 8 countries: Brazil, France, India, Italy, Japan, Nigeria, Turkey, and the United States, across three domains including diet, landmarks, and art. The dataset also includes 1,000 text-to-image generation prompts developed to evaluate the cultural awareness of generative AI models. CUBE-MT extends the original CUBE dataset, supporting diverse modalities such as text, Braille, speech, music, video, and 3D, and generates corresponding multimodal data instances using publicly available Hugging Face models.
CUBE-MT数据集概述
基本信息
- 许可证: CC-BY-4.0
- 任务类别: 翻译 (translation)
- 语言: 英语 (en)
- 标签: 艺术 (art)、音乐 (music)、文化遗产 (heritage)、Wikidata (wikidata)
- 数据集名称: CUBE-MT: A Cultural Benchmark for Multimodal Knowledge Graph Construction with Generative AI
- 数据规模: 小于1K (n<1K)
数据集描述
CUBE-MT是CUltural BEnchmark for Text-to-Image models (CUBE)的扩展版本,旨在评估生成式AI模型的文化意识。CUBE包含来自8个国家(巴西、法国、印度、意大利、日本、尼日利亚、土耳其和美国)和3个领域(美食、地标、艺术)的30万件文化艺术品,以及1K个文本到图像生成提示。
扩展内容
- 多模态支持: 扩展至6种模态,包括文本、盲文、语音、音乐、视频和3D。
- 提示扩展: 扩展提示以评估生成这些模态的文化意识。
- 基准测试: 使用Hugging Face公开模型(如Stable Diffusion、Phi3、FastSpeech、MusicGen)生成模态实例。
数据集组成
- 元数据文件: CUBE-MT.json
- 数据转储: 数据转储链接
- Parquet版本:
refs/convert/parquet分支
使用基准
- 主文件: mt.ipynb包含用于每种模态的模型变量,可替换为其他模型。
- 支持的模型: Hugging Face上托管的模型,包括:
文档
- Wiki: CUBE-MT Wiki
引用
bibtex @misc{merono2025cubemt, title={{CUBE-MT: A Cultural Benchmark for Multimodal Knowledge Graph Construction with Generative Models}}, author={Albert Meroño-Peñuela and Nitisha Jain and Filip BIrcanin and Timothy Neate}, year={2025}, url={doi:10.5281/zenodo.15398577}, }