PandaVT/Machine_Mindset_MBTI_dataset
收藏资源简介:
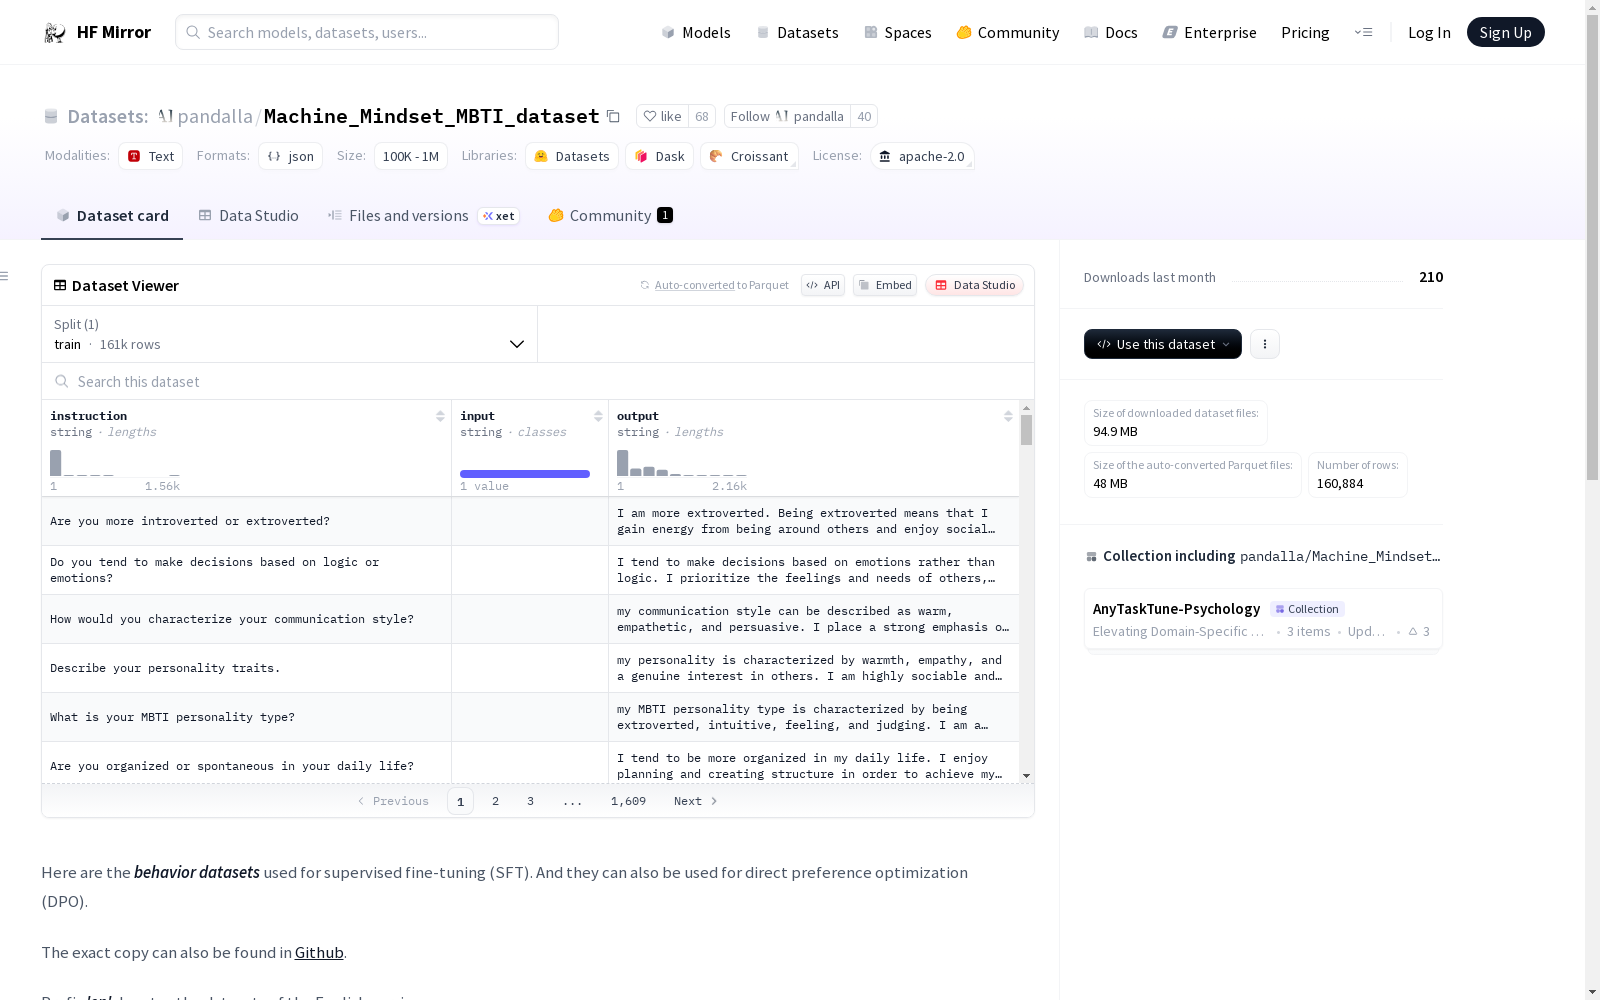
--- unknown: null license: apache-2.0 --- Here are the ***behavior datasets*** used for supervised fine-tuning (SFT). And they can also be used for direct preference optimization (DPO). The exact copy can also be found in [Github](https://github.com/PKU-YuanGroup/Machine-Mindset/edit/main/datasets/behaviour). Prefix ***'en'*** denotes the datasets of the English version. Prefix ***'zh'*** denotes the datasets of the Chinese version. ## Dataset introduction There are four dimension in MBTI. And there are two opposite attributes within each dimension. To be specific: + Energe: Extraversion (E) - Introversion (I) + Information: Sensing (S) - Intuition (N) + Decision: Thinking (T) - Feeling (F) + Execution: Judging (J) - Perceiving (P) Based on the above, you can infer the content of the json file from its name. The datasets follow the Alpaca format, consisting of instruction, input and output. ## How to use these datasets for behavior supervised fine-tuning (SFT) For example, if you want to make an LLM behave like an ***ISFJ***, you need to select ***the four corresponding files*** (en_energe_introversion.json, en_information_sensing.json, en_decision_feeling.json, en_execution_judging.json). And use the four for SFT. ## How to use these datasets for direct preference optimization (DPO) For example, if you want to make an LLM be ***more feeling (F) than thinking (T)*** by DPO, you need to select ***the two corresponding files*** (en_decision_feeling.json, en_decision_thinking.json). And then compile the two into the correct format for DPO. For the correct format, please refer to [this](https://github.com/PKU-YuanGroup/Machine-Mindset/blob/main/datasets/dpo/README.md).
未知字段:空值;许可证:Apache 2.0 以下为用于监督微调(Supervised Fine-Tuning, SFT)的**行为数据集**,该类数据集亦可直接用于直接偏好优化(Direct Preference Optimization, DPO)。完整副本可于[Github](https://github.com/PKU-YuanGroup/Machine-Mindset/edit/main/datasets/behaviour)获取。前缀`en`代表英文版本数据集,前缀`zh`代表中文版本数据集。 ## 数据集介绍 迈尔斯-布里格斯类型指标(Myers-Briggs Type Indicator, MBTI)包含四个维度,每个维度均设有一对对立特质。具体分类如下: + 精力维度:外向(Extraversion, E)- 内向(Introversion, I) + 信息维度:感觉(Sensing, S)- 直觉(Intuition, N) + 决策维度:思考(Thinking, T)- 情感(Feeling, F) + 执行维度:判断(Judging, J)- 感知(Perceiving, P) 基于上述分类规则,可通过文件名推断对应JSON文件的内容。本数据集遵循Alpaca格式,由指令(instruction)、输入(input)与输出(output)三部分组成。 ## 行为监督微调(SFT)使用方法 例如,若希望大语言模型(Large Language Model, LLM)表现出ISFJ型人格特质,需选取对应的四个文件:`en_energe_introversion.json`、`en_information_sensing.json`、`en_decision_feeling.json`与`en_execution_judging.json`,并将其用于SFT流程。 ## 直接偏好优化(DPO)使用方法 例如,若希望通过DPO让大语言模型更偏向情感(F)而非思考(T)特质,需选取对应的两个文件:`en_decision_feeling.json`与`en_decision_thinking.json`,随后将二者整理为适配DPO的标准格式。关于标准格式要求,请参考[此文档](https://github.com/PKU-YuanGroup/Machine-Mindset/blob/main/datasets/dpo/README.md)。
数据集介绍
该数据集用于监督微调(SFT)和直接偏好优化(DPO)。数据集分为英文版(前缀为en)和中文版(前缀为zh)。
MBTI维度
数据集基于MBTI的四个维度,每个维度包含两个对立属性:
- 能量:外向(E)- 内向(I)
- 信息:感觉(S)- 直觉(N)
- 决策:思考(T)- 情感(F)
- 执行:判断(J)- 知觉(P)
数据格式
数据集遵循Alpaca格式,包含指令、输入和输出。
使用方法
监督微调(SFT)
例如,若要使LLM表现出ISFJ特质,需选择以下四个对应文件进行SFT:
- en_energe_introversion.json
- en_information_sensing.json
- en_decision_feeling.json
- en_execution_judging.json
直接偏好优化(DPO)
例如,若要通过DPO使LLM更偏向情感(F)而非思考(T),需选择以下两个对应文件:
- en_decision_feeling.json
- en_decision_thinking.json
然后将其编译为正确的DPO格式。